1. Introduction
Donald Trump’s return to the United States´(US) government has empowered high-tech companies in unprecedented ways. The most influential technology companies — known as GAFAM (Google, Amazon, Facebook [now Meta], Apple and Microsoft) — have acquired an unparalleled level of economic and political power. In 2020, these five companies’ combined market capitalisation reached $5.35 trillion — exceeding the combined Gross Domestic Product of countries such as Japan, Germany, India and the United Kingdom (IG, 2021; Worldometer, 2023). These figures illustrate not only the magnitude of their dominance in the global market, but also the difficulties that governments face in regulating their activities.
In late 2025, the European Union imposed sanctions on the platform X for alleged non-compliance with its regulatory obligations under EU digital governance frameworks, a move that was followed by public statements from Donald Trump threatening the imposition of trade tariffs should the EU continue to challenge U.S.-based technology companies (Reuters, 2025). Against this backdrop, disputes over platforms governance intersect with geopolitical and economic pressures, fueling broader regulation tensions.
Announcements about content moderation policies have consequences that transcend the political and social spheres, as illustrated by Mark Zuckerberg’s 2025 announcement changing Meta’s content-moderation policy in US, replacing the IFCN-certified fact-checking system with a community-notes model. Around 60% of Internet users — approximately 3.2 million people — are active on at least one Meta platform, including WhatsApp, Facebook, Instagram, Messenger and Threads (Rogan, 2025). Therefore, this announcement is not just a business decision.
The United States is increasingly embracing a path toward deregulation. One of the arguments in favor of this shift is the assertion that content moderation practices enforced by verification agencies on social media platforms infringe upon citizens’ fundamental right to freedom of expression. Critics contend that these agencies may function as instruments of censorship, selectively determining which voices and opinions are permissible in the public discourse (Adam, 2025). This issue becomes even more complex when considering the role of social media in various political systems.
In hybrid regimes or dictatorships, governments often manipulate social media channels to suppress dissenting views and control the narrative, effectively using these platforms as tools for censorship. However, it is important to note that, despite the prevalence of such practices in authoritarian contexts, there is a lack of empirical evidence suggesting that similar practices are being employed in democratic systems.
Indeed, entities like the European Union are worried about finding the right equilibrium between ensuring a secure online space and protecting individual freedoms. Efforts are underway to address both illegal content, which includes the promotion of terrorism, child exploitation, and threats to national security, as well as legal yet harmful content, such as disinformation, conspiracy theories, and polarization, all while upholding proportionality in relation to the defense of the right to freedom of expression (Kalliris, 2024).
This study analyses how leading media outlets in Spain, the US and Turkey reacted on platform X to Meta’s change in content-moderation policy, and examines how users responded to these posts.
1.1 Digital governance, platform governance, and public discourse in social media
Digital governance refers to the institutional design required to govern digital technologies, stressing governance mechanisms that manage risks and enhance public well-being (Filgueiras and Almeida, 2021). Models of digital governance range from centralised approaches to more decentralised or libertarian schemes, where the private sector shapes the digital ecosystem. Thus, there is a certain consensus on identifying at least three models of governance (O’Hara & Hall, 2018; Rone, 2021): the Chinese or authoritarian model; the Californian or Silicon Valley open internet model, and the European co-regulation or Brussels bourgeois model.
The Chinese model is characterised by pragmatism, state centralism, and a preventive policy. According to Cuihong and Liting, China is characterised by the implementation of strict regulations to mitigate social and cybersecurity risks, such as the enforcement of licences for online services, the use of automated filters and content censorship through the use of keywords. However, the internet is seen as a fundamental tool for economic development. The government exerts near-total control over the network, yet internet users, companies and social organisations work together under its directives to achieve more effective governance (2021).
In contrast, the Californian model gives companies enormous leeway to develop their business, even if this infringes individual rights such as data protection. This model is based on the idea of “move fast and break things — innovate until the innovation is shown to be harmful” (O’Hara & Hall, 2018: 6). This model facilitates the formulation of flexible and dynamic policies, allowing for a rapid response to technological advances and market demands (Henton, 2001). The adoption of the “Internet freedom” policy by the US State Department as a soft power strategy involved the active participation of Silicon Valley companies, who promoted the principles of an open internet while aligning themselves with the government’s interests in preserving US leadership in digital governance (Baykürt, 2022).
For its part, the European Union seeks to develop its own regulatory model based on multistakeholder governance and co-regulation, in which public institutions collaborate with relevant stakeholders in the design and implementation of policies that directly affect them. The EU does not fully trust market self-regulation, often considering it to be disruptive and a source of social costs. Although critics argue that this model suffers from excessive and sometimes contradictory regulations, which prevent it from being effective and competitive (Bauer, 2023), regulatory intervention is considered the way to achieve balanced agreements (O’Hara & Hall, 2018).
Within the broader framework of digital governance, the concept of platform governance has gained importance in the last decade. According to Luna-Reyes: “The first set of applications that challenge traditional governance mechanisms and information flows in society are social media private platfoms (2017: 199). Gorwa (2019) characterizes the platform governance concept as the layered governance relationships that link platform practices, policies, affordances, and external political forces. This interaction produces asymmetric power relations, particularly when large platforms operate transnationally across diverse political regimes, adapting their governance practices to different regulatory and institutional contexts. “Social media platforms are also private companies that are actively looking for ways to monetize user activity, mostly through marketing. In this way, all public conversations on these platforms are mediated by algorithms and rules designed to maximize the company’s profit rather than benefit the society” (Luna-Reyes, 2017: 200).
Concerns such as disinformation, content moderation, algorithmic transparency, and the protection of freedom of expression are central to debates on platform regulation due to their impact on society. Bradshaw and Howard (2019) describe how organised manipulation on social media has shaped a “global order of disinformation”, in which state and non-state actors deploy large-scale computational propaganda strategies. These findings provide a basis for understanding how governments and political parties use armies of automated accounts and trolls for electoral purposes and to control public discourse. According to Badillo et al.: “Although it may seem paradoxical, political systems with greater freedom of expression are also more vulnerable than autocracies or dictatorships to disinformation campaigns because they benefit from the free circulation of information, one of the cornerstones of democratic systems” (2023: 54).
Phillips and Milner (2021) provide a framework for interpreting polarisation and conspiracy theories, demonstrating how digital environments can reinforce the dynamics of otherness and discursive radicalisation. In the Turkish context, Saka (2018) describes the activities of ‘AKtrolls’, revealing how fake identities and automated profiles are systematically employed by government-aligned individuals to influence public discourse. These contributions are particularly relevant to the study of public discourse on platforms such as X (formerly Twitter), as they enable the issue of content moderation to be addressed as one of the main features of digital public spaces, insofar as it defines the boundaries of truthfulness and the circulation of extremist content, as well as the scope for expression in platform-mediated environments.
1.2 Content moderation on social media platforms
According to Gomes and Sultan, “content moderation is a key quality regulation of online spaces; it is the main mechanism through which social media platforms examine content against their terms of services and community guidelines to determine its suitability” (2024: 2). Social media platforms typically use hybrid moderation systems that combine Artificial Intelligence (AI) and human oversight to manage content. These systems use technologies such as Natural Language Processing (NLP) and Convolutional Neural Networks (CNN) to detect harmful content, such as hate speech and misinformation (Nehe et al., 2024; Govindankutty & Kumar, 2024).
As technologies advance, Large Language Models (LLMs) are being implemented that can learn to identify harmful content more effectively than traditional methods from very few training examples (Bonagiri et al., 2025). However, these systems suffer from problems related to the quality of training datasets and bias (Car, 2025). This is why platforms have incorporated IFCN-certified fact-checkers into their content moderation departments1.
Recently, there has been a trend among digital platforms to view content moderation as a potential threat to freedom of expression (Gosztonyi et al., 2025) resulting in their deregulation. In the United States, Meta and X have replaced the use of independent fact-checkers with community notes system, which allow users to comment on the accuracy of posts. However, studies have shown that relaxing X’s moderation policies has increased hate speech and the formation of polarised communities (Arun et al., 2024).
In non-democratic countries, governments control the content circulating on networks using measures such as word filters. But, on the other hand, by delegating this control to platforms, “there are no guarantees that these providers will be motivated by the benevolence” (Kalliris, 2024: 413). Sánchez Muñoz therefore proposes various measures to protect freedom of expression in content moderation. These include clearly defining the harms to be prevented based on evidence, ensuring transparency in the process to enable assessment of its impact, guaranteeing the right of appeal for authors of deleted content, and mitigating the risks of excessive automation through human supervision (Sánchez Muñoz, 2020: 120). A study by the University of Oxford and the Technical University of Munich found that most respondents would prefer a social media platform that prevents the spread of hate and disinformation, even if it means sacrificing absolute freedom of expression (Zilinsky et al., 2025).
In discussions surrounding the regulatory landscape of social media, authors like Kohl (2024) have raised concerns regarding the immunity that social media platforms hold within the European Union. This immunity is troubling given their sophisticated algorithmic recommendation systems. Rather than functioning as mere conduits for information, these platforms are proactive architects of the digital environment, influencing what users see, engage with, and ultimately believe (Gillespie, 2018). The business models underpinning these social media giants are intricately tied to the proliferation of disinformation, echo chambers, and societal polarization (Bakshy et al., 2015; Lazer et al., 2018; Pariser, 2012). By prioritizing user engagement and maximizing profits, social media platforms employ algorithms that curate personalized content based on individual users’ preferences. This targeted approach not only keeps users engaged for longer periods but also reinforces existing biases.
1.3 Media system in Spain, Turkey and US
Numerous studies have demonstrated the relationship between a country’s political and media systems. For example, it has been shown that in countries with higher levels of democracy, the media operate with greater freedom (Herman & Chomsky, 1988; Hallin et al., 2008). Spain, US, and Turkey represent three countries with different political systems and media landscapes. While the former two are considered democratic states, Turkey is not recognised as a fully free country due to its government’s authoritarian drift in recent years (Freedom House, 2024).
The Eurasian country is classified as a flawed democracy or hybrid regime. Around 90% of traditional media outlets, including newspapers, radio and television, support the government’s ideology (Reporters Without Borders, 2024). “The government is similarly taking advantage of the potential of social media, employing a dual strategy of communication and mobilisation. (…) A twofold strategy aimed at circulating fictional or misleading political narratives and systematically harassing the regime’s opponents”(De Cosentino & Alikasifoglu, 2019: 93). Although digital media outlets have more diverse editorial lines, access to press accreditation is controlled by a government-dependent body that issues press cards (BBC News Türkçe, 2022). Consequently, digital media journalists may face restrictions on their accreditation if their publications are overly critical.
Spain, for its part, falls within what Hallin and Mancini (2008) call the Polarised Pluralist System: a media model characterised by low newspaper circulation, limited professionalisation of journalism, strong political alignments, and marked state interventionism. This manifests in the regulation of media structure and ownership, as well as the control and management of public media (Hallin & Mancini, 2008; Seijas Costa et al., 2024; Serrano Puche, 2017).
The 2008 debt crisis had a significant impact on Spanish media conglomerates, resulting in widespread job losses, reduced staff numbers, and deteriorating working conditions for professionals (García Madariaga & Arasanz Esteban, 2019). This crisis-stricken context led to structural changes in the industry, encouraging the adoption of digitalisation and new forms of information production (García-Santamaría & Pérez-Serrano, 2020). Polarisation is another distinctive feature of the Spanish media system. Ideological alignment between the media and political parties means that the tension of political debate is transferred to the media.
The relaxation of moderation policies on social media platforms like X has prompted Spanish news outlets, such as La Vanguardia, to depart from this social network. Despite being selected as a source of information by 16% of the population (Newman et al., 2024), X has become a platform rife with polarisation, disinformation, and the spread of hate speech (Majó-Vázquez & González-Bailón, 2022; Reuters, 2024).
Finally, the United States is classified within the Liberal or North Atlantic model. The US media system is characterised by a high degree of liberalism and market-driven ownership. This approach has its roots in the First Amendment, which implicitly protects freedom of expression and limits government intervention in the media’s operations.
However, the main criticism of this model is that media plurality and diversity are not guaranteed, as libertarianism prioritises corporate rights over public interests (Pickard, 2015). The Federal Communications Commission (FCC) is a regulatory body whose objectives include ensuring diversity of channels and opinions. In addition to facing pressure from an industry that favours deregulation, this body has had to contend with several court rulings that have hindered its work (Candeub, 2008; Fukuyama & Grotto, 2020).
While the EU has implemented comprehensive digital regulations such as the General Data Protection Regulation (GDPR) to address issues such as privacy and disinformation, the US has not adopted such an interventionist approach (Fukuyama & Grotto, 2020). Figures such as Donald Trump have exploited these platforms to circumvent traditional media and communicate directly with the public, altering the dissemination and reception of political messages (Harbi, 2024).
This evolution has raised questions about the credibility and reliability of information sources and has contributed to the fragmentation of public discourse (Dickerson, 2019). Furthermore, information is often approached from a sensationalist and entertainment-focused perspective, as evidenced by the coverage of political campaigns such as Donald Trump’s in 2016 and 2024. By portraying his campaign as a spectacle rather than focusing on political issues, the media allowed him to dominate the narrative and attract his supporters (Harbi, 2024).
2. Objectives and hypotheses
The overall objective of this study is to examine media reactions on X to Meta’s shift from IFCN-certified fact-checking to a community-notes model, and to analyse how users respond to these posts in three different digital governance contexts (Spain, the US and Turkey).
To achieve this, the following Specific Objectives (SO) have been defined:
SO1: Identify and compare the main discursive tones and stance adopted by the media outlets in each country in their X posts reacting to Meta’s announcement.
SO2: Classify the predominant thematic and lexical–semantic patterns present in the media posts, highlighting cross-country differences.
SO3: To examine how user replies relate to the discursive framing of media posts across countries.
SO4. Examine how both media discourse and user-reply patterns relate to the broader regulatory frameworks of digital governance in the United States, Spain and Turkey.
Similarly, the following hypotheses (H) are proposed:
H1.
In Turkey, where government control over digital platforms is highest, media outlets will adopt a more favourable stance toward Meta’s decision to relax content moderation oversight, and user replies will show comparatively lower levels of explicit disagreement or polarization.
H2.
In Spain, where digital governance emphasises user rights and co-regulation, media outlets will express a more critical stance toward Meta’s announcement, and user replies will tend to reproduce or amplify this critical orientation.
H3.
In the United States, media reactions will reflect ideological alignment: outlets aligned with Democratic positions will be more critical, while those closer to Republican positions will show neutrality or support; user replies will mirror this partisan divide, exhibiting higher levels of polarity.
H4.
Higher polarity scores and stronger lexical–semantic differentiation will emerge in media systems characterised by greater ideological fragmentation (US), whereas more centralised or government-aligned systems (Turkey) will display lower polarity and more homogeneous semantic patterns.
3. Methodology
This research has developed a methodology that combines automated data extraction techniques, descriptive quantitative analysis, semantic analysis and qualitative content analysis. This mixed approach is supported by computational tools that allow both the discourse emitted by the media and the reactions and communicative practices of users on X (formerly Twitter) to be examined. This approach falls within the field of computational social science, which is defined as the combination of computational methods and theoretical frameworks from the social sciences to systematically study complex phenomena (Conte et al., 2012; Edelmann et al., 2020). While the volume of data is not massive, scraping techniques, automatic language processing and computational analysis of digital interactions enable a replicable approach to the subject.
The methodological process can be divided into five main phases:
(1) Selection of the sample and countries under study.
(2) Automated collection of news headlines covering Meta’s announcement as shared within X posts, using web-scraping techniques.
(3) Data processing, cleaning, and quantitative analysis, including dataset structuring and statistical metrics.
(4) Software-assisted qualitative analysis using Atlas.ti to manually code key posts from the five largest media outlets in each country, followed by co-occurrence matrix generation and heatmap-based comparative visualization.
(5) Extraction and analytical evaluation of user replies linked to the collected X posts.
(6) Lexical–semantic analysis and polarity modeling, incorporating sentiment detection and the construction of tone or polarization models.
3.1 Data selection and sample design
X was selected as the platform for analysis due because it is the social media site most used by journalists for professional purposes according to a Pew Research Center survey (Jurkowitz & Gottfried, 2022). Additionally, X’s content moderation model is similar to Meta’s proposed approach, which relies on user participation through community notes rather than exclusively on external fact-checkers.
In terms of countries, Spain, the United States, and Turkey were chosen as they represent three different models of digital governance and levels of press freedom, as well as having divergent media ecosystems. This allows for a comparative analysis of narratives and citizen replies to the change in Meta’s content moderation policies.
For each country, media outlets with the greatest digital reach were selected according to the 2024 Digital News Report, provided they had an official X account. The final sample included the following media outlets from different countries: five Spanish outlets (El País, El Mundo, 20minutos, eldiario.es and OkDiario), five American outlets (The New York Times, The Washington Post, USA Today, The Wall Street Journal and
New York Post) and five Turkish outlets (Sözcü, Habertürk,
Haberler.com
, Ensonhaber and SonDakika).
3.2 Extraction and cleaning of news headlines as shared within X posts
The data was extracted using the TweetScraperR (R) package via web scraping, with advanced searches encoded in URLs that replicate manual queries on the platform. All tweets posted by the selected official accounts since 6 January 2025 that included references to “Meta”, “Facebook”, “Instagram” or “Mark Zuckerberg”, as well as terms related to content moderation: “censorship”, “verification”, “algorithmic”, “fact-checking” were retrieved.
The obtained data underwent a cleaning process:
• removal of irrelevant columns.
• format standardisation.
• identification and removal of duplicates.
• classification by country and media.
• extraction of interaction metrics (likes, reposts and replies).
Finally, 56 headlines were obtained to form the basis of the initial descriptive and interpretative analysis.
3.3 Quantitative analysis of news headlines as shared within X posts
The statistical analysis was carried out entirely in R using the dplyr, tidyr, ggplot2 and kableExtra packages. Descriptive metrics were calculated for each country and medium, including:
• total number of publications.
• average number of replies.
• average number of reposts.
• average number of likes.
• engagement distribution.
A lexical analysis was also performed using TidyText and Text2Vec. The text underwent pre-processing (normalisation, removal of stop words, lemmatisation and translation where necessary) in order to extract bigrams and analyse patterns of semantic co-occurrence. The results enabled the dominant narratives in each country to be characterised, as well as the centrality of concepts such as “moderation”, “censorship”, “fact-checking” and references to key political figures.
3.4 Qualitative analysis of news headlines as shared within X posts
In addition to the computational approach outlined above, a phase of software-assisted qualitative analysis was conducted to identify and compare the main discursive tones and stances adopted by media outlets in each country in their posts on X reacting to Meta’s announcement. This stage adopted an inductive-interpretative logic, centring on the manual coding of the most pertinent tweets published by the five media outlets with the widest reach in each country.
Atlas.ti was used to organise and analyse the qualitative data by tone, discursive themes, and analytical codes. Co-occurrence matrices crossing countries with tone and thematic categories were generated and exported to Microsoft Excel, where they were visualised using heatmaps. To support cross-national comparison of codes, a comparative table was produced using normalised percentages (relative to each country’s total coded segments), and the most frequent non-tone codes were reported in the text. This qualitative approach captured contextual nuances and specific narratives that automated semantic analysis may overlook, adding an interpretative dimension to understanding media positioning in relation to the predominant digital governance models in each country.
3.5 Collection of replies
To analyse the public’s reception of the headlines, all replies associated with the collected posts were extracted. This process was carried out using the TweetScraperR (R) package, which provides stable access to X’s unofficial API via multiple accounts authenticated using cookies and session parameters.
The steps were as follows:
1. Extraction of the tweet identifier (tweet_id) from the URL of each publication.
2. Use of the tweet_replies() function to retrieve all replies associated with each tweet identifier.
3. Converting the data to dataframe format using to_dataframe() and consolidating it into a single dataset.
4. Integrating contextual variables from the original tweet (media, country, date and headline) into each reply.
5. Cleaning the dataset by removing empty replies, duplicates and replies without valid linguistic content.
The final dataset includes several hundred replies, which is sufficient for robust quantitative, semantic and comparative analysis.
3.6 Sentiment analysis of user replies
To examine the affective orientation of user reactions to the changes in Meta’s content moderation policy, a computational sentiment analysis was applied to user replies posted on X in response to media coverage of the announcement.
Given the multilingual nature of the corpus—comprising replies written primarily in Spanish and English, as well as a smaller number of messages in other languages—all user replies were automatically translated into English prior to sentiment analysis. This step was implemented to ensure linguistic standardization and comparability across national contexts, and to allow the application of a single high-performing sentiment classification model.
Translation was performed using a neural machine translation model based on the No Language Left Behind architecture (NLLB-200, distilled version), specifically facebook/nllb-200-distilled-600 M. This model is designed for multilingual translation and has demonstrated robust performance across a wide range of language pairs. In the present study, translation is conceptualized as a normalization procedure, aimed at preserving the general semantic content of user replies while facilitating downstream sentiment analysis.
While automatic translation may entail a partial loss of pragmatic or cultural nuance, its use is methodologically justified in comparative computational research, where consistency of linguistic input is a prerequisite for valid cross-country comparisons.
Following translation, sentiment analysis was conducted using a transformer-based model derived from RoBERTa, fine-tuned specifically for sentiment classification on social media data. The model employed was cardiffnlp/twitter-roberta-base-sentiment-latest, which has been trained on large-scale Twitter corpora and optimized to capture the linguistic characteristics of short, informal, and opinionated texts.
The model assigns each reply to one of three sentiment categories—positive, negative, or neutral—and outputs the corresponding posterior probabilities for each class. This probabilistic output enables a more nuanced analysis than categorical classification alone and supports the construction of continuous sentiment indicators.
To capture the intensity and direction of affective orientation in a more granular manner, the probabilistic outputs of the model were transformed into a continuous polarity index, defined as the difference between the predicted probability of positive sentiment and the predicted probability of negative sentiment:
This index ranges from −1 (strongly negative orientation) to +1 (strongly positive orientation), with values close to zero indicating neutral or ambivalent sentiment. Polarity scores were computed at the level of individual replies and subsequently aggregated by country and by media outlets using robust summary statistics (median and interquartile range), in order to reduce the influence of extreme values.
The quantitative sentiment analysis was applied exclusively to replies associated with media outlets from Spain and the United States. In the case of Turkey, the number of available user replies was insufficient to support statistically comparable sentiment estimates. Consequently, Turkish replies were excluded from the quantitative sentiment analysis and were examined solely through descriptive and qualitative analyses. This methodological decision reflects a commitment to analytical rigor, ensuring that each technique is applied only where the empirical structure of the data allows for reliable interpretation.
4. Analysis and results
This section presents the results derived from the computational and qualitative procedures described in the methodological framework. Each subsection corresponds to one of the study’s specific objectives. The analyses combine descriptive statistics; lexical and co-occurrence modelling; qualitative coding assisted by Atlas.ti; extraction and examination of user replies, and polarity modelling using RoBERTa.
A preliminary descriptive analysis was conducted to characterise the dataset before proceeding to the objective-specific analyses. Interaction metrics (replies, reposts and likes) were calculated using Python after scraping the posts through the academic API of platform X. Mean engagement levels were computed for the full sample: 59.49 replies, 77.61 retweets and 190.05 likes per post. Posting frequency was also extracted from the dataset. US outlets published the highest number of posts (
New York Post = 14;
Washington Post = 12), followed by El País and eldiario.es (8 each), and The Wall Street Journal (5). Turkish outlets showed lower posting frequency.
These descriptive indicators provide the baseline distribution from which the subsequent lexical, thematic and discursive analyses were computed.
4.1 Discursive tone and stance of media outlets
The tone analysis was conducted manually using an inductive coding scheme in Atlas.ti. Each post was coded according to the explicit stance expressed towards Meta’s content-moderation policy change. Posts were classified as critical or neutral. No supportive posts were identified in the corpus.
Figure 1 shows cross-national differences. In the United States, tone was evenly split between critical (n = 10) and neutral posts (n = 10). In Spain, critical posts (n = 7) were slightly fewer than neutral posts (n = 8). In Turkey, no critical posts were observed (n = 0), and all posts were coded as neutral (n = 5).
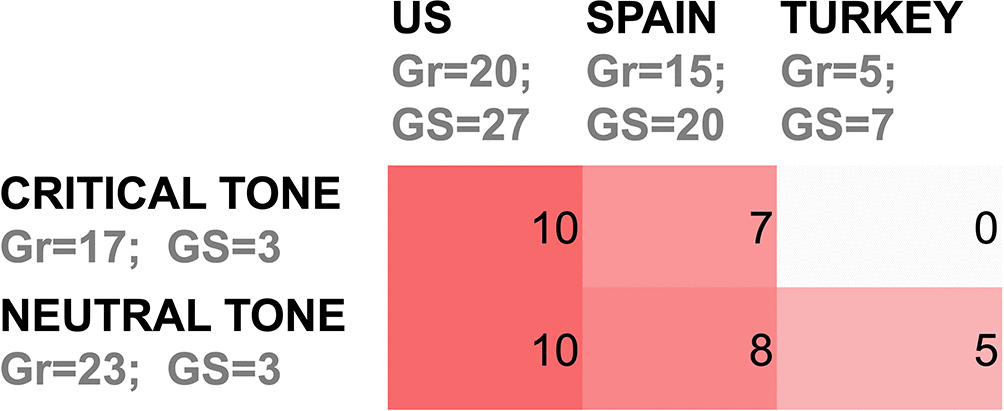
Figure 1. Heatmap of discursive tone by country.
These results derive from qualitative coding focused on evaluative markers (e.g., explicit criticism of Meta’s decision, references to censorship, …). Beyond tone, the analysis examined the distribution of discursive themes across countries. As shown in
Figure 2, themes related to political context and criticism of institutional or corporate actors were most prominent in US media coverage, moderately present in Spanish outlets, and largely absent from Turkish media, which displayed a more informative and less critical perspective.
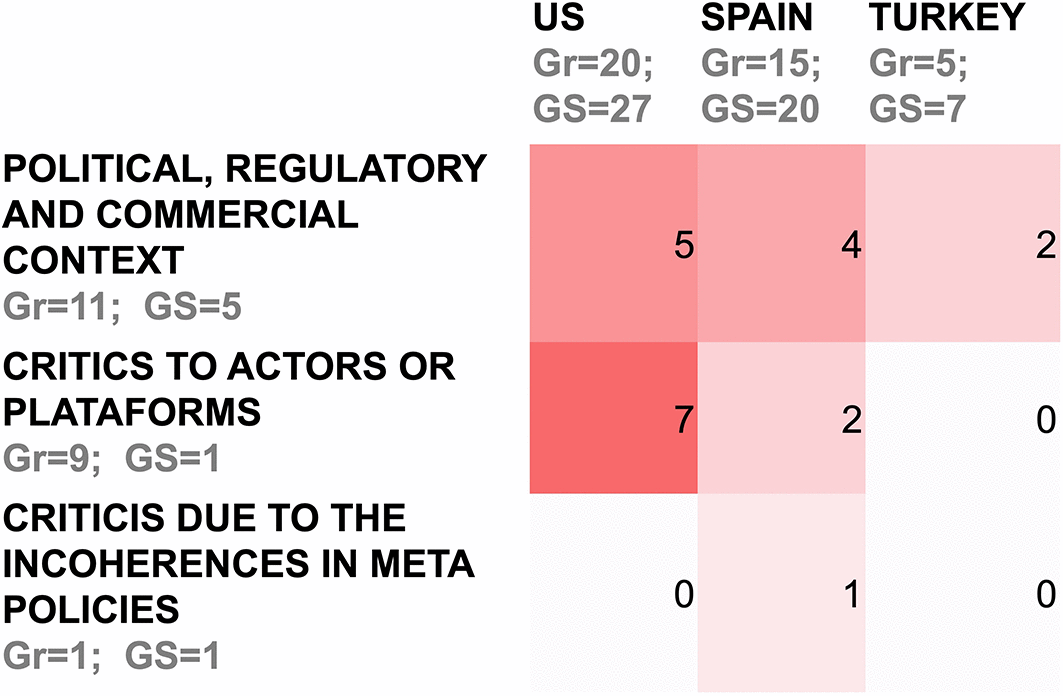
Figure 2. Heatmap of discursive themes by country.
Table 1 compares the relative prevalence of the most frequent non-tone codes across countries. In the United States, posts more often referenced changes to verification policies (16.7%) and mentioned Zuckerberg (16.7%), whereas in Spain the most salient codes within this subset were mentions of Trump (8.1%) and comparisons with X (8.1%). In Turkey, references to changes to verification policies were proportionally more frequent (23.1%) than in the US and Spain, and mentions of Zuckerberg also represented a notable share (15.4%). Criticism of Zuckerberg/Meta was present in the US (11.7%) and Spain (5.4%) but not observed in Turkey within this subset.
Table 1. Comparative distribution of discursive codes across countries.
| Código | US (%) | Spain (%) | Turkey (%) |
|---|
| Changes to verification policies | 16.7 | 8.1 | 23.1 |
| Mention of Zuckerberg | 16.7 | 0 | 15.4 |
| Criticism of Zuckerberg/Meta | 11.7 | 5.4 | 0.0 |
| Mention of Trump | 6.7 | 8.1 | 0.0 |
| Freedom of expression | 6.7 | 2.7 | 7.7 |
| Permissiveness towards hate speech, violence, etc. | 3.3 | 5.4 | 7.7 |
| Comparison with X | 1.7 | 8.1 | 0 |
4.2 Thematic and lexical–semantic patterns in media posts
Lexical frequencies, bigrams and co-occurrences were computed using Python’s NLTK and spaCy libraries. After cleaning and tokenising the corpus, frequency lists and bigram models were generated to detect dominant terms and associations. Co-occurrence matrices were computed using sliding-window methods and visualised with heatmaps. In the Turkish case, lexical analysis showed frequent use of meta, zuckerberg, facebook, mark, content and instagram. Bigrams (mark zuckerberg, facebook instagram, fact checking) were generated through Python.
In Turkey, the most frequent terms in the corpus were meta, zuckerberg, facebook, mark, content and instagram. Dominant bigrams—such as mark zuckerberg, facebook instagram and fact checking—were identified. In Spain, frequent terms included meta, verification, facebook and content. Co-occurrence patterns such as facebook instagram and content moderation, obtained through a word-window co-occurrence model. Additional bigrams, including porn ads and trump threatens, emerged through frequency-weighted bigram extraction.
As shown in
Figure 3, the most frequent lexical items in the United States were fact, meta and zuckerberg. Bigram scoring in Python identified fact checking and Mark Zuckerberg as highly recurrent combinations (see
Figure 4).
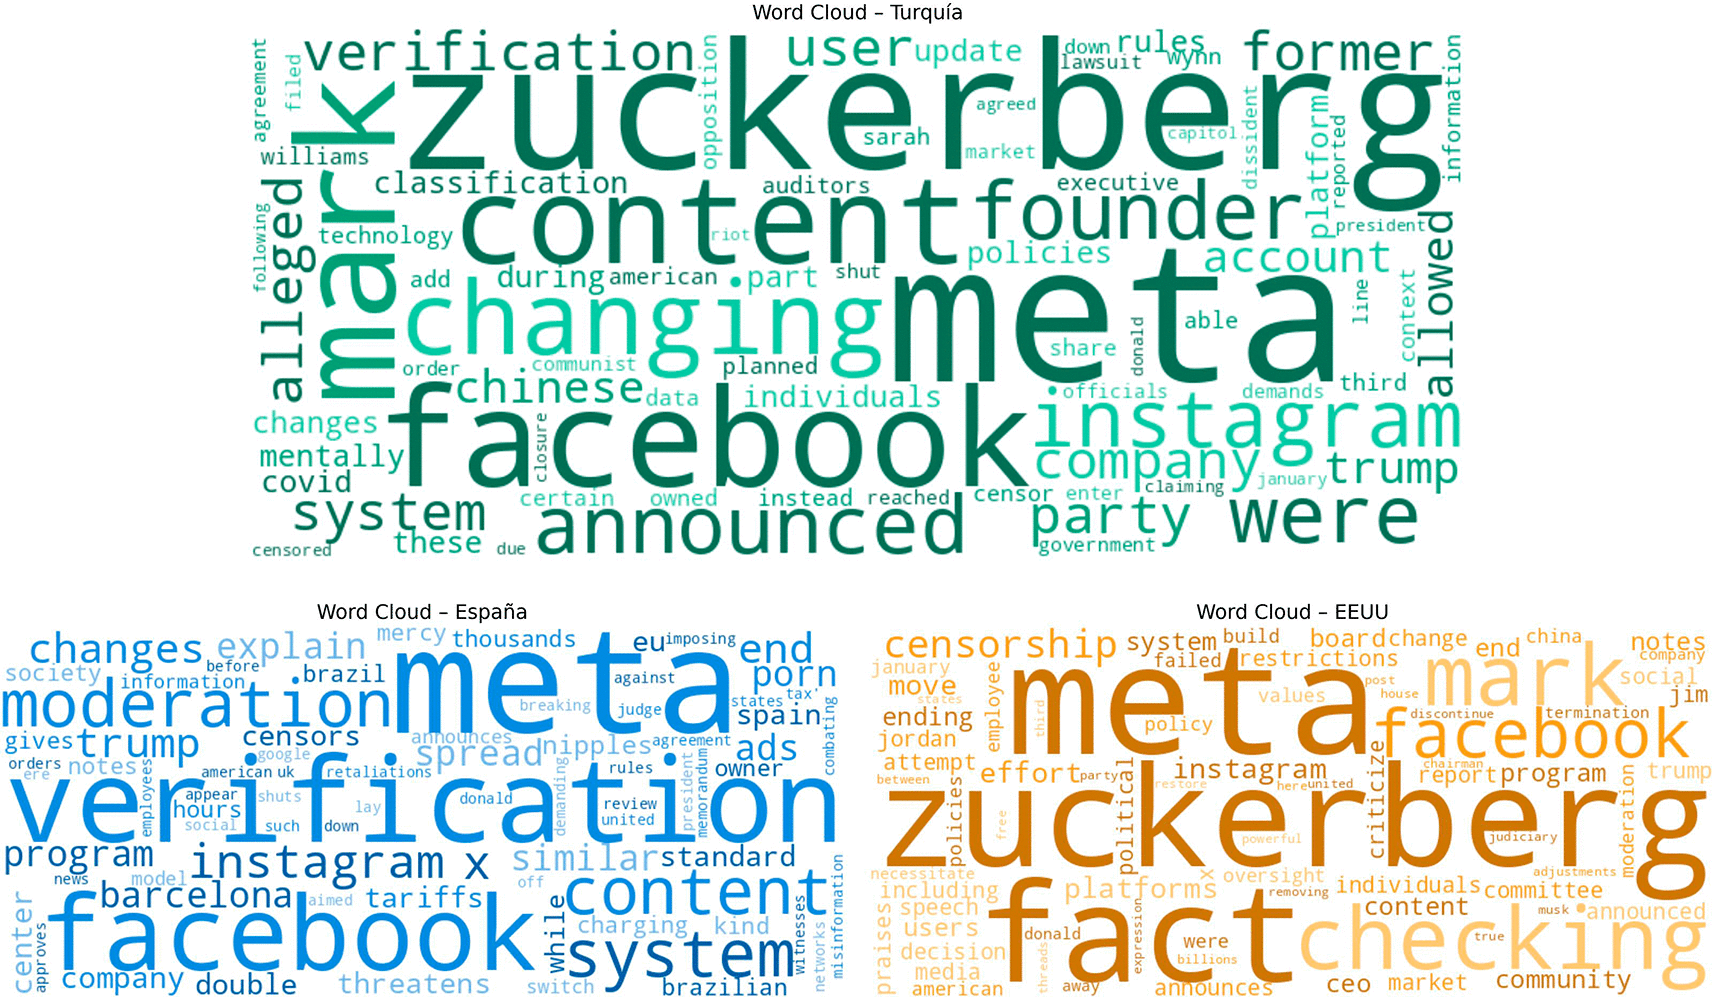
Figure 3. Word clouds of the most frequent terms by country.
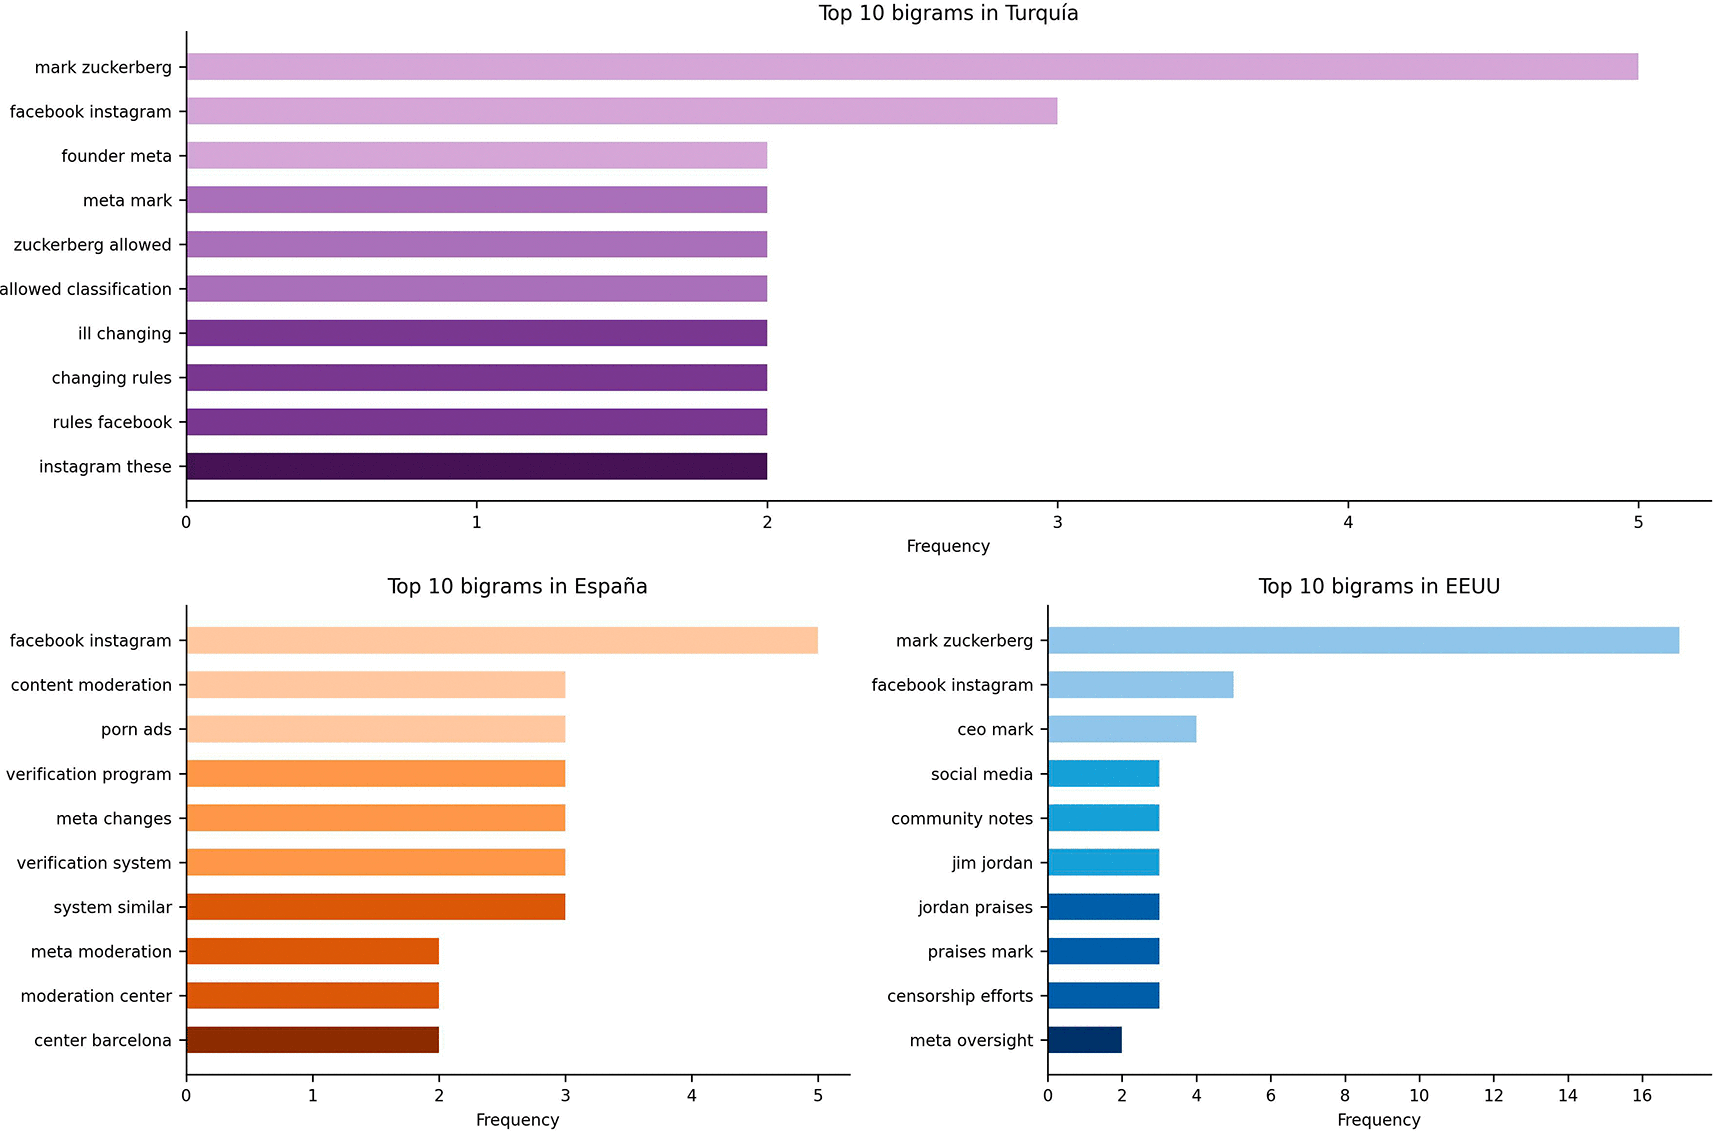
Figure 4. Top 10 bigrams by country.
4.3 Analysis of user replies and audience engagement
User replies were extracted by scraping the reply threads associated with each media post, resulting in a dataset of 1,052 responses. This dataset was cleaned and tokenised using Python, and the replies were subsequently coded inductively in Atlas.ti to identify tone and discursive frames. Tone classification followed the same criteria applied to the media posts. The results show marked cross-national differences in how audiences responded to Meta’s policy change. In the United States, replies frequently contained evaluative and critical markers, with users referencing “censorship,” “bias” or “political manipulation”. For instance, in response to a
New York Post headline announcing the end of fact-checking, one user reacted with a brief but expressive “whattt,” while others expanded the critique by asserting that Zuckerberg “helped steal the 2020 election” or that he was attempting to “get in good with the Trump Administration.”
In Spain, replies also displayed a predominantly critical orientation, combining irony, evaluative commentary and scepticism towards Meta’s governance decisions. For example, reacting to a 20 Minutos post on Meta’s decision to drop moderation policies, one user asked whether Zuckerberg intended to “liberalise female nipples or only the disgusting far-right stuff,” reframing content moderation as an issue of selective permissiveness. Another reply linked Meta’s actions to political dynamics involving Elon Musk and Donald Trump, suggesting that fears of platform sanctions influenced the decision. Similarly, a response to an El País post about Trump’s claims of censorship stated that combating disinformation merely served to “censor dissenters,” thereby reframing verification as a mechanism of ideological control. These examples demonstrate that Spanish users frequently expanded the media frame by introducing political critique and social commentary.
User replies in Turkey largely mirrored the informational and descriptive tone of media posts, showing limited engagement with the governance or censorship implications of Meta’s policy change. Most comments reiterated the information provided rather than introducing interpretative debate. Occasional reactions diverted discussion toward moral or hostile positions regarding actors mentioned in the news, but these did not constitute the dominant response pattern.
4.4 Media ecosystems and interpretative communities in shaping user sentiment
Sentiment polarity was computed after translating all replies into English and applying a transformer-based sentiment classifier. Quantitative analyses focus on Spain and the United States, as the number of replies associated with Turkish media outlets was insufficient for robust statistical modelling and is therefore addressed exclusively in the qualitative analysis.
At the aggregate level, user replies display a predominantly negative emotional orientation. As shown in
Table 2, the global mean polarity is clearly below the neutral threshold, with a negative median indicating that critical reactions dominate the conversation. The dispersion of values suggests a heterogeneous emotional response, yet consistently skewed towards negativity. These results confirm that Meta’s policy change elicited a largely critical reaction among users across the dataset as a whole.
Table 2. Descriptive statistics of user reply polarity (overall and by country).
| Group | N | Mean polarity | SD |
Median |
|---|
| Overall | 1,046 | −0.47 | 0.29 | −0.52 |
| Spain | 290 | −0.52 | 0.26 | −0.52 |
| United States | 756 | −0.56 | 0.25 | −0.56 |
When disaggregated by country, both Spain and the United States exhibit very similar patterns of reply polarity. As reported in
Table 2, average polarity values in both countries remain strongly negative, with only minor differences in central tendency and dispersion. Formal statistical tests indicate that these differences do not reach statistical significance, suggesting that the affective tone of user reactions does not vary substantially between the two national contexts. Despite differences in media systems and regulatory traditions, the emotional response to Meta’s content moderation changes appears broadly comparable in Spain and the United States. This finding indicates that national context alone is insufficient to explain variation in user sentiment and points to the relevance of other structural factors in shaping audience reactions.
Additional analyses examined whether the emotional tone of media headlines influenced the polarity of user replies. As reported in
Table 3 correlation analyses and regression-based robustness checks consistently show no statistically significant relationship between headline polarity and the polarity of replies. This result suggests that more negative or more positive headlines do not systematically generate correspondingly negative or positive audience reactions. Instead, user sentiment appears to be driven by factors beyond the immediate emotional framing of individual posts. The absence of a headline-level effect reinforces the need to consider broader contextual dynamics when analysing audience responses to platform governance debates.
Table 3. Statistical tests on user reply polarity.
| Comparison | Test | Statistic | df | p-value
| Result |
|---|
| Reply polarity × Country | Mann–Whitney U | — | — | > .05 | Not significant |
| Reply polarity × Headline polarity | Pearson r | −0.01 | — | .91 | Not significant |
| Reply polarity × Media outlet | χ2 | 77.31 | 24 | < .001 | Significant |
In contrast to the lack of significant differences by country or headline polarity, clear and statistically significant variation emerges at the media outlet level. Descriptive statistics by outlet, reported in
Table 4, reveal substantial differences in the mean polarity of user replies. While all outlets receive predominantly negative responses, the intensity of negativity varies markedly across media, ranging from near-neutral averages to strongly negative patterns.
Table 4. Mean polarity of user replies by media outlet (N ≥ 5).
| Media outlet | Country | N | Mean polarity |
SD |
|---|
| @wsj | United States | 57 | −0.11 | 0.24 |
| @elmundoes | Spain | 24 | −0.18 | 0.30 |
| @nytimes | United States | 36 | −0.36 | 0.28 |
| @el_pais | Spain | 237 | −0.40 | 0.18 |
| @eldiarioes | Spain | 27 | −0.42 | 0.31 |
| @nypost | United States | 434 | −0.48 | 0.14 |
| @washingtonpost | United States | 229 | −0.50 | 0.13 |
A chi-square test of independence confirms a significant association between reply polarity category and media outlet (χ2 = 77.31, df = 24, p < .001), indicating that user reactions are not randomly distributed across outlets. Instead, specific media accounts systematically attract more negative or more moderate responses. These differences are visualised in
Figure 5, which plots the mean polarity of user replies for each media outlet.
Figure 5 shows a clear clustering of outlets according to the intensity of negative sentiment, highlighting the role of outlet-specific dynamics in structuring audience reactions.
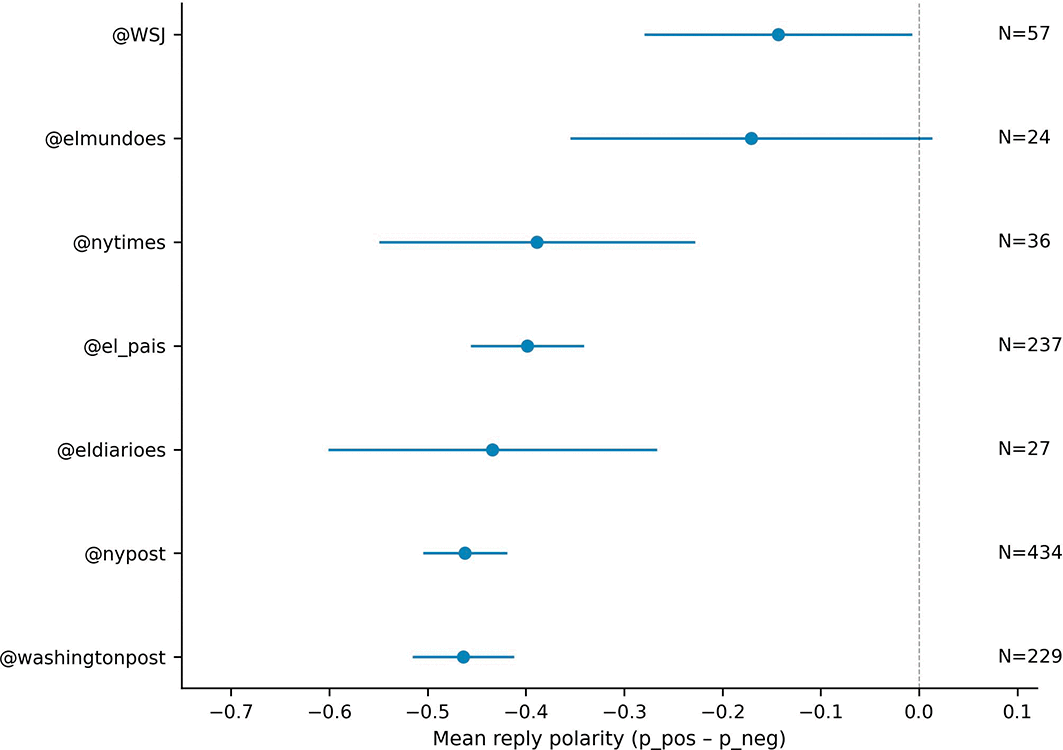
Figure 5. Mean polarity of user replies by media outlet.
Together, these results suggest that media ecosystems and audience alignments play a more decisive role in shaping user sentiment than national context or headline tone. User reactions appear embedded in media-specific interpretative communities, where prior orientations towards particular outlets influence how platform governance decisions are received and evaluated.
5. Discusion
In this article, aspects such as the level of media freedom in each country and the way in which each country approaches platform governance have been considered in order to assess whether differences exist between them. In this regard, although there are widespread concerns about freedom of expression in these contexts, platform companies frequently adopt a pragmatic stance in their operations within non-democratic environments, accepting governmental authority and complying with restrictive legal and political demands in order to maintain their market access. In Turkey, amendments to the national internet legislation require social media platforms to appoint a local legal representative within the country. This representative is obliged to cooperate with public authorities in the enforcement of domestic regulations, including content takedown requests and data-related obligations (Information Technology & Innovation Foundation, 2025).
Such regulations, widely criticized for their restrictive impact on freedom of expression, facilitates platform cooperation with state censorship mechanisms. According to the last Freedom House report (2025) about Turkey, social media companies, including X, suspended or restricted accounts belonging to independent media organizations and opposition politicians in response to government demands.
As Gorwa points out, it should not be overlooked that these network sites “are influential political actors with an obvious interest in preserving their dominant market positions” (Gorwa, 2019: 865). Less obvious, however, is the extent to which large digital platforms exert influence in democracies. Users may be free to think, speak, and participate, yet cases like the Facebook–Cambridge Analytica scandal illustrate how challenge democratic political processes can be challenged.
Moreover, the political influence of these high techs has generated an institutional pushback. Recently, leaders of the European Union publicly defended the autonomy of its digital regulation after President Donald Trump threatened retaliatory measures against the EU in response to enforcement actions under the Digital Services Act (Le Monde, 2025).
In this context, the new dilemma for the European Union is not limited to regulating its digital environment, but to position itself as an influential geopolitical actor in a global order increasingly shaped by non-European platform and artificial intelligence corporations. Control over large-scale data flows, algorithmic systems, and digital infrastructures has become an axis of contemporary power, one that will ultimately shape the capacity of democratic systems to govern themselves in the digital age.
6. Conclusion
This study examined how leading media outlets in the United States, Spain and Turkey framed Meta’s decision to replace IFCN-certified fact-checking with a community-notes model on platform X, and how users responded to these media posts. The analysis integrated quantitative metrics, lexical–semantic patterns, tone, thematic coding, user replies and polarity modelling.
The findings addressing SO1 reveal cross-national variation in media tone and stance. US and Spanish outlets combined neutral reporting with varying degrees of critical and politicised framing, whereas Turkish media maintained a consistently neutral and informational tone, with minimal engagement in evaluative or critical discourse. The absence of critical tone in the Turkish sample are consistent with broader findings on constrained information environments (Ertuna & Aşık, 2025; Yücel, 2025).
Regarding SO2, the lexical–semantic and thematic coding analyses also revealed variations across countries. In the United States, dominant lexical items and recurrent bigrams foregrounded issues of fact-checking and censorship, indicating a more conflict-oriented framing of Meta’s policy change. Spanish media discourse, by contrast, was characterised by a regulatory vocabulary centred on verification, content moderation and institutional processes, reflecting a more governance-focused emphasis. In Turkey, lexical patterns were largely actor- and platform-centred, with frequent references to Meta, Zuckerberg and affiliated platforms, and a relative absence of evaluative or critical semantic associations.
With respect to SO3, in the United States and Spain, audience responses frequently challenged or expanded the discursive frames established by media outlets, introducing additional political interpretations, normative judgments and critiques of platform governance. This corresponds to what Liu & McLeod (2019) concluded about the users that often engage in counter-framing by providing alternative perspectives or challenging the original editorial stance. In contrast, replies in Turkey tended either to reiterate the informational content of the posts or to divert the discussion toward moral or hostile commentary unrelated to Meta’s policy change.
The findings indicate that user-reply patterns are shaped more by media ecosystems than by national regulatory frameworks or headline tone (SO4). Although the study originally included Turkey, it was excluded from the sentiment analysis due to an insufficient number of statistically significant responses. In the United States and Spain, variations in user sentiment correspond primarily to the ideological orientation and editorial profiles of individual outlets rather than to differences in digital governance models. These results suggest that audience reactions are embedded within media-specific interpretative communities, where prior alignments and loyalties play a more decisive role than national context. In this regard, Spinde et al. (2023) found that the level of hostility expressed in user comments tends to increase in relation to the degree of bias present in the original article. They also provide evidence that the ideological orientation of the media outlet influences the bias embedded in the published content. Consequently, the editorial stance of the outlet emerges as a relevant factor shaping audience reactions, alongside the specific characteristics of the comments themselves (2023).
Software availability
Source code available from: https://github.com/pablopastora/meta-content-moderation-x-pipeline
Archived software available from: https://doi.org/10.5281/zenodo.19355020
License: MIT.
The data collection procedures relied on the following third-party open-source software:
https://github.com/agusnieto77/TweetScraperR
https://github.com/agusnieto77/twscrapeR
Sentiment analysis was conducted using transformer-based models implemented via the Hugging Face transformers library.
Ethics and consent
Ethical approval and consent were not required.







