Introduction
The driving force of all scientific inquiries are problems – unsolved or open problems. We observe phenomena that we cannot explain, we do not understand how phenomena interact and to which degree they influence each other, or we want to know how we can enhance methods that allow us to study phenomena of interest. While questions that ask for the solution of big problems often trigger peoples’ initial interest in science, scientists themselves typically work with much smaller problems. While the solution of small problems may seem boring to the public, they are crucial for the field to advance and they can lay the foundation for major breakthroughs at later stages.
Working on the typically small problems that individual subfields offer, all scientists run the risk of loosing track of their discipline’s broader challenges. Working luckily in our ivory tower that shields us from the outside world, it is often through confrontation with laypeople or scientists from other fields that we are made aware of the greater challenges of our own discipline.
In the field of linguistics, specifically in the field of historical linguistics, one of the questions that linguists have stopped asking is how language – that is, the specific communicative faculty of which many think is unique to humans – originated for the first time. Non-linguists are often very surprised that asking for the origin of language is a taboo question in the field of historical linguistics. Already in the 19th century, the question had been officially banned from the agenda of most linguistic endeavors. The statuts of the Société de Linguistique de Paris from 1866, for example, state that ‘[the] Société does not accept any contributions concerning neither the origin of the language faculty, nor the creation of a universal language.’ (Société de Linguistique de Paris, 1871, III).1 The situation has not changed since then. One of the first things I learned as a student of Indo-European and Comparative Linguistics at the Freie Universität Berlin in 2003 was that serious historical linguists would never ask about the origin or evolution of language.
Of course, there are good reasons to avoid asking how language originated. When sifting through the literature that has been published on this matter, one finds a diverse collection ranging from serious attempts to summarize what we can know and what we can’t know, up to the weirdest speculations. There are not many similar fields in science where it is so difficult to draw a line between genius and madness. On the one hand, one finds researchers who meticulously assemble tiniest pieces of evidence in the search for a clear picture in the dark glasses. On the other hand, one finds scholars so obsessed with a single idea that they have become blind to counterarguments. Specifically for outsiders from the field, for those not trained in historical linguistics and evolutionary anthropology, it is often very difficult to tell if a theory on the origin of language should be treated as a serious or a senseless idea. Next to Johann Gottfried Herder (1744–1802) who imagined that human beings would have run through the woods imitating the sounds of the objects and phenomena surrounding them (Herder, 1778, see also Table 1), scholars discuss whether Neanderthals could speak or not (Dediu & Levinson, 2013), they debate whether a single gene was responsible for our language faculty (Atkinson et al., 2018), they propose that research on aphasia might shed light on the structure of early language (Code, 2021), and they speculate about the nature of the ‘language of proto-sapiens’ in the context of yin and yang (Papakitsos & Kenanidis, 2018, see also Table 1). There is no doubt: the question invites bold speculation, and when bold speculation becomes careless, it can easily damage the reputation of entire scientific fields. At the same time, however, it feels strange that linguists would deliberately decide to ignore the investigation of a problem that some might consider the most fascinating the field has to offer. While following inconclusive debates and trying to not get angry or amused by weird speculations regarding the “big questions” of one’s discipline, one may easily forget that there are valid and important problems which one may have forgotten to think about. An example for such a problem that is routinely ignored in historical linguistics is the problem of the “size” of a language. While historical linguists never ask how many words a language has, or how many sentences one can speak until one would repeat oneself, non-linguists have often asked me these questions. I still remember quite vividly how annoyed I always felt – and at times even reacted – when colleagues from biology asked me if English was bigger than German or French. I tried to explain that languages are open systems that cannot be measured by counting the words in a corpus and that if at all, one would have to count the words in the head of individuals, but that this would not be possible from a practical viewpoint, and that as a result of these complications, linguists preferred to ignore the question completely and look into other problems instead. But with time, I learned to put my linguistic pride aside and began to understand that a solution to the question would have several important implications to other questions that are of vital interest to my research.
Table 1. Collection of quotes on the origin of language.
| Sound imitation at the origin of language. |
Take for example the sheep. As an image [...] – how much, how difficult to discern! All characteristics are intertwined, next to each other, all
still unspeakable! Who can talk shape? Who can sound colors? [...] Who can say what he feels with his hands? But listen, the sheep bleats! [...]
"Ha!" says the apprentice [...], "now I will recognize you – you bleat!" The turtledove coos! The dog barks! There are three words, because he was
looking for three clear ideas, the latter go into his logic, the former into his dictionary! [...] The soul grasped [for it] – there it has a sounding
word! (Herder, 1778, 76).2 |
| Yin, yang, and the language of proto-sapiens. |
The Proto-Sapiens grammar was so simple that the sporadic references in previous paragraphs have essentially described it. The prime
importance of sound symbolism for the people of nature should be noted again before we further detail that the vowel E was felt as indicating
the “yin” element, passivity, femininity etc., while “O” indicated the yang element, activeness, masculinity etc.; “A” was neutral or spiritual,
indicating things conceived by the mind and emotions rather than with the physical senses. (Papakitsos & Kenanidis, 2018, 8) |
In evolutionary biology, for example, scholars have argued that the amount of genes that were horizontally transferred among species largely exceeds the amount of genes that were vertically inherited (Dagan & Martin, 2006). Horizontal transfer is quite abundant in language history as well, and we usually base our phylogenetic studies on very small collections of basic words often not even exceeding 200 items per language (Greenhill et al., 2023; Sagart et al., 2019). It would therefore be interesting to have a rough estimate of how many words of a language survive over time, but this would require (at the very least) a rough estimate of the words that constitute a language.
In historical linguistics, Starostin (1989) has proposed that every language has about 1000 lexical roots from which most of the words in the language are formed. Up to today, no attempt has been made to count the number of lexical roots, even for well-documented languages like German or Chinese. It would be very interesting to see if Starostin’s estimate holds cross-linguistically, and how much variation we should expect when comparing the languages of the world.
Given that languages may differ quite substantially regarding the way in which they build new words from existing ones, it would also be very interesting to see to which degree languages differ regarding the “productivity” of their words to form families (List, 2023), and to which degree the production of new vocabulary is triggered by external events, such as, for example, pandemics or wars.
Lastly, measuring the number of words that different speakers of the same language know might even help us to investigate to which degree individual language faculties vary among humans. The question to which degree speakers of the same language differ regarding their competence is another question that is – unfortunately – rarely asked, although the notion of competence plays a crucial role in some linguistic fields.3
While the question of the “size of a language” has been mostly ignored in the context of historical linguistics, vocabulary size or vocubulary breadth4 have been routinely investigated by scholars focusing on foreign language acquisition (Milton, 2009) and psycholinguistics (Brysbaert et al., 2016; Nation & Coxhead, 2021). Unfortunately, the majority of these studies has concentrated exclusively on English. We know that languages may differ quite substantially regarding the structure of their word families and the techniques they use to create new words from existing ones (Milton, 2010, 226, see also List et al., 2016b, 9f). As a result, the estimates on vocabulary size are of limited use to address the above-mentioned problems in historical linguistics, and it remains an open problem to measure and compare the size of the vocabularies of the worlds’ languages.
As scientists, we cannot ask enough questions. Being used to address small problems as part of our scientific routines, however, we may forget to ask the “big questions” that are at the heart of our particular disciplines. By ignoring certain questions deliberately and limiting the scope of questions we allow ourselves to ask in our work we may easily loose the chance us to enrich our studies and open new horizons. Specifically for young and rapidly growing subdisciplines such as the field of computational historical linguistics, it can be very helpful to identify particular problems and challenges that should be addressed in future work. In the following, I will reflect on challenges that have been discussed in the context of comparative linguistics an contrast them with those challenges that I have identified for my own work. In doing so, I hope to show that an active discussion about open problems can be a useful guiding principle not only for an entire research field, but also for individual researchers.
Rational, general and historical problems
Major problems and challenges for the field of comparative linguistics have been discussed in the past on different occasions. Weinreich et al. (1968, 183–187) identify five general problems with respect to the phenomenon of language change, which they call
(1) the constraints problem, dealing with the question of which changes are possible in language change and which conditions could constrain them,
(2) the transition problem, dealing with the question of how and where changes are instantiated in concrete during language change,
(3) the embedding problem, dealing with the systemic aspects conditioning language change,
(4) the evaluation problem, dealing with the question to which degree change happens consciously in a community of language users, and
(5) the actuation problem, dealing with the question of how changes are triggered.
Roberts and Sneller (2020) discuss these in the context of the “four questions” for evolutionary sciences proposed by Tinbergen (1963), pointing to potential empirical implications and programs for future research. Tinbergen’s questions themselves have been originally stated for the field of biological evolution (Bateson & Laland, 2013), although they were later adopted by researchers studying cultural evolution (Roberts & Sneller, 2020, 194f). They are nowadays usually presented in a more systematic fashion than the problems by Weinreich et al. (1968), distinguishing two major perspectives, dynamic (diachronic) and static (synchronic), and two major kinds of questions, how- and why-questions, the former referring to individuals and the latter to species (Tinbergen, 1963). This allows to look at particular problems (e.g., the evolution of a specific trait) from four perspectives, namely
(1) the perspective of the ontogeny, focusing on how the trait evolves in individuals,
(2) the perspective of the mechanism, focusing on how the trait is structured synchronically in an individual,
(3) the perspective of the phylogeny, focusing on how the trait evolves inside a given species, and
(4) the perspective of the function, focusing on the role adaptive role the trait plays for a given species.
Similar to Roberts and Sneller (2020), I do not find it very helpful to try to classify the five problems by Weinreich et al. (1968) according to the schema proposed by Tinbergen (1963). Despite the apparent systematicity of the latter, I find the schema hard to apply to concrete problems.
As yet another example for an attempt to systematize linguistic endeavor by stating problems, Eugenio Coseriu (1921-2002, see Coseriu, 1973, 65f) suggested to distinguish three basic problems of language change, namely
(a) the rational problem of change (“problema racional del cambio”),
(b) the general problem of change events (“problema general de los cambios”), and
(c) the historical problem of a given change (“problema histórico de tal cambio determinado”).
These problems can again be represented by certain questions, as indicated by Coseriu himself. The rational problem asks why languages change after all (“¿por que cambian las lenguas?”). This question does not find a counterpart in the list of problems proposed by Weinreich et al. (1968), where language change has been taken for granted, and the goal is to investigate and describe the phenomenon. As Coseriu emphasizes himself, the problem is of a chiefly theoretical nature and cannot be resolved by identifying all causes for particular changes that can be observed for particular languages (ibid. 66f), but rather addresses the deeper question of why mutability is one of the fundamental characteristics of language (68f). Coseriu himself sees the reason for the mutable character of language as a result of the fact that languages is constantly recreated, not only when being learned by speakers, but also when being applied by them (69f).
The second problem of Coseriu is similar to the actuation problem by Weinreich et al. (1968), addressing the question in which conditions certain changes occur (“¿en qué condiciones suelen occurrir cambios en las lenguas?”). In Coseriu’s view, this problem is a problem of general linguistics in the sense that general linguistics deals with linguistic phenomena independently of particular languages. Particular changes in particular languages, finally, are addressed by the third problem, which Coseriu calls historical, emphasizing the individual character of investigating particular changes in particular languages.
Coseriu’s strict distinction between general problems in linguistics on the one hand and historical problems on the other hand finds a very close counterpart in the distinction between p(articular language)-linguistics and g(eneral) linguistics by Haspelmath (2020, 5), where a distinction between the investigation of language as a general communication system and the investigation of individual languages is made (see also Haspelmath, 2019).
Judging from numerous discussions with colleagues, distinguishing questions applying to individual languages and language families from questions applying to language in general (as a system of human communication) constitutes a much more important systematization of problems than the attempts by Weinreich et al. and Tinbergen. The failure to distinguish questions pertaining to particular languages and questions pertaining to language in general has led to many misunderstandings in the field of comparative linguistics. In my own research, it has happened quite a few times that scholars who reviewed my work were asking me to test new methods which I had designed to account for general problems of spoken languages against methods that could only solve problems for particular languages.
Hilbert problems
At the end of 2018, students from the Universidad de Buenos Aires asked me about the biggest challenges for computational historical linguistics. Inspired by this discussion, I decided to make a short list of tasks that I consider challenging, but of which I still think could be solved some time in the nearer or farther future.
The idea to make such a list of questions is not new. Mathematicians, for example, have their well-known Hilbert Problems, proposed by David Hilbert in 1900 (published in Hilbert, 1902). In linguistics, I first heard about them from Russell D. Gray, who himself was introduced to this by a talk of the linguist Martin Hilpert, who gave a talk on challenging questions for linguistics in 2014, called “Challenges for 21st century linguistics". Russell D. Gray since then has emphasized the importance to propose “Hilbert" questions for the fields of comparative linguistics and cultural evolution, and has also presented his own challenges in the past.
Due to my methodological background, the problems I identified and assembled were by no means big and in some sense also not necessarily extremely challenging (at least not at first sight). Instead, the problems I selected were problems I wanted to see solved at that time. While the solution of the problems would not directly advance our knowledge about language evolution and linguistic typology, I had the hope that it would help us to do so indirectly, by giving us the possibility to assemble more data and to carry out new analyses that would ultimately help us to search for answers on deeper questions in historical linguistics in specific and in comparative linguistics in general.
One further aspect of the problems that I selected was that I was convinced that they could all be solved by algorithms or workflows. Characterizing them as “small” refers to their very specific application range. I did not want to express that the problems I selected were not challenging. It also did not mean that I expected that they all could be solved in the nearer future, although, given that the work in the field of computational and computer-assisted language comparison, is steadily progressing, I had some confidence that at least some of these problems that I assembled by then would indeed be solvable within the next five years.
When writing down my ten open problems for computational historical linguistics, I announced them in a blog post for the blog The Genealogical World of Phylogenetic Networks (https://phylonetworks.blogspot.com/), edited by David Morrison, in January 2019 (List, 2019a), with the plan of discussing each of the problems in detail in monthly blog posts throughout the year. I managed to stick with this schedule and concluded the year with a final blog post in December 2019, in which I looked back at one year of discussing problems in my own research for which no solution could have been found by then (List, 2019d).
The 10 problems I came up with are listed in Table 2. I divided the problems into three different groups, which roughly correspond to three different categories I identified as being important for research in general, namely modeling (m), inference (i), and analysis (a). This triad, inspired by Dehmer et al. (2011, XVII), follows the general idea that scientific research in the historical disciplines usually starts from some kind of idea we have about our research object (the model stage), and based on which we then apply methods to infer examples in our data which confirm our ideas (the inference stage). Having inferred enough examples, we can then analyze them qualitatively or quantitatively (the analysis stage) and use this information to update our model, as indicated in the schema in Figure 1.
Table 2. 10 problems of computational diversity linguistics discussed in a series of blog posts in 2019.
| No. | Problem |
|---|
| 1 | automated morpheme segmentation (i) |
| 2 | automated borrowing detection (i) |
| 3 | automated sound law induction (i) |
| 4 | automated phonological reconstruction (i) |
| 5 | simulating lexical change (m) |
| 6 | simulating sound change (m) |
| 7 | statistical proof of language relatedness (m) |
| 8 | typology of semantic change (a) |
| 9 | typology of sound change (a) |
| 10 | typology of semantic promiscuity (a) |
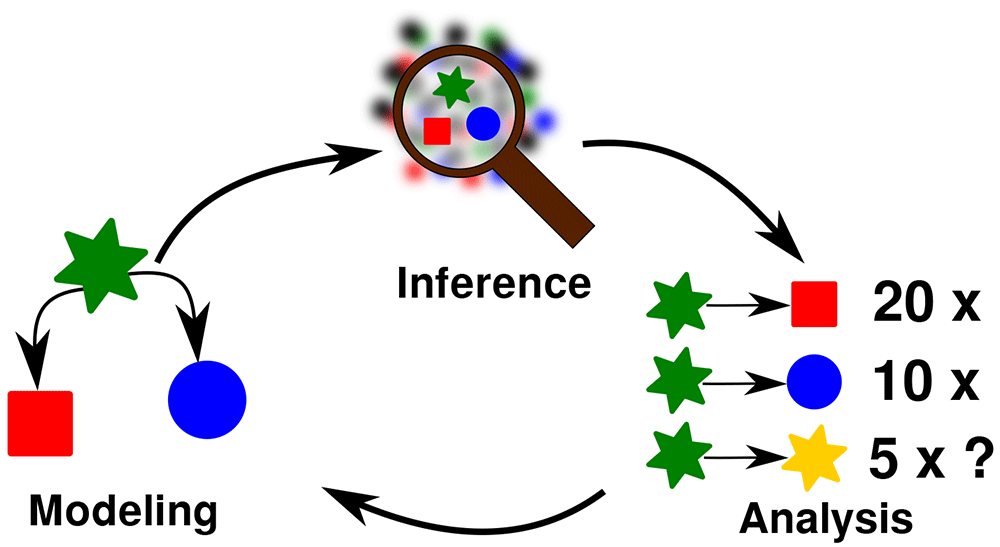
Figure 1. Research workflow for the investigation of problems in computational historical linguistics.
As an example for this procedure, consider the problem of cognate detection, the detection of historically related – or homologous – words across languages. Here, initial surveys of words across different languages have long since confirmed that we can easily find words which are to some extend similar to each other with respect to their form and their meaning, and that the amount of similar words varies quite significantly from one pair of languages to another. Starting from a model of lexical change that states that the lexicon of all spoken languages changes slowly over time, be it through the change of individual sounds or through the change of the meaning which a word expresses, we can derive a model of language split which assumes that the same language may split into two or more varieties when its speakers separate from each other and their language keeps modifying independently. Based on this evolutionary model, we can then conclude that similar words observed across different language varieties have been inherited from the common, formerly unified, ancestral variety. In order to detect these cognates, one could now design methods that help to find more than the so far observed similar words in order to increase the data basis. Once this has been done, and more material has been identified, one can analyze the data and try to see if the analysis provides some hints on specific questions, such as, for example, the more detailed branching history of a given language family.
As one can see from the example, the term modeling is used in a rather loose sense, unlike its usage in phylogenetic approaches, where modeling is often treated as synonymous with stochastic modeling, referring to a transition matrix which shows how certain characters can turn into other characters during an evolutionary process (Nunn, 2011).
With respect to my ten open problems from 2019, the first four problems belong to the family of inference problems, since they all deal with tasks where something has to be inferred from the data, be it morphemes from words (Problem 1, List, 2019e), lexical borrowings from word lists (Problem 2, List, 2019g), sound laws from data on ancestral languages and their descendants (Problem 3, List, 2019f), or proto-forms from cognate sets (Problem 4, List, 2019h).
The next three problems in my list belong to the family of modeling problems, since they all require to understand the processes by which certain aspects of languages, such as their lexicon (Problem 5, List, 2019i) or their sound systems (Problem 6, List, 2019j) change over time. Proving language relatedness statistically (Problem 7, List, 2019k) does not directly model any aspect of language evolution, but it requires a model of language relatedness that can then be tested against a random model in which languages are thought to be unrelated.5
The last three problems in my list all had “typology” in their title. They belong to the family of analysis problems, aiming to gain insights into phenomena of language change by comparing major processes, such as semantic change (Problem 8, List, 2019l) and sound change (Problem 9, List, 2019b). What was meant by “typology” in this context was a data-driven estimate of the overall cross-linguistic dynamics of these phenomena. Lacking consistent accounts on the general tendencies of these processes and phenomena when excluding areal and genetic factors, the task I thought of was to come up with a consistent estimate on each of them. While semantic change and sound change are probably self-explaining in this context, the last problem – dealing with the question of what I called “semantic promiscuity” by then – deserves some explanation (Problem 10, List, 2019c. What I meant with this term was the degree to which certain words, due to their original meanings, are re-used or re-cycled in the human lexicon. While the term promiscuity has been used before in other contexts in linguistics (Schweikhard, 2018), the specific usage of promiscuity to denote what one could also call semantic productivity or concept productivity, was first proposed in List et al. (2016a), where biological and linguistic processes were consistently compared with each other, and semantic promiscuity was identified as a phenomenon similar to domain promiscuity in protein evolution in biology (Basu et al., 2008), with an explicit analogy being identified between the processes of word formation in linguistics and protein assembly (Ahnert et al., 2015) in biology (List et al., 2016a, 5).
New and old open problems
The series of blog posts was generally well received, and some posts triggered interesting discussions. However, my hope that at least a few of the problems might be considered as “solved” after half a decade turned out to have been a false one. When looking back at the list of ten problems now, almost five years after I first proposed them, I do not have the feeling that we got any closer in solving any of them.
Inference problems
As far as inference problems are concerned, no significant progress was made with respect to the tasks of automated morpheme segmentation (Problem 1) and automated sound law induction (Problem 3).
Quite a few new methods have been proposed to address the detection of lexical borrowings (Problem 2). Among these are supervised approaches (which I had deliberately excluded, since I consider unsupervised approaches as more useful when it comes to inference problems) that made use of recurrent neural networks (Miller et al., 2020), there are tree-based approaches that even try to identify the direction of borrowings (Neureiter et al., 2022),6 and there are numerous attempts to handle very specific cases of lexical borrowing, such as contact across language families (Hantgan et al., 2022; List & Forkel, 2022) or contact induced by dominant languages (Kaiping & Klamer, 2022; Miller & List, 2023).
While all of these methods may contribute to the detection of borrowings in particular cases, all of them suffer from the problem that they need very specific conditions to work. For supervised approaches, we need labeled training data, for tree-based approaches to borrowing detection, we need phylogenetic trees, for borrowing detection across language families, we need languages to belong to different families, and for the detection of borrowing from dominant languages, we need to deal with languages that are spoken in a region where dominant languages occur.
It is well possible, that the current pocket knife solution that employs various forms of evidence to find borrowings in very specific contexts is the only feasible way to handle the problem of language contact in computational historical linguistics. Even classical approaches to historical language comparison do not use one unified approach to identify borrowed traits, but rather hope to accumulate enough evidence until borrowing is the only convincing solution to explain the data at hand. But even if we accept that we need to embrace arguments based on “cumulative evidence” (Berg, 1998) or “consilience” (Whewell, 1847; Wilson, 1998) in order to solve the problem of borrowing detection (see also List, 2019n, 11), we are still quite far away from being able to handle all the evidence with automated approaches which goes into the argumentation of classical qualitative approaches to borrowing detection. From today’s perspective, I would adjust the problem of borrowing detection in order to make it more specific. Here, a problem I would really love to be solved would be the detection of the layers of contact across a group of languages (Lee & Sagart, 2008). Contact layers have been discussed for a long time in the literature on language contact. The idea behind contact layers is that the individual traits of a language can be stratified and assigned to different groups that would point to different phases in which these traits were borrowed through specific contact events. Developing a method that would be able to group borrowings into different strata that could then be identified with specific contact events in time would be extremely beneficial for the discipline of historical linguistics. The problem is, however, also very challenging, since it is not clear whether contact layers can be identified in all cases (evidence might just have been lost), and on what kind of evidence one should base the detection of contact layers. This makes contact layer detection a truly hard problem, although I would not consider it impossible to solve.
Rather huge progress – at least when looking back specifically at the last couple of years – has been made with respect to supervised phonological reconstruction. Here the task is different from the problem I had originally stated. Instead of inferring the proto-language from a sufficiently large number of aligned cognate sets, the method is given aligned cognate sets (or simply cognate sets) along with a certain number of already reconstructed proto-forms that can be used to train a machine learning model in a first instance. In a second instance the model can then be used to infer proto-forms for data that has not been seen previously.
While scholars had been working on this problem before, a first impressive demonstration of the capability of machine learning methods was done by Meloni et al. (2021) for a test set in which Latin words needed to be reconstructed from words in several Romance languages. The authors used recurrent neural networks to learn to predict Latin word forms from word forms in the Romance languages. What was remarkable about their approach was the high accuracy reported. Using the edit distance (Levenshtein, 1966) to compare the proposed Latin word with the attested Latin word, their best parameter settings reported scores in which the proposed word would on average diverge less than one character from the attested word form. Kim et al. (2023) repeated the experiments by Meloni et al. (2021) but used Transformers (Vaswani et al., 2017), the famous architecture for neural networks, that has revolutionized artificial intelligence applications in many areas, but is best known in the context of large stochastic language models that are used to run chat bots. Not unexpectedly, the Transformer models further outperform the recurrent neural network architecture employed by Meloni et al. (2021).
The problem of supervised phonological reconstruction can be stated in the broader context of reflex prediction. Reflex prediction refers to the task of predicting how a word sounds when knowing the pronunciation of historically related words in related languages. For example, observing words like German Zoll and Swedish tull “customs”, I might predict that the English should have a corresponding words toll with a meaning similar (but not necessarily identical) to the meaning of the words in Swedish and German. At times, this may even work with language pairs, and as learners of languages closely related to languages we know intimately, we may even intuitively predict how certain words in the foreign language might sound, based on our knowledge of similar words in the languages we know.
We introduced the task in a preregistered study in which we first predicted word forms in languages that had so far been insufficiently studied and then checked the predictions against word forms verified in field work carried out after the predictions had been registered (Bodt & List, 2022). For the prediction, we used a supervised approach that goes back to a new method for the detection of regular sound correspondence patterns which I had introduced in 2019m. Having refined this approach in a later study, testing it on a larger collection of datasets from different language families (List et al., 2022b), we used it as a baseline for a shared task on reflex prediction where we invited scholars with a background in machine learning and historical linguistics to design their own approaches for the task of reflex prediction (List et al., 2022c). For this shared task, we used an even larger number of datasets from the Lexibank repository (List et al., 2022a) and introduced a computer-assisted pipeline to make sure that all participants would have access to the data in the same form. The best systems were presented by Kirov et al. (2022) who used sophisticated neural network architectures and data processing pipelines to augment the very sparse input data. Interestingly, their best model was not based on transformers, but on convolutional network architectures originally designed for the task of restoring images (Liu et al., 2018).
With respect to the originally proposed problem of unsupervised phonological reconstruction, not much has happened in the meantime. In 2013, Bouchard-Côté et al. (2013) showed that unsupervised automated phonological reconstruction is possible for Austronesian languages, using a complex framework in which stochastic transducers were applied to model the evolution of individual words across known reference trees. Since then, only Jäger (2019) has presented an alternative approach to the problem, in which methods for ancestral state reconstruction (Nunn, 2011, 63–89) were applied to a test set of Romance languages. The results were apparently disappointing, but closer inspection easily shows that the problem is less the method itself (although a closer analysis would be needed), but even more the quality and the nature of the original data, which treats Latin as the ancestor of the Romance languages, although it has been known for a long time that a reconstruction of Romance languages cannot reveal Latin entirely, since many distinctions have been lost across all Romance languages (Hall, 1950).
In summary, we can conclude that the problem of automated phonological reconstruction remains a difficult problem for which no satisfying solutions exist so far. Even the very good results reported for the supervised reconstruction on Romance languages should be taken with considerable care, since the original dataset by Ciobanu & Dinu (2014) is far too large to provide a realistic test case that would be applicable to other language families. Not only does it seem impossible to find a comparable number of cognate sets for other language families of the same time depth as that of the Romance language family, I would also suspect that the majority of supposed cognates in the data do not qualify as true cognates (referring to etymologically related words, see Trask, 2000, 63) but rather reflect late borrowings from Latin into the individual Romance languages. Since borrowings show very different rules of transformation, which are – at least in the case of borrowings from Latin into Romance languages – often much simpler than the complex sound change processes that can be observed in the languages of the world, it would be important to test the approach by Meloni et al. (2021) and the follow-up approach by Kim et al. (2023) on the much sparser dataset that we proposed for our shared task on reflex prediction in order to understand their real potential.
Modeling problems
With respect to the modeling problems, there was – as far as I can judge – no substantial progress in the simulation of lexical change and sound change, but there were some interesting studies dealing with the problem of finding a statistical proof for language relatedness.
Ceolin (2019) tested the methods by Baxter and Manaster Ramer (2000), Kessler and Lehtonen (2006) and Kessler (2001) on a dataset consisting of six different language varieties, including Turkish, Mongolian, and Manchu, three languages that some scholars assume to be genetically related, showing that no conclusive results could be obtained in favor of the highly disputed Altaic language family (Georg, 2017).
Kassian et al. (2021) employed the test reported by Turchin et al. (2010), originally inspired by Dolgopolsky (1964) to another dataste of languages from the disputed Altaic family, with the difference that they used reconstructed proto-languages. Their test also failed to provide conclusive evidence for the whole language family, although they argue that rather clear support can be found for a deeper relationship of the families tested by Ceolin (2019). While both Ceolin (2019) and Kassian et al. (2021) applied methods proposed before to newly compiled datasets, Blevins and Sproat (2021) designed a new workflow for to test for supposed deep language relations in order to find evidence for the hypothesis that the language isolate Basque is related to Indo-European. In contrast to previous studies, Blevins and Sproat (2021) test their approach on a rather large sample of languages where the language relations are known, showing that their approach is rather conservative, showing a tendency to reject grouping two languages within the same family in case of sparse evidence. Whether this is enough to prove the case of Basque and Indo-European, however, remains to be seen, since the data used in the test and the data used to test the potential relationship between Basque and Indo-European were not identical in design. This makes it more difficult to interpret the results of the test.
Given that Ceolin (2019) and Kassian et al. (2021) report contradicting results, both using methods that are supposed to deliver clear mathematical proofs, and given the difficulty to compare the evaluation study reported by Blevins and Sproat (2021) with the tests they conducted, I think it is safe to argue that the last word on the problem of finding a convincing statistical proof for language relatedness has not yet been spoken.
Analysis problems
No progress that I would be aware of has been made with respect to the establishment of first typologies for semantic change (Problem 8) and sound change (Problem 9). This confirms my original suspicion that both problems are indeed rather tough ones, requiring large amounts of annotated data – along with ideas of how the data should be annotated – that we simply do not have at the moment. Regarding the last problem on my list, the problem of establishing a typology of what I called semantic promiscuity by then, there has been no progress regarding the methodology of studying the phenomenon, but I think that there was at least some progress in explaining and defining the problem itself more properly. When I initially stated the problem, I was not aware of the rather large body of literature devoted to the topic of lexical motivation, referring to the process by which new words are created from existing ones (Koch, 2001; Koch & Marzo, 2007; Urban, 2016). Most of the words in the lexicon of human languages are composed from other words and individual word histories can be very complex, as can be seen from the illustration in Figure 2, where I have described, how the term Ellenbogengesellschaft in German (“dog-eat-dog society”, lit. “elbow society”) derives from individual words and suffixes. For a long time, I have been trying to find a way to investigate to which degree the meaning of individual words contributes to their reuse.
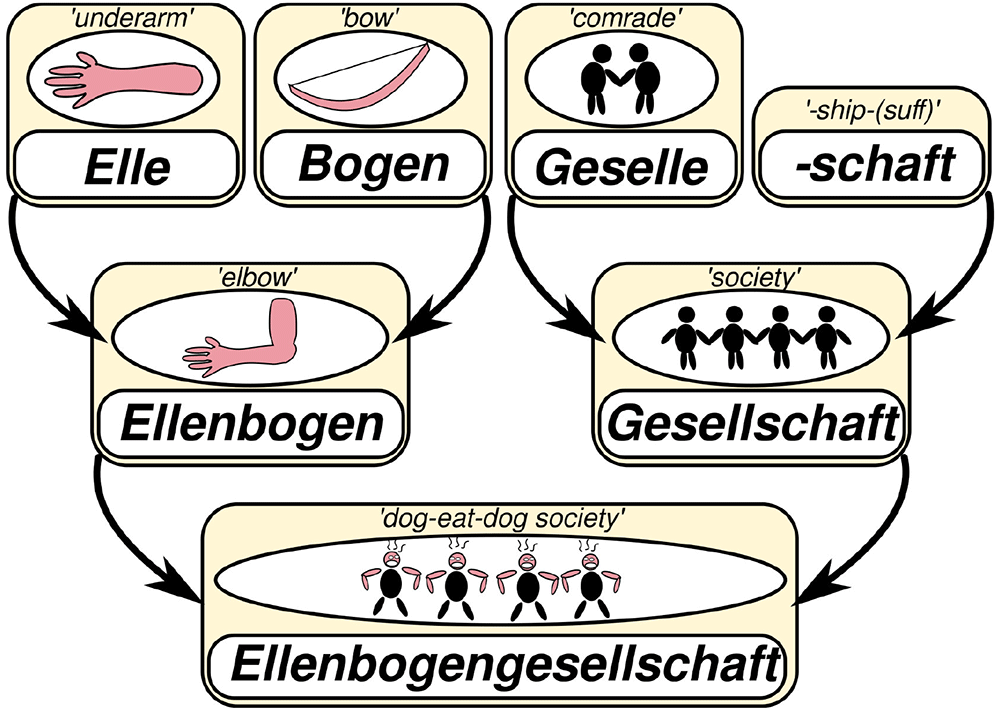
Figure 2. The lexical motivation of the term “dog-eat-dog society” in German.
Geisler (2018) makes the rather strong claim that word reuse results from bodily experiences made in early life, such as the act of “falling” or “standing”. This could explain why words build from the verbal roots meaning “to fall” and “to stand” are so frequently met in German. An alternative possibility would be that word reuse reflects actual trends that could change over time (Alinei, 2001). This could explain, for example, the recent increase in the use of metaphors from psychology, popularly also known as “therapy speech” (Prendergast, 2022). Most likely, none of the two extreme positions is absolutely true. Instead, it is quite likely that both actual trends and important (potentially bodily) experiences contribute to the reuse of words in the world’s languages. But a detailed investigation of the semantics underlying these processes by which new words are formed from existing ones has so far not been carried out yet.
When I first stated my problem of establishing a typology of semantic promiscuity, I did not know that quite some detailed work on the processes of lexical motivation – albeit mostly qualitative in nature – had already been carried out and that some authors had proposed concepts quite similar to what I had in mind when proposing the term semantic promiscuity. Blank (1997, 21), for example, describes the processes of attraction and expansion. Attraction refers to cases where a given concept “attracts” different words to express it. In theory, we might be able to measure the attractivity of concepts, that is, their propensity to be expressed by multiple words. Expansion refers to cases where a word receives new meanings. If one agrees that the expansivity of words typically depends on the meaning they express originally, one could take this idea one step further and measure the expansivity of concepts and compare it across languages. Taking it one additional step further, one could then ask not only which concepts are good at triggering the extension of a word’s meaning, but also which concepts are good at triggering the reuse of a word in word formation processes, which is what I meant to denote with the term “semantic promiscuity”.
In a recent study in which I proposed new methods for the automated inference of words that share certain parts resulting from word formation processes (called partial colexifications in that study, see List, 2023), I found that there is a tendency for words expressing certain concepts to be reused much more frequently in other words than words expressing different concepts. I also found a tendency for certain concepts to be expressed by words that are composed rather than being expressed by single morphemes. Since my analyses are based on a very rough approach that has not yet been tested any further so far, they should be taken with certain care. Given the confusion that the term “semantic promiscuity” has created in discussions with colleagues as well as in discussions following my original blog post (List, 2019c), I decided – inspired by a comment of Alexandre François – to use the term “lexical root productivity” from now on, in order to refer to the reuse potential of words in the lexicon – resulting from their meaning.
Regarding the problem of establishing a typology of lexical root productivity, I would no longer consider this as the most important problem for the field of lexical typology. Instead, I think, that one could state the problem in broader terms as the problem of establishing a typology of processes of lexical motivation that would allow us to investigate both how words are reused across the languages in the world (form-based perspective), and how concepts are expressed with the help of reusing lexical material (concept-based perspective). Despite earlier attempts to solve certain aspects of this problem (Urban, 2012), a real typology of lexical motivation has not yet been established, and the problem can therefore be considered as an unsolved one.
Outlook
In the end of 2018, I identified ten unsolved problems in computational historical linguistics that I considered as important and solvable at the same time. While quite some progress has been made in the past five years, most of the problems are still not solved, and it is not clear if and when we will find solutions for them. In order to be able to compare where I see the field of computational historical linguistics now, five years later, I have created a revised list of open problems, which is shown in Table 3. In two cases (Problem 3, contact layer detection, and Problem 10, typology of lexical motivation), I have decided to shift the focus and therefore modified the title of the problem. In two out of ten problems (Problem 3, automated borrowing detection, and Problem 4, automated phonological reconstruction), I would argue that some substantial progress has been made in the field, although I do not consider any of the problems as “solved” as of today.
Table 3. Updated list of open problems in computational historical linguistics.
| No. | Problem (2019) | Problem (2023) | Progress |
|---|
| 1 | automated morpheme segmentation | - |
| 2 | automated sound law induction | - |
| 3 | automated borrowing detection | contact layer detection | + |
| 4 | automated phonological reconstruction | + |
| 5 | simulation of lexical change | - |
| 6 | simulation of sound change | - |
| 7 | statistical proof of language relatedness | (+) |
| 8 | typology of semantic change | - |
| 9 | typology of sound change | - |
| 10 | typology of semantic promiscuity | typology of lexical motivation | (+) |
Given that my optimism from 2018, when I assumed that most problems could be solved in five to ten years’ time, has not turned out to be very reliable, I would now refrain from making any further assumptions on whether the ten problems outlined in Table 3 are solvable or not. If, however, in five years from now, the progress of the field of historical computational linguistics has been at a similar rate as it has been in the past five years, I assume that we will see some substantial progress, even if none of the problems can be solved completely.
Data and software availability
Source data
No data are associated with this study.
Software availability
No software are required for this study.
Acknowledgments
I would like to thank Nathan W. Hill for ongoing interesting discussions on open problems in historical linguistics, and Russell D. Gray for introducing me to the fascinating world of open problems in science.
Faculty Opinions recommendedReferences
- Ahnert SE, Marsh JA, Hernández H, et al.:
Principles of assembly reveal a periodic table of protein complexes.
Science.
2015; 350(6266): aaa2245. PubMed Abstract
| Publisher Full Text
- Alinei M:
Aspects of a theory of lexical motivation (iconymicity).
Versus. Quaderni di studi semiotici.
2001; 88/89(1): 89–97.
- Atkinson EG, Audesse AJ, Palacios JA, et al.:
No evidence for recent selection at FOXP2 among diverse human populations.
Cell.
2018; 174(6): 1424–1435.e15. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Basu MK, Carmel L, Rogozin IB, et al.:
Evolution of protein domain promiscuity in eukaryotes.
Genome Res.
2008; 18(3): 449–461. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Bateson P, Laland KN:
Tinbergen's four questions: an appreciation and an update.
Trends Ecol Evol.
2013; 28(12): 712–718. PubMed Abstract
| Publisher Full Text
- Baxter WH, Manaster Ramer A:
Beyond lumping and splitting. Probabilistic issues in historical linguistics. In: Colin Renfrew, April McMahon, and Larry Trask, editors, Time Depth in Historical Linguistics. McDonald Institute for Archaeological Research, Cambridge, 2000; 167–188.
- Berg T:
Linguistic structure and change: An explanation from language processing. Clarendon Press, Gloucestershire, 1998. Reference Source
- Blank A:
Prinzipien des lexikalischen Bedeutungswandels am Beispiel der romanischen Sprachen. Niemeyer, Tübingen, 1997. Reference Source
- Blevins J, Sproat R:
Statistical evidence for the proto-indo-european-euskarian hypothesis.
Diachronica.
2021; 38(4): 506–564. Publisher Full Text
- Bodt TA, List JM:
Reflex prediction. a case study of western kho-bwa.
Diachronica.
2022; 39(1): 1–38. Publisher Full Text
- Bouchard-Côté A, Hall D, Griffiths TL, et al.:
Automated reconstruction of ancient languages using probabilistic models of sound change.
Proc Natl Acad Sci U S A.
2013; 110(11): 4224–4229. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Brysbaert M, Stevens M, Mandera P, et al.:
How many words do We know? Practical estimates of vocabulary size dependent on word definition, the degree of language input and the participant’s age.
Front Psychol.
2016; 7: 1116. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Ceolin A:
Significance testing of the altaic family.
Diachronica.
2019; 36(3): 299–336. Publisher Full Text
- Ciobanu AM, Dinu LP:
Automatic detection of cognates using orthographic alignment. In: Proceedings of the 52nd Annual Meeting of the Association for Computational Linguistics (Short Papers). 2014; 2. : 99–105. Publisher Full Text
- Code C:
The prehistory of speech and language is revealed in brain damage.
Philos Trans R Soc Lond B Biol Sci.
2021; 376(1824): 20200191. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Coseriu E:
Sincronía, diacronia e historia. El problema del cambio lingüístico. Biblioteca Románica Hispánica, Madrid, 1973. Reference Source
- Dagan T, Martin W:
The tree of one percent.
Genome Biol.
2006; 7(10): 118. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Dąbrowska E:
Language as a phenomenon of the third kind.
Cogn Linguist.
2020; 31(2): 213–229. Publisher Full Text
- Dediu D, Levinson SC:
On the antiquity of language: the reinterpretation of Neandertal linguistic capacities and its consequences.
Front Psychol.
2013; 4: 397. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Dehmer M, Emmert-Streib F, Graber A, et al.:
Applied statistics for network biology. Methods in systems biology. Wiley-Blackwell, Weinheim, 2011. Publisher Full Text
- Dolgopolsky AB:
Gipoteza drevnejego rodstva jazykovych semej Severnoj Evrazii s verojatnostej točky zrenija.
Voprosy Jazykoznanija.
1964; 2: 53–63.
- Geisler H:
Sind unsere Wörter von Sinnen? Überlegungen zu den sensomotorischen Grundlagen der Begriffsbildung. In: Kerstin Kazzazi, Karin Luttermann, Sabine Wahl, and Thomas A. Fritz, editors, Worte über Wörter. Festschrift zu Ehren von Elke Ronneberger-Sibold. Stauffenburg, Tübingen, 2018; 131–142.
- Georg S:
The role of paradigmatic morphology in historical, areal and genealogical linguistics.
Journal of Language Contact.
2017; 10: 353–381. Publisher Full Text
- Greenhill SJ, Haynie HJ, Ross RM, et al.:
A recent northern origin for the utoaztecan family.
Language.
2023. Publisher Full Text
- Hall RA:
The Reconstruction of Proto-Romance.
Language.
1950; 26(1): 6–27. Publisher Full Text
- Hantgan A, Babiker H, List JM:
First steps towards the detection of contact layers in Bangime: A multi-disciplinary, computer-assisted approach [version 2; peer review: 2 approved].
Open Res Eur.
2022; 2: 10. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Haspelmath M:
Confusing p-linguistics and g-linguistics: Philosopher Ludlow on “framework-free theory”.
Diversity Linguistics Comment.
2019; 7(6). Reference Source
- Haspelmath M:
Human linguisticality and the building blocks of languages.
Front Psychol.
2020; 10: 3056. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Herder JG:
Abhandlung über den Ursprung der Sprache, welche den von der königl. Academie der Wissenschaften für das Jahr 1770 gesetzten Preis erhalten hat. Christian Friedrich VoSS, Berlin, 1778.
- Hilbert D:
Mathematical problems.
B New York Math So.
1902; 8(1): 437–479. Publisher Full Text
- Jäger G:
Computational historical linguistics.
Theor Linguist.
2019; 45(3–4): 151–182. Publisher Full Text
- Kaiping GA, Klamer M:
The dialect chain of the Timor-Alor-Pantar language family A new analysis using systematic Bayesian phylogenetics.
Language Dynamics and Change.
2022; 2022(2): 1–53. Publisher Full Text
- Kassian AS, Starostin G, Egorov LM, et al.:
Permutation test applied to lexical reconstructions partially supports the altaic linguistic macrofamily.
Evol Hum Sci.
2021; 3: e32. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Kassian A, Zhivlov M, Starostin GS:
Proto-Indo-European-Uralic comparison from the probabilistic point of view.
J Indo-Eur Stud.
2015; 43(3–4): 301–347. Reference Source
- Kessler B:
The significance of word lists. CSLI Publications, Stanford, 2001. Reference Source
- Kessler B, Lehtonen A:
Multilateral comparison and significance testing of the Indo-Uralic Question. In: Peter Forster and Colin Renfrew, editors, Phylogenetic Methods and the Prehistory of Languages. McDonald Institute monographs,Cambridge UK , Oxford UK , Oakville CT USA„ McDonald Institute for Archaeological Research; Distributed by Orbow Books, 2006; 33–43. Reference Source
- Kim YM, Chang K, Cui C, et al.:
Transformed protoform reconstruction. In: Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers). Toronto, Canada, Association for Computational Linguistics, 2023; 2. : 24–38. Publisher Full Text
- Kirov C, Sproat R, Gutkin A:
Mockingbird at the SIGTYP 2022 Shared Task: Two types of models for the prediction of Cognate Reflexes. In: The Fourth Workshop on Computational Typology and Multilingual NLP. Online, Association for Computational Linguistics, 2022; 70–79. Publisher Full Text
- Koch P:
Lexical typology from a cognitive and linguistic point of view. In: Martin Haspelmath, Ekkehard König, Wulf Oester- reicher, and Wolfgang Raible, editors, Language Typology and Language Universals. number 20.2 in Handbook of Linguistics and Communication Science, de Gruyter, Berlin and New York, 2001; 1142–1178. Reference Source
- Koch P, Marzo D:
A two-dimensional approach to the study of motivation in lexical typology and its first application to french high-frequency vocabulary.
Stud Lang.
2007; 31(2): 259–291. Publisher Full Text
- Lee YJ, Sagart L:
No limits to borrowing: The case of Bai and Chinese.
Diachronica.
2008; 25(3): 357–385. Publisher Full Text
- Levenshtein VI:
Binary codes capable of correcting deletions, insertions, and reversals.
Soviet Physics Doklady.
1966; 10(8): 707– 710. Reference Source
- List JM:
Investigating the impact of sample size on cognate detection.
J Lang Relat.
2014; 11: 91–101. Publisher Full Text
- List JM:
Future challenges for computational diversity linguistics.
The Genealogical World of Phylogenetic Networks.
2019a; 6(1): 1–3. Publisher Full Text
- List JM:
Typology of sound change (open problems in computational diversity linguistics 9).
The Genealogical World of Phylogenetic Networks.
2019b; 6(10): 1–8. Publisher Full Text
- List JM:
Typology of semantic promiscuity (open problems in computational diversity linguistics 10).
The Genealogical World of Phylogenetic Networks.
2019c; 6(11): 1–5. Publisher Full Text
- List JM:
Open problems in computational diversity linguistics: Conclusion and outlook.
The Genealogical World of Phylogenetic Networks.
2019d; 6(12): 1–5. Publisher Full Text
- List JM:
Automatic morpheme segmentation (Open problems in computational diversity linguistics 1).
The Genealogical World of Phylogenetic Networks.
2019e; 6(2): 1–5. Publisher Full Text
- List JM:
Automatic detection of borrowing (Open problems in computational diversity linguistics 2).
The Genealogical World of Phylogenetic Networks.
2019f; 6(3): 1–6. Publisher Full Text
- List JM:
Automatic sound law induction (Open problems in computational diversity linguistics 3).
The Genealogical World of Phylogenetic Networks.
2019g; 6(4): 1–8. Publisher Full Text
- List JM:
Automatic phonological reconstruction (Open problems in computational diversity linguistics 4).
The Genealogical World of Phylogenetic Networks.
2019h; 6(5): 1– 7. Publisher Full Text
- List JM:
Simulation of lexical change (Open problems in computational diversity linguistics 5).
The Genealogical World of Phylogenetic Networks.
2019i; 6(6): 1–6. Publisher Full Text
- List JM:
Simulation of sound change (Open problems in computational diversity linguistics 6).
The Genealogical World of Phylogenetic Networks.
2019j; 6(7): 1–6. Publisher Full Text
- List JM:
Statistical proof of language relatedness (Open problems in computational diversity linguistics 7).
The Genealogical World of Phylogenetic Networks.
2019k; 6(8): 1–6. Publisher Full Text
- List JM:
Typology of semantic change (Open problems in computational diversity linguistics 8).
The Genealogical World of Phylogenetic Networks.
2019l; 6(9): 1–5. Publisher Full Text
- List JM:
Automatic inference of sound correspondence patterns across multiple languages.
Comput Linguist.
2019m; 45(1): 137–161. Publisher Full Text
- List JM:
Automated methods for the investigation of language contact, with a focus on lexical borrowing.
Lang Linguist Compass.
2019n; 13(10): e12355. Publisher Full Text
- List JM:
Inference of partial colexifications from multilingual wordlists.
Front Psychol.
2023; 14: 1156540. PubMed Abstract
| Publisher Full Text
| Free Full Text
- List JM, Forkel R:
Automated identification of borrowings in multilingual wordlists [version 3; peer review: 4 approved].
Open Res Eur.
2022; 1: 79. PubMed Abstract
| Publisher Full Text
| Free Full Text
- List JM, Forkel R, Greenhill SJ, et al.:
Lexibank, a public repository of standardized wordlists with computed phonological and lexical features.
Sci Data.
2022a; 9(316): 316. Publisher Full Text
- List JM, Hill NW, Forkel R:
A new framework for fast automated phonological reconstruction using trimmed alignments and sound correspondence patterns. In: Proceedings of the 3rd Workshop on Computational Approaches to Historical Language Change. Dublin, Association for Computational Linguistics, 2022b; 89–96. Reference Source
- List JM, Lopez P, Bapteste E:
Using sequence similarity networks to identify partial cognates in multilingual wordlists. In: Proceedings of the Association of Computational Linguistics 2016 (Volume 2: Short Papers). Berlin, Association of Computational Linguistics, 2016a; 2. : 599–605. Publisher Full Text
- List JM, Pathmanathan JS, Lopez P, et al.:
Unity and disunity in evolutionary sciences: process-based analogies open common research avenues for biology and linguistics.
Biol Direct.
2016b; 11: 39. PubMed Abstract
| Publisher Full Text
| Free Full Text
- List JM, Vylomova E, Forkel R, et al.:
The SIGTYP shared task on the prediction of cognate reflexes. In: Proceedings of the 4th Workshop on Computational Typology and Multilingual NLP. Seattle, Association for Computational Linguistics, Max Planck Institute for Evolutionary Anthropology, 2022c; 52–62. Publisher Full Text
- Liu G, Reda FA, Shih KJ, et al.:
Image inpainting for irregular holes using partial convolutions. In: Vittorio Ferrari, Martial Hebert, Cristian Sminchisescu, and Yair Weiss, editors, Proceedings of the 15th European Conference on Computer Vision (ECCV 2018). Munich, Germany, Springer International Publishing, 2018; 11215. : 89–105. Publisher Full Text
- Meloni C, Ravfogel S, Goldberg Y:
Ab antiquo: Neural proto-language reconstruction. In: Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies. Association for Computational Linguistics, 2021; 4460–4473. Publisher Full Text
- Miller JE, List JM:
Detecting lexical borrowings from dominant languages in multilingual wordlists. In: Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics. Short Papers. Association of Computational Linguistics, 2023; 2591–2597. Reference Source
- Miller JE, Tresoldi T, Zariquiey R, et al.:
Using lexical language models to detect borrowings in monolingual wordlists.
PLoS One.
2020; 15(12): e0242709. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Milton J:
Measuring second language vocabulary acquisition. DeGruyter, Berlin and New York, 2009. Publisher Full Text
- Milton J:
The development of vocabulary breadth across the CEFR levels. A common basis for the elaboration of language syllabuses, curriculum guidelines, examinations, and textbooks across Europe. In: INge Bartning, Maisa Martin, and Ineke Vedder, editors, Communicative proficiency and linguistic development: intersections between SLA and language testing research. Eurosla, York, 2010; 211–232. Reference Source
- Mortarino C:
An improved statistical test for historical linguistics.
Statistical Methods and Applications.
2009; 18(2): 193–204. Publisher Full Text
- Nation ISP, Coxhead A:
Measuring native-speaker vocabulary size. John Benjamins, 2021. Reference Source
- Neureiter N, Ranacher P, Efrat-Kowalsky N, et al.:
Detecting contact in language trees: a Bayesian phylogenetic model with horizontal transfer.
Humanit Soc Sci Commun.
2022; 9(1): 205. Publisher Full Text
- Nunn CL:
The comparative approach in evolutionary anthropology and biology. University of Chicago Press, Chicago and London, 2011. Reference Source
- Papakitsos EC, Kenanidis IK:
Going to the root: Paving the way to reconstruct the language of homosapiens.
International Linguistics Research.
2018; 1(2): 1–16. Reference Source
- Prendergast C:
Therapy dialect is a thing right now – but could it be toxic?
Vogue.
2022; 129(7). Reference Source
- Ringe DA:
On calculating the factor of chance in language comparison.
T Am Philos Soc.
1992; 82(1): 1–110. Publisher Full Text
- Roberts G, Sneller B:
Empirical foundations for an integrated study of language evolution.
Language Dynamics and Change.
2020; 10: 188–229. Publisher Full Text
- Sagart L, Jacques G, Lai Y, et al.:
Dated language phylogenies shed light on the ancestry of Sino-Tibetan.
Proc Natl Acad Sci U S A.
2019; 116(21): 10317–10322. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Schweikhard NE:
Semantic promiscuity as a factor of productivity in word formation.
Computer-Assisted Language Comparison in Practice.
2018; 1(11). Reference Source
- Société de Linguistique de Paris: Statuts.
Bulletin de la Société de Linguistique de Paris.
1871; 1: III–IV.
- Starostin SA:
Sravniteln’o-istoričeskoe jazykoznanie i leksikostatistika. In: S. V. Kullanda, Ju. D. Longinov, A. Ju. Militarev, E. Je. Nosenko, and V. A. Shnirelan, editors,
Materialy k diskussijam na konferencii.
Institut Vostokovedenija, Moscow, 1989; 1: 3–39.
- Tinbergen N:
On aims and methods of ethology.
Zeitschrift fur Tierpsychologie.
1963; 20(4): 410–433. Publisher Full Text
- Trask RL, editor.:
The dictionary of historical and comparative linguistics. Edinburgh University Press, Edinburgh, 2000. Publisher Full Text
- Turchin P, Peiros L, Gell-Mann M:
Analyzing genetic connections between languages by matching consonant classes.
J Lang Relat.
2010; 3: 117–126. Reference Source
- Urban M:
Analyzability and semantic associations in referring expressions: A study in comparative lexicology. Phd, Leiden University, Leiden, 2012. Reference Source
- Urban M:
Motivation by formally analyzable terms in a typological perspective: An assessment of the variation and steps towards explanation. In: Päivi Juvonen and Maria Koptjevskaja-Tamm, editors, The lexical typology of semantic shifts, De Gruyter Mouton, Berlin and New York, 2016; 555576. Publisher Full Text
- Vaswani A, Shazeer N, Parmar N, et al.:
Attention is all you need. In: I. Guyon, U. Von Luxburg, S. Bengio, H. Wallach, R. Fergus S. Vishwanathan, and R. Garnett, editors,
Advances in Neural Information Processing Systems.
Curran Associates, 2017; 30. : 1–11. Reference Source
- Weinreich U, Labov W, Herzog MI:
Empirical foundations for a theory of language change. In: Winfred Philipp Lehmann and Yakov Malkiel, editors,
Directions for historical linguistics: A symposium.
(-195?) University of Texas Press, Austin, 1968; 95–189. Reference Source
- Whewell WDD:
The philosophy of the inductive sciences, founded upon their history, volume 2. John W. Parker, London, 2 edition, 1847; 2. Reference Source
- Wilson EO:
Consilience. The unity of knowledge. Vintage Books, New York, 1998. Reference Source