Introduction
Synthetic populations generated with LLM agents are becoming a practical tool for exploratory social research, user research, public-policy prototyping, education, and market-research workflows. Prior work has shown how language models can be used to simulate human samples, replicate selected human-subject study patterns, support interactive generative-agent simulations, and assist marketing or consumer-research ideation (Argyle et al., 2023; Aher et al., 2023; Park et al., 2023; Arora et al., 2025; De Freitas et al., 2025; Toubia et al., 2025). In these settings, researchers define synthetic participants or population segments and ask agents to produce open-ended responses to prompts. The prompts may resemble survey questions, interviews, product-reaction tasks, deliberation exercises, or group-style discussions. This workflow can make early-stage exploration faster and cheaper, but it introduces a new measurement problem: generated answers are mediated by a shared model, shared prompting environment, and shared generation process.
The resulting outputs can appear coherent and fluent while still being methodologically fragile. A research team may configure agents with different demographic, behavioural, or preference attributes, yet the generated answers may reuse similar vocabulary, examples, argument order, or rhetorical templates. This concern connects with evidence that generative AI can homogenize open-ended responses and reduce collective content diversity in some settings (Anderson et al., 2024; Doshi and Hauser, 2024; Zhang et al., 2025). If outputs are reviewed manually, local convergence can be missed because the responses remain plausible. If outputs are summarized into aggregate themes, local near-duplicates may disappear from view. For synthetic-population studies, response convergence is therefore both a validity concern and an observability concern.
This issue is related to broader concerns about homogenization in generative AI, model collapse, synthetic-text feedback loops, and the evaluation of LLM-based agents (Guo et al., 2024a; Shumailov et al., 2024; Chang et al., 2024; Guo et al., 2024b; Mohammadi et al., 2025). It is also distinct from those topics in one important respect: researchers using synthetic populations often need a lightweight operational signal during study design. They need to know whether a prompt, population design, or model configuration is producing responses that are lexically too similar before they invest in deeper semantic analysis, human comparison, or domain-specific review.
The method proposed here treats response-convergence monitoring as a deterministic post-processing step. It does not claim to measure the full validity of a synthetic population. It does not infer whether an answer is true, representative, persuasive, or human-like. Instead, it focuses on a narrower and reproducible question: when several generated agents answer the same prompt, how much lexical overlap is present, where are the local extremes, and which response pairs should be inspected?
A lexical baseline is useful because it is transparent, cheap to compute, and easy to reproduce. Set-overlap measures such as Jaccard similarity are long established for comparing token sets, entropy provides an interpretable measure of concentration, distinct-n metrics have been used to monitor diversity in generated text, and automatic text-generation evaluation has long considered overlap and degeneration trade-offs (Jaccard, 1901; Shannon, 1948; Papineni et al., 2002; Manning et al., 2008; Li et al., 2016; Holtzman et al., 2020). Unlike embedding-based similarity, lexical overlap can be recalculated without model access or hidden external dependencies. Unlike manual review, it can be applied consistently across many runs. It is also interpretable: a high maximum similarity can be traced to a concrete pair of responses, and a low diversity score can be connected to repeated tokens or phrases.
The contribution of this Method Article is threefold. First, it defines a platform-independent data model and algorithmic workflow for monitoring response convergence in generated agent populations. Second, it provides an open-source reference implementation with data-quality counters, duplicate handling, pairwise similarity distributions, and optional pair-level diagnostics. Third, it documents article-specific controlled examples and initial validation scenarios that show how the method behaves under known convergence conditions. The article also includes a small platform-generated applied example to illustrate portability to a normalized export without making the method dependent on that platform.
Methods
The proposed method can be applied after a synthetic-population run or embedded inside a generation pipeline. The only required input is a set of generated answers with a question identifier, an agent identifier, and response text. Optional metadata such as run identifier, model, temperature, population segment, or timestamp can be preserved for later grouping and audit. The method is deliberately independent of model internals, sampling probabilities, embedding services, and orchestration frameworks.
Method design requirements
The method was designed around five requirements, following common expectations for reproducible computational research and research-software citation (Sandve et al., 2013; Smith et al., 2016; Wilkinson et al., 2016; Wilson et al., 2017). First, it must be platform agnostic: it should accept ordinary tabular or JSON response exports rather than depend on a specific agent framework. Second, it must be lightweight: the default metrics must run locally and add negligible overhead compared with generation. Third, it must be reproducible: thresholds, normalization settings, input records, and outputs must be exportable and rerunnable. Fourth, it must be interpretable: the metrics should be understandable to research teams without specialist model-evaluation infrastructure. Fifth, it must be extensible: lexical metrics should provide the baseline layer while allowing semantic, syntactic, and human-baseline metrics to be added later.
Framework architecture
The method is organized as a five-stage pipeline: response ingestion, normalization, metric computation, alerting, and reporting (
Figure 1). This separation keeps the procedure reusable. Ingestion handles conversion into canonical response records. Normalization defines the text representation used for comparison. Metric computation produces continuous scores. Alerting converts selected scores into inspection flags. Reporting stores results in a stable machine-readable object; the corresponding layer responsibilities are summarized in
Table 1.
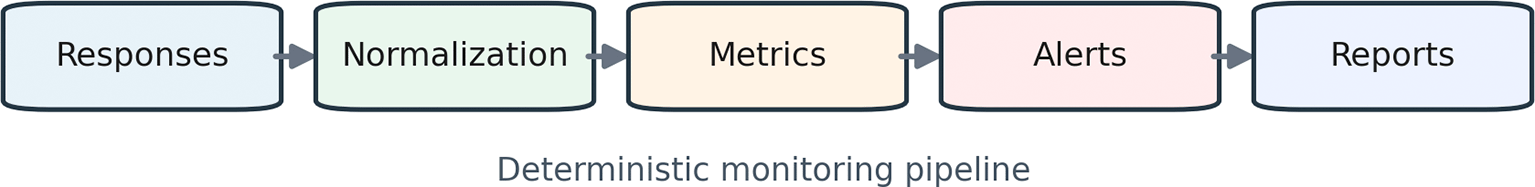
Figure 1. Deterministic response-convergence monitoring pipeline used by the framework.
Table 1. Framework layers and responsibilities.
| Layer | Responsibility | Output |
|---|
| Response ingestion | Load response records or interaction exports and convert them into canonical response records. | List of records with question, agent, text, and optional metadata. |
| Normalization | Apply deterministic text preprocessing before comparison. | Token sequences and token sets. |
| Metric computation | Calculate pairwise lexical overlap and vocabulary-diversity metrics by question. | Per-question metric rows. |
| Alerting | Apply configurable rules to identify questions requiring inspection. | Alert flags and run-level counts. |
| Reporting | Persist outputs in a machine-readable format for audit and rerun. | JSON object with summary and by_question blocks. |
Input data model
The canonical input unit is a response record (
Table 2). The minimum required fields are question_id, agent_id, and text. Optional metadata fields allow researchers to preserve run identifiers, model names, sampling settings, population or segment identifiers, and timestamps. The design is intentionally simple because most generation workflows can export this information without changing their internal state model.
Table 2. Generic response-record schema.
| Field | Required | Role |
|---|
| question_id | Yes | Groups responses that answer the same question, task, or prompt. |
| agent_id | Yes | Identifies the synthetic participant or agent producing the answer. |
| text | Yes | Contains the generated answer to be evaluated. |
| run_id | No | Links records to a study execution or batch. |
| model | No | Stores the model or deployment used for generation. |
| temperature | No | Stores the sampling temperature or analogous setting. |
| population_id | No | Links the answer to a population, segment, or scenario. |
| timestamp | No | Stores generation or export time for traceability. |
The reference implementation accepts common aliases such as question, content, answer, response, agentId, and participant_id. This reduces adoption friction when response data come from notebooks, dashboards, simulators, or annotation files. The method itself does not require a database schema or a specific application backend. Similarly, exports from external platforms can be analysed after normalization to the required question_id, agent_id, and text fields.
Configuration validation and record handling
Configuration values, including the options and defaults in
Table 3, are validated before metrics are computed. The maximum-similarity threshold must lie between 0 and 1, the minimum number of answers must be at least two, the minimum token length must be at least one, and duplicate-record handling must be selected from a documented set of policies. These checks are included to prevent silent misconfiguration when the method is used in scripts, notebooks, or automated study pipelines.
Table 3. Core configuration options and defaults in synthetic-response-metrics 0.2.5.
| Configuration item | Default | Purpose |
|---|
| threshold_max_similarity
| 0.70 | Provisional alert threshold applied to maximum Jaccard similarity. |
| min_answers | 2 | Minimum valid responses required before pairwise metrics are computed. |
| language | auto | Selects default stopwords for English/Spanish or combined mode. |
| min_token_length
| 3 | Filters short tokens after normalization. |
| duplicate_policy | latest | Controls repeated question-agent records: latest, first, error, or keep_all. |
| include_pairs | False | Controls whether top similar agent pairs are included in the JSON output. |
The default duplicate policy is latest. This is useful when a pipeline emits intermediate and final answers for the same question-agent pair. Alternative policies allow users to keep the first response, raise an error, or keep all repeated records by treating each occurrence as a separate response instance. Regardless of the policy, duplicate_records_count is reported so that repeated records are visible before interpreting the metric values.
Method assumptions
The current method assumes that responses are open-ended text answers and that convergence should be evaluated within each question rather than across unrelated prompts. It also assumes that the researcher is interested in lexical behaviour as an interpretable baseline. Two answers can be semantically similar while using different words, and two answers can reuse words while making different claims. For this reason, the method flags potential lexical convergence rather than claiming complete semantic equivalence.
The default threshold of 0.70 for maximum Jaccard similarity is provisional. It is a transparent starting point for inspection rather than a universal cutoff. Researchers should report the threshold, the normalization settings, the number of valid answers, and the number of response pairs. These denominators matter because a larger population creates more pairwise opportunities for local overlap.
Algorithmic workflow
The procedure can be described as a deterministic algorithm (
Table 4). First, response records are loaded from CSV, JSON, or JSONL. Second, public configuration values are validated. Third, repeated question-agent records are handled according to the duplicate policy. Fourth, records are grouped by question_id. Fifth, each response is normalized using case folding, separator replacement, tokenization, stopword filtering, and minimum token-length filtering. Sixth, empty responses after normalization are excluded from pairwise metric computation while their exclusion is counted. Seventh, all valid answer pairs are generated within each question. Eighth, lexical overlap, containment, duplicate, diversity, and length diagnostics are computed. Ninth, the provisional alert rule is applied. Finally, results are written as a JSON object with summary and by_question blocks.
Table 4. Algorithmic workflow for response-convergence monitoring.
| Step | Operation | Reproducibility output |
|---|
| 1 | Load records from CSV, JSON, or JSONL. | records_total and input schema. |
| 2 | Validate configuration and duplicate policy. | config block in JSON output. |
| 3 | Normalize response text deterministically. | language, stopwords, and min_token_length. |
| 4 | Group valid answers by question. | questions_total and questions_evaluated. |
| 5 | Generate answer pairs within each question. | answers_count and pairs_count. |
| 6 | Compute lexical and diversity metrics. | by_question metrics and run summary. |
| 7 | Apply provisional inspection flag. | convergence_alert field, shown as Alert in manuscript tables. |
| 8 | Write machine-readable output. | summary and by_question JSON blocks. |
Normalization pipeline
Each response is normalized before metrics are computed. The default pipeline applies Unicode-aware case folding, replaces punctuation and non-alphanumeric separators with spaces, splits on whitespace, removes a small stopword list, and excludes tokens shorter than the configured minimum length. The default minimum token length is three characters. Users can select English, Spanish, automatic combined stopwords, or a custom newline-delimited stopword file.
Normalization is deterministic and configuration-driven. This matters because convergence scores can change when stopwords, token-length thresholds, or language-specific preprocessing rules change. The method therefore treats normalization settings as part of the reproducibility record. Responses that become empty after normalization are excluded from pairwise metric computation, but the exclusion is counted explicitly as excluded_empty_after_normalization.
Lexical metric suite
The metric suite is lexical, deterministic, and lightweight. For each question with enough valid answers, the method forms all unordered response pairs and calculates Jaccard similarity over normalized token sets. Jaccard similarity is used because it is deterministic, bounded between 0 and 1, and directly inspectable as overlap divided by union (Jaccard, 1901; Manning et al., 2008). The method then reports average, maximum, minimum, median, p90, and standard deviation of pairwise similarity. This distributional view is useful because a run may have low average overlap while still containing one highly convergent pair.
For each question q, let R_q be the set of valid normalized responses and let n_q = |R_q|. Each response r_i is represented by a normalized token sequence T_i and a token set S_i. For each unordered pair (i, j), the method computes J(S_i, S_j) = |S_i ∩ S_j|/|S_i ∪ S_j|and C(S_i, S_j) = |S_i ∩ S_j|/min(|S_i|,|S_j|), where J is Jaccard similarity and C is containment similarity. avg_jaccard_similarity is the mean of J across all unordered pairs; max_jaccard_similarity, min_jaccard_similarity, median_jaccard_similarity, p90_jaccard_similarity, and std_jaccard_similarity are defined analogously over the same pairwise Jaccard distribution. max_containment_similarity is the maximum C value across pairs, and exact_duplicate_count is the number of unordered pairs with identical normalized token sequences.
Diversity and length diagnostics are computed from the normalized token sequences for each question. distinct_1 is the number of unique normalized unigrams divided by the total number of normalized unigram tokens; distinct_2 is the number of unique normalized bigrams divided by the total number of normalized bigrams; token_entropy is Shannon entropy over normalized token frequencies; mean_response_tokens is the mean normalized-token length; and response_length_cv is the coefficient of variation of normalized response length. Operationally, the method collects valid responses, normalizes them into token sequences and token sets, generates unordered pairs, computes pairwise Jaccard and containment, aggregates the pairwise distributions, computes diversity and length diagnostics, and then applies the configured inspection rule.
The reporting layer combines the lexical overlap, containment, duplicate, diversity, and length diagnostics listed in
Table 5. Vocabulary-level diversity is reported through lexical_unique_ratio, distinct_1, distinct_2, token entropy, mean response length, and response-length coefficient of variation. In the current implementation, lexical_unique_ratio is equivalent to distinct_1: both are computed as the number of unique normalized unigram tokens divided by the total number of normalized unigram tokens across valid responses for a question. The manuscript retains lexical_unique_ratio as a descriptive reporting name and distinct_1 for consistency with the text-generation diversity literature. These metrics provide complementary views of concentration: unique-ratio scores summarize token-type reuse, distinct-n scores capture unigram and bigram diversity, and entropy increases when token use is more evenly spread (Shannon, 1948; Li et al., 2016; Zhu et al., 2018). They are not substitutes for semantic validity, but they help identify response sets dominated by repeated vocabulary or phrasing.
Table 5. Lexical and diversity metrics included in synthetic-response-metrics 0.2.5.
| Metric | Computation | Purpose |
|---|
| Jaccard distribution | Average, maximum, minimum, median, p90, and standard deviation of pairwise token-set Jaccard scores. | Summarizes both typical and local lexical convergence. |
| max_containment_similarity
| Intersection size divided by the smaller token set for each response pair. | Flags subset-like overlap when answer lengths differ. |
| lexical_unique_ratio and distinct_1 | Unique normalized unigrams divided by total normalized unigrams. | Reports vocabulary breadth using a descriptive name and a literature-aligned distinct-n name. |
| distinct_2 | Unique normalized bigrams divided by total normalized bigrams. | Captures repeated short phrase patterns. |
| token_entropy | Shannon entropy over normalized token frequencies. | Captures concentration or spread of vocabulary use. |
| length diagnostics | Mean response tokens and response-length coefficient of variation. | Separates lexical convergence from length effects. |
| exact_duplicate_count
| Number and proportion of response pairs with identical normalized token sequences. | Identifies direct repetition after normalization. |
Alerting and reporting
The method separates continuous metric values from alerting rules. Continuous scores are the primary result and should be reported for all runs. Alerts are operational aids that identify questions requiring inspection. The default rule flags a question when max_jaccard_similarity is greater than or equal to the configured threshold_max_similarity, which is 0.70 by default, and at least two valid answers are available. In the JSON output, convergence_alert is the canonical Boolean summary field indicating whether the configured maximum-similarity rule was triggered for at least one evaluated question. Per-question rows use alert for the same rule at question level, and manuscript tables use the shorter label Alert as a human-readable column heading.
When include_pairs is enabled, the output also includes top_similar_pairs for each evaluated question. Each row identifies the two agent identifiers, the original record indexes, Jaccard similarity, and containment similarity. Together with the alert and summary fields in
Table 6, this diagnostic is designed for interpretability: an alert should not only tell researchers that potential lexical convergence may be present, but also point to the response pair that triggered inspection.
Table 6. Reporting and diagnostic fields formalized in version 0.2.5.
| Output field family | Examples | Interpretation |
|---|
| Run summary | questions_total, questions_evaluated, records_total, runtime_ms | Documents scope and reproducibility context. |
| Data-quality counters | missing_text_count, missing_agent_id_count, duplicate_records_count
| Makes input problems visible before metric interpretation. |
| Pairwise distributions | avg/max/min/median/p90/std_jaccard_similarity
| Shows both central tendency and local extremes. |
| Diversity diagnostics | distinct_1, distinct_2, token_entropy, mean_response_tokens
| Separates repeated wording from broader vocabulary patterns. |
| Pair-level explanations | top_similar_pairs with agent ids and record indexes | Makes alerts auditable and inspectable. |
Reference implementation
The reference implementation is the Python package synthetic-response-metrics. In this article, the package is used to make the method executable and reproducible; the methodological contribution is the monitoring procedure rather than the package alone. The implementation exposes ResponseRecord, DispersionConfig, compute_dispersion, and DispersionResult through the public API, and provides a command-line interface for reproducible examples.
srm compute examples/ore_validation/convergence_scenarios/high_convergence.csv --include-pairs --language en --output examples/ore_validation/convergence_scenarios/high_convergence_results.json
The package currently supports CSV, JSON, and JSONL inputs. It includes command-line options for language, custom stopwords, duplicate handling, pair diagnostics, alert threshold, minimum answers, and minimum token length. The reference implementation, synthetic-response-metrics (Alvarez et al., 2026), is archived as version v0.2.5 at https://doi.org/10.5281/zenodo.20537552 and is available from https://github.com/ralvarezmartin/synthetic-response-metrics under the MIT License.
Article-specific validation and worked examples
Open Research Europe guidance for Method Articles indicates that validation results should be provided where available, and that use cases or worked examples are appropriate when full method validation has not yet been completed. This article therefore uses controlled synthetic examples created specifically for the manuscript. The examples test whether the method behaves as expected under known data-quality, convergence, population-size, and diagnostic conditions. They do not establish domain-specific thresholds and they do not replace validation against human-response baselines.
Validation design
The validation design contains four controlled blocks. The controlled data-quality example tests empty text, duplicate records, exact duplicate pairs, and diverse answers in one compact file. The convergence scenarios compare low, moderate, and high lexical overlap while keeping the number of questions and agents constant. The population-size sensitivity examples increase N from 3 to 5 and 10 while preserving comparable prompts. The diagnostic case creates a local high-overlap pair among otherwise distinct responses. The applied platform-generated example is kept separate from these controlled checks, so expected metric behaviour and operational portability remain distinct concerns (
Figure 2).
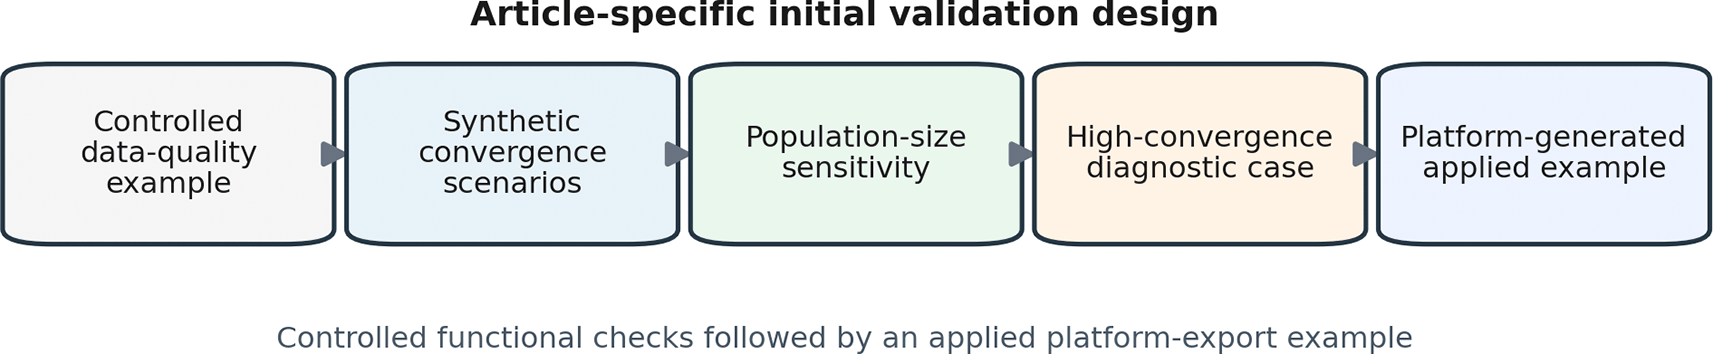
Figure 2. Article-specific initial validation design.
Synthetic dataset construction
The validation datasets were constructed specifically for this manuscript as controlled examples rather than as samples from a human-response population. Each dataset was designed to exercise a predefined behaviour of the method. The controlled data-quality example includes deliberately inserted missing text, repeated question-agent records, and exact duplicate response pairs. The low-, moderate-, and high-convergence scenarios manipulate lexical overlap while keeping the number of questions and agents constant. The population-size examples vary the number of agents while preserving comparable prompt structure, so that the effect of increasing the number of response pairs can be inspected. The diagnostic case introduces one locally high-overlap pair among otherwise distinct responses.
The datasets were created to support functional checking, reproducibility, and manual inspectability. They should therefore be interpreted as article-specific controlled examples and sanity checks, not as evidence that the default threshold generalizes across domains, populations, models, or prompt types. The archived release contains the input files, expected JSON outputs, and derived table files used to reproduce the manuscript results, with the article-specific datasets listed in
Table 7.
Table 7. Validation datasets created for this article.
| Dataset | Questions | Agents | Records | Purpose |
|---|
| Controlled data-quality example | 3 | 4 | 13 | Exercises empty text, duplicate records, exact duplicates, and diverse answers. |
| Low-convergence scenario | 3 | 6 | 18 | Shows expected behaviour when responses are lexically diverse. |
| Moderate-convergence scenario | 3 | 6 | 18 | Shows expected behaviour when agents share core vocabulary but vary wording. |
| High-convergence scenario | 3 | 6 | 18 | Shows expected alert behaviour when many answers reuse the same wording. |
| Population-size sensitivity N = 3 | 2 | 3 | 6 | Provides the smallest population-size sensitivity condition. |
| Population-size sensitivity N = 5 | 2 | 5 | 10 | Adds pairwise opportunities while preserving comparable prompts. |
| Population-size sensitivity N = 10 | 2 | 10 | 20 | Shows how pair count and vocabulary overlap change with larger N. |
| High-convergence diagnostic case | 1 | 5 | 5 | Demonstrates pair-level traceability through top_similar_pairs. |
All validation data are synthetic and article-specific. The examples are intentionally small so that readers can inspect the inputs manually and rerun the outputs through the command-line interface. This is important for a Method Article: the validation should not only report values, but also demonstrate how another researcher could reproduce the procedure.
Controlled data-quality example
The controlled example contains three questions and four agents. It includes one empty answer cell, one repeated question-agent record, one exact duplicate response pair, and otherwise diverse answers. The purpose is to show that data-quality counters and convergence metrics are reported together in the output (
Table 8). A high similarity score should not be interpreted before checking whether missing text, repeated records, or exact duplicates explain the signal.
Table 8. Controlled data-quality example metrics.
| Question | Raw | Valid | Missing text | Duplicates | Pairs | Max Jaccard | Distinct-2 | Alert |
|---|
| cq1 | 5 | 4 | 1 | 1 | 6 | 1.000 | 0.724 | True |
| cq2 | 4 | 4 | 0 | 0 | 6 | 0.000 | 1.000 | False |
| cq3 | 4 | 4 | 0 | 0 | 6 | 0.000 | 1.000 | False |
The controlled example shows that an alert can be technically correct while still requiring contextual interpretation. The exact duplicate pair produces a maximum Jaccard similarity of 1.0, while the summary also records the missing text and duplicate record. This supports an audit-first reading pattern: inspect data-quality counters, then pairwise distributions, then the response pair responsible for an alert.
Synthetic convergence scenarios
The convergence-scenario datasets use the same three questions and six agents. The low-convergence scenario uses diverse vocabulary and examples. The moderate-convergence scenario reuses core task vocabulary while varying sentence structure. The high-convergence scenario deliberately repeats near-identical wording by question. This controlled design checks whether the metrics respond in the expected direction when lexical overlap is manipulated directly: average and maximum Jaccard similarity increase, while lexical uniqueness decreases, as the scenario moves from low to high convergence (
Figure 3;
Table 9).
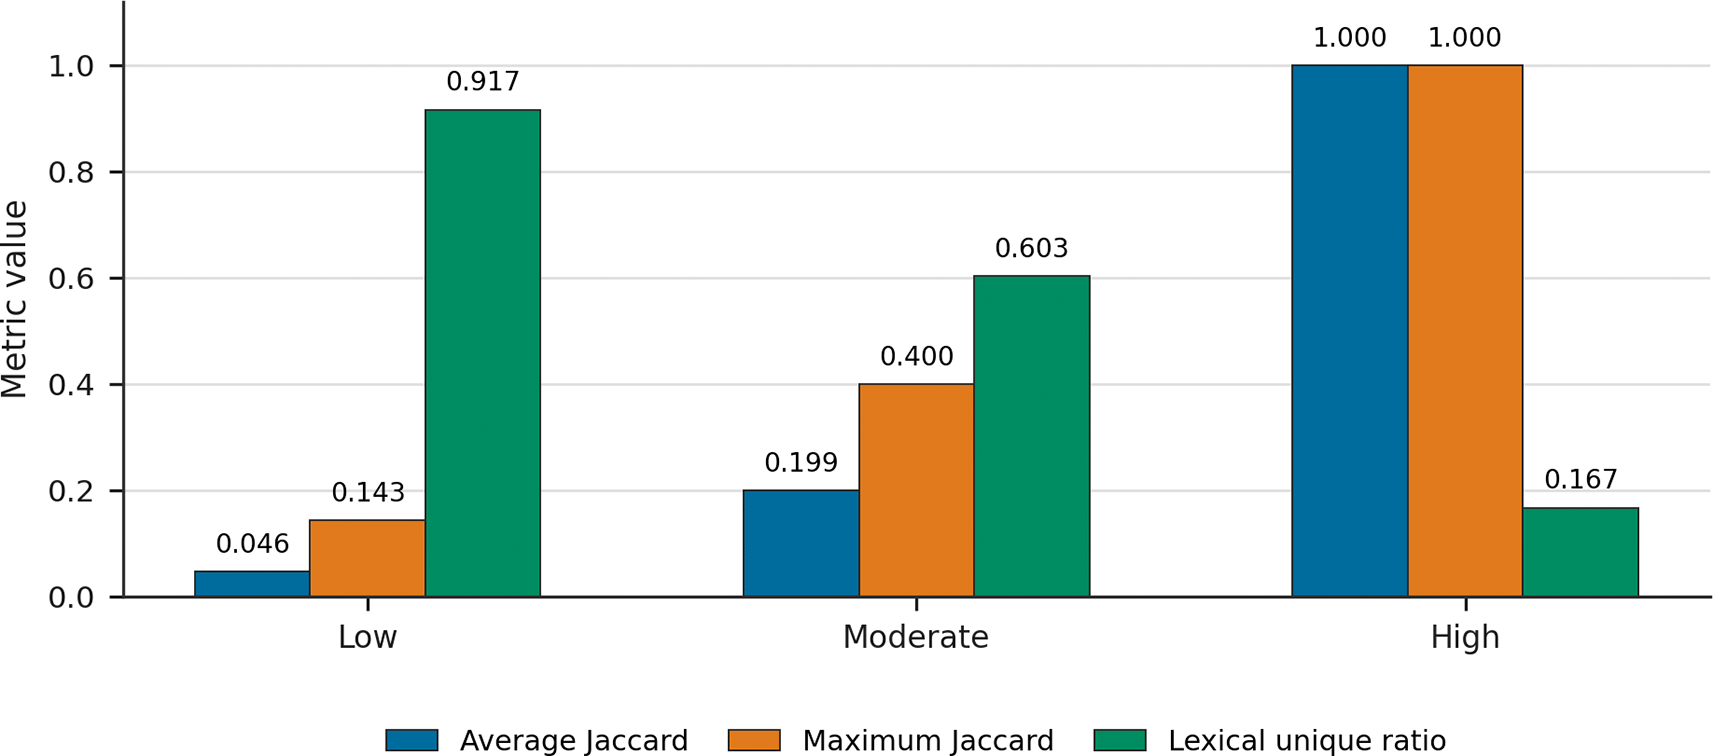
Figure 3. Metric response across low-, moderate-, and high-convergence scenarios.
Table 9. Synthetic convergence scenario comparison.
| Scenario | Questions | Records | Avg. Jaccard | Max. Jaccard | Lexical unique | Distinct-2 | Alert |
|---|
| Low | 3 | 18 | 0.046 | 0.143 | 0.917 | 0.964 | False |
| Moderate | 3 | 18 | 0.199 | 0.400 | 0.603 | 0.907 | False |
| High | 3 | 18 | 1.000 | 1.000 | 0.167 | 0.167 | True |
The comparison shows the intended separation between similarity and diversity diagnostics. In the low-convergence scenario, average and maximum Jaccard similarity remain low while lexical diversity is high. In the moderate scenario, shared vocabulary increases average overlap but remains below the provisional alert threshold. In the high scenario, repeated wording produces maximum similarity of 1.0 and a positive alert. Distinct-2 and lexical unique ratio decrease when repeated phrases dominate the response set.
Population-size sensitivity analysis
The population-size examples use two comparable questions and increase the number of agents from 3 to 5 and 10. This analysis is not intended to estimate a general scaling law. Its purpose is to demonstrate a reporting requirement: as N increases, pairs_count grows quickly, creating more opportunities for local overlap. A higher maximum similarity can therefore reflect a meaningful near-duplicate pair, a larger opportunity set, or both, which is why answers_count and pairs_count should be interpreted alongside similarity metrics (
Figure 4;
Table 10).
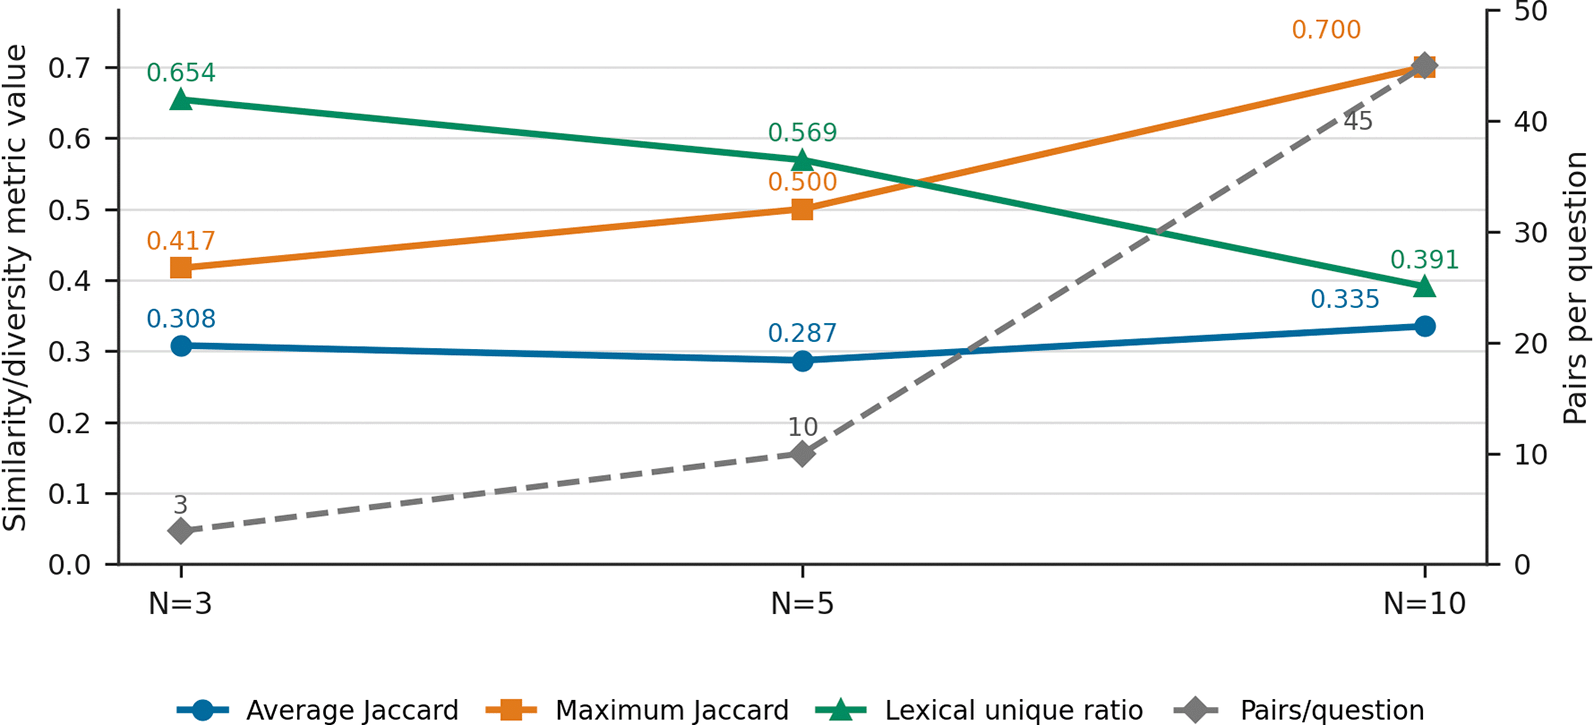
Figure 4. Population-size sensitivity across N = 3, N = 5, and N = 10.
Table 10. Population-size sensitivity analysis.
| Condition | Questions | Records | Pairs/question | Avg. Jaccard | Max. Jaccard | Lexical unique | Alert |
|---|
| N = 3 | 2 | 6 | 3 | 0.308 | 0.417 | 0.654 | False |
| N = 5 | 2 | 10 | 10 | 0.287 | 0.500 | 0.569 | False |
| N = 10 | 2 | 20 | 45 | 0.335 | 0.700 | 0.391 | True |
The N = 10 condition reaches the provisional maximum-similarity threshold while the smaller conditions do not. This does not mean that larger populations are less valid. It shows why maximum similarity should be interpreted alongside answers_count, pairs_count, average similarity, and diversity metrics. The lexical unique ratio also declines as more agents reuse common task vocabulary, which is expected in many prompt-controlled response sets.
High-convergence diagnostic case
The diagnostic example contains one question and five agents. Two agents produce highly similar answers about onboarding, privacy controls, pricing notes, and support contact information; the other agents provide distinct concerns. This creates a local convergence pattern rather than a complete response-set collapse, and the pair-level output in
Table 11 shows how the method makes that local pattern inspectable.
Table 11. High-convergence diagnostic pair.
| Question | Top pair | Pair Jaccard | Containment | Avg. Jaccard | Max. Jaccard | Alert |
|---|
| dq1 | a1-a2 | 0.833 | 0.909 | 0.093 | 0.833 | True |
The top_similar_pairs field makes the alert auditable. Instead of reporting only that the question crossed a threshold, the output identifies the pair responsible for the highest overlap and reports both Jaccard and containment similarity. This supports manual inspection before interpreting the alert as substantive convergence.
Applied platform-generated example
The controlled synthetic examples above test expected behaviours of the method under known conditions. To complement them, we generated a small applied example from MadSynthesis and converted the export to the same platform-independent response-record schema. This example is included as an operational portability check: it shows that the method can process platform-generated synthetic data once responses are represented with question_id, agent_id, and text.
The scenario was deliberately fictional and publication-safe: a generic city-service booking app for local public events, appointments, and reminders. The run used 10 synthetic agents, three open-ended questions, English-language responses, and 30 normalized response records, with aggregate metrics reported in
Table 12. The generated files contain no human respondent data, no client data, no personal data, no commercially sensitive prompt content, and no confidential scenario information. MadSynthesis is used here only as the source of a realistic platform export, not as a dependency of the method.
Table 12. Applied platform-generated example summary.
| Metric | Value |
|---|
| Run ID | ore-platform-20260528T095605Z-cd16d40a |
| Population ID | ore_platform_fictional_city_services_n10
|
| Questions | 3 |
| Questions evaluated | 3 |
| Records total | 30 |
| Valid records total | 30 |
| Overall average Jaccard similarity | 0.15 |
| Overall maximum Jaccard similarity | 0.31 |
| Overall average lexical unique ratio | 0.55 |
| Overall average distinct-2 | 0.84 |
| Overall average token entropy | 7.52 |
| Overall maximum containment similarity | 0.489 |
| Duplicate records | 0 |
| Missing text records | 0 |
| Convergence alert | False |
| Runtime, ms | 4 |
The reproducibility artifacts include the normalized CSV and JSONL inputs, the metric JSON output, an aggregate summary table, per-question metrics, top similar pairs, metadata, a dataset card, and a dedicated platform_generated/reproducibility_commands.md file. The per-question and top-pair tables are provided as extended data rather than expanded in the main text.
In this specific synthetic run, the method did not flag potential lexical convergence under the provisional 0.70 maximum-similarity threshold. This supports operational portability to a platform export, but it should not be read as general threshold calibration, human-response validation, or an evaluation of the overall quality of MadSynthesis.
CLI reproducibility check
Every validation example includes the input file and the expected JSON output generated by the command-line interface. The commands are listed in the archived repository documentation, including the relevant README and reproducibility_commands.md files. The generated outputs contain schema_version 0.2, the effective configuration, data-quality counters, distributional lexical metrics, and optional top similar pair diagnostics. The manuscript tables are derived from the archived CSV files, which summarize the JSON outputs. Runtime is retained as a diagnostic field for transparency and may vary slightly across machines or repeated executions.
srm compute examples/ore_validation/population_size/n10.csv --include-pairs --language en --output examples/ore_validation/population_size/n10_results.json
Operational overhead
The lexical computation runs locally and compares normalized response sets within each question. For a question with n_q valid responses, the method computes n_q(n_q - 1)/2 unordered response pairs, so pairwise similarity computation scales as O(n_q^2) per question, excluding the cost of normalization. Across multiple questions, the total number of pairwise comparisons is the sum of n_q(n_q - 1)/2 over all evaluated questions. In the article-specific validation examples, all runs complete at millisecond scale, but larger synthetic populations should report runtime together with answers_count and pairs_count.
Practical guidance for adoption
Researchers applying the method to a new synthetic-population study should report the response schema, normalization settings, duplicate policy, minimum answer threshold, alert threshold, software version, answers_count, and pairs_count. The raw number of records and the number of valid answers should be reported separately, because empty responses, missing identifiers, and duplicate records can otherwise make the metric denominator ambiguous. If include_pairs is enabled, the top similar pairs should be inspected before interpreting an alert as substantive convergence;
Table 13 links these reporting checks to common interpretation patterns.
Table 13. Practical interpretation guide for common diagnostic patterns.
| Situation | Diagnostic signal | Recommended interpretation |
|---|
| High max similarity, low average similarity | One or a few top_similar_pairs dominate the alert. | Inspect local convergence; do not assume the whole population collapsed. |
| High containment similarity, moderate Jaccard | A short answer is largely contained in a longer answer. | Check whether one response paraphrases or extends another. |
| Low distinct-2 or low token entropy | Vocabulary or phrase patterns are concentrated. | Review prompts for repeated wording or overly narrow answer framing. |
| insufficient_data status | Too few valid answers after normalization. | Report the exclusion reason and avoid interpreting pairwise metrics for that question. |
| Duplicate records present | duplicate_records_count is greater than zero. | Declare the duplicate policy and verify that repeated records were handled as intended. |
| Higher max similarity with larger N | pairs_count increases as more agents are included. | Report denominators and avoid comparing max values without population-size context. |
Discussion
The method contributes an observability layer for synthetic-population research. It does not attempt to replace qualitative interpretation, human validation, semantic similarity assessment, or downstream task evaluation. Instead, it provides a reproducible signal for a narrower question: are generated agents producing responses that are lexically too similar for a given prompt, population, model, and configuration?
This framing matters because convergence can be local. A response set may have low average similarity while still containing one pair of near-duplicate answers. Maximum Jaccard similarity is therefore included alongside average similarity, and distributional summaries such as median, p90, and standard deviation make the pairwise pattern more visible. Conversely, vocabulary diversity can remain high even when semantic content is aligned, which is why lexical unique ratio and distinct-n metrics should not be interpreted as complete validity scores.
The method also relates to wider concerns about homogenization and model collapse. Those concerns are often discussed at the level of training data, creative output, or model ecosystems. The present method addresses a more operational layer: during a synthetic-population study, the researcher needs to know whether the specific generated answer set contains repeated wording or local near-duplicates. This local view does not solve the broader problem, but it makes one observable failure mode easier to report.
Population size is a key interpretive factor. Because the method compares pairs within each question, the number of possible pairs increases quickly as N grows. For N = 3 there are three pairs per question, for N = 5 there are ten, and for N = 10 there are forty-five. A high maximum similarity is more likely to appear when there are more pairs. For this reason, max_jaccard_similarity should not be compared across runs without reporting answers_count and pairs_count.
The main limitation of the current version is its lexical scope. Two answers can express the same opinion with different words, producing low lexical overlap despite semantic convergence. Two answers can also reuse words while making different claims. This limitation is deliberate because lexical metrics are transparent, inexpensive, and reproducible. The method establishes a lexical baseline before introducing more complex metrics that may depend on embedding models, parsers, or human-labelled reference data.
The second limitation is validation scale. The examples in this manuscript are controlled synthetic examples created to test expected behaviour, reproducibility, and diagnostic interpretability. They do not establish general-purpose thresholds, and they do not compare synthetic response distributions against human-response baselines. Future validation should include larger populations, additional task types, different model families, domain-specific prompts, and expert assessment of whether flagged response pairs represent excessive convergence. The applied platform-generated example adds an operational portability check, but it remains synthetic and scenario-specific; validation with real domains, human-response baselines, or external benchmarks remains future work.
The default threshold of 0.70 is therefore provisional. It is useful because it is explicit and easy to audit, but it should be treated as a starting point for inspection rather than a stable validity boundary. In some domains, lower thresholds may be useful because repeated phrasing is problematic; in others, higher thresholds may be appropriate because task wording naturally constrains vocabulary.
The planned extension path includes semantic similarity, syntactic-template monitoring, and human-baseline calibration (
Table 14). Semantic similarity can flag potential convergence when agents use different vocabulary to express similar meanings, but it requires model and version documentation for embedding-based methods (Reimers and Gurevych, 2019; Zhang et al., 2020). Syntactic-template monitoring can identify repeated answer structures (Shaib et al., 2024). Human-baseline calibration can help determine whether synthetic dispersion is narrower, broader, or differently shaped than observed human response variation.
Table 14. Planned extensions beyond the current lexical method.
| Extension | Motivation | Expected requirement |
|---|
| Semantic similarity | Flag meaning-level convergence when wording differs. | Optional embedding model and documented model/version. |
| Syntactic-template monitoring | Identify repeated answer structures or rhetorical templates. | Tokenizer/parser or lightweight pattern extractor. |
| Human-baseline calibration | Interpret synthetic dispersion relative to observed human response variation. | Human or benchmark response dataset with ethics approval where needed. |
| Longitudinal monitoring | Track convergence across repeated runs or model updates. | Stable run metadata and archived output payloads. |
Conclusions
This Method Article presents a lightweight computational method for monitoring response convergence in LLM-based synthetic populations. The method uses a generic response-record schema, deterministic normalization, interpretable lexical and diversity metrics, data-quality counters, threshold-based inspection flags, optional pair-level diagnostics, and reproducible JSON outputs.
The central methodological claim is that response dispersion should be treated as an explicit observability problem in synthetic-population research. Synthetic agents should not be evaluated only by fluency or aggregate thematic plausibility. Researchers also need simple, reproducible ways to inspect whether generated responses preserve variation across configured agents. The proposed method provides a practical lexical baseline toward that goal.
The article-specific examples provide initial validation under controlled synthetic conditions. They show that the method responds to manipulated lexical convergence, records data-quality issues, exposes population-size effects, and traces high-overlap alerts to response pairs. The next step is to calibrate the method against human-response baselines and domain-specific expert judgments. Together, the controlled datasets and applied platform export show that the method can be run on both designed test cases and normalized synthetic-platform outputs, provided the required input schema is available.
Ethics and consent
This manuscript does not report data from human participants or animals. The initial validation uses synthetic response records created for software and methodological evaluation. Ethical approval and consent were therefore not required for the current synthetic-output analysis. If future work uses human-response baselines, the relevant ethics approval, consent process, and data-protection safeguards will be reported.