Ranking
We conducted an online survey about how these manipulated poems were perceived by a group of Italian native speakers. Participants were asked to listen to the four conditions and give a ranking of preference, from the one that sounded the most “poetically plausible” to them, to the one they perceived as the strangest.
Consent statement. Written informed consent for participation was obtained in advance from all participants.
Subjects. 62 people participated in the online survey for Ariosto (F=32, M=30, mean age = 29.06, sd= 8.13) and 65 people for Dante (F=35, M=30, mean age = 26.48, sd = 6.26). Part of either cohort were the participants in the main experiment below, but tested with the other author, and they were asked to complete this survey after the end of the second session of the main experiment. Another group of participants was recruited through the online platform Prolific (www.prolific.co). This last group was compensated with five euros. We had aimed for 72 rankers in each cohort, but had to exclude some a posteriori, who failed to complete the ranking in full.
Experimental design. The online survey was designed with the open-source toolkit Psytoolkit (Stoet, 2017). After an example, presented as training also in the main experiment below, they listened to the four poems one at a time. Every poem was associated with a name, in order to help participants refer to that specific condition. If they wanted, they were allowed to listen again and again to the same poem before proceeding to the next.
At the end they were asked to rank the four poems: from the one they perceived as the best, to the one that sounded worse to them. From the rankings by all participating subjects we extracted an average index of metric plausibility by assigning a value 0.6 to the first –ranked condition (e.g., NPA), 0.3, to the second, 0.1 to the third, and 0 to the fourth. The logic behind this assignment is that subjects occasionally reported being unsure as to which passage sounded the strangest. The rankings were collapsed across canti, with the relatively large number of participants ensuring approximately even sampling (each canto was presented originally 18 times per condition, which came down to 16+/-2 after the exclusions). As a result, the average metric plausibility of each condition could in principle range from 0 to 0.6, but in practice was much more restricted, particularly with passages from Dante, to values around the average of 0.25 (see Figure 2).
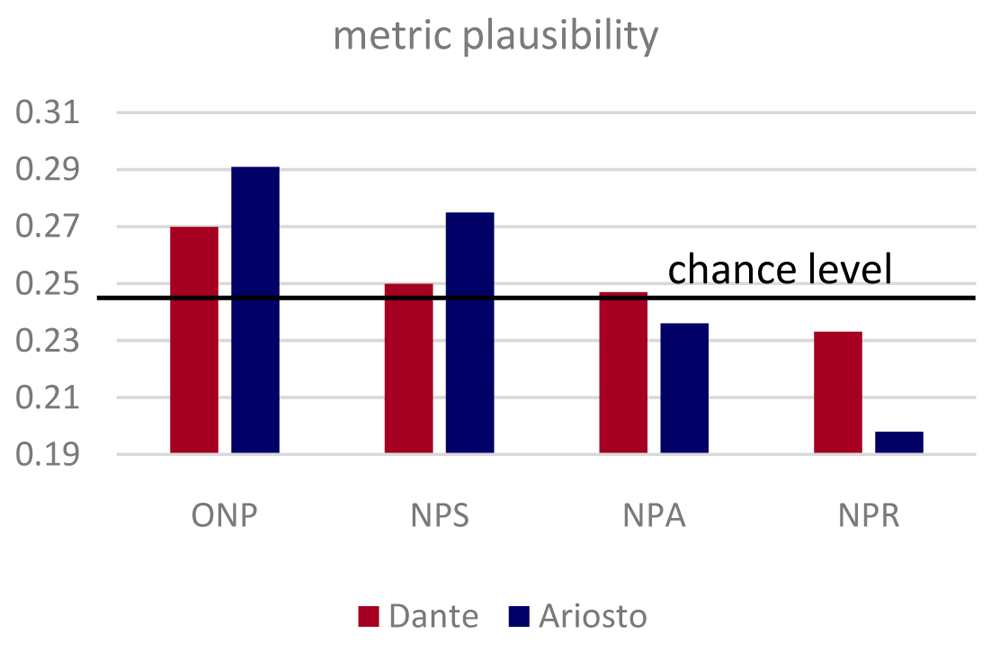
Figure 2. Relative metric plausibility.
The different versions of the same four passages from the Divina Commedia (red) and Orlando Furioso (blue) were ranked in the same order, but the plausibility index (see Methods) is more spread out for Ariosto.
Memory experiment
Ethical approval for this study was granted by the SISSA Ethics Committee at the Scuola Internazionale Superiore di Studi Avanzati with deliberation 2018/16/ib on Nov. 5th, 2018 transmitted by act prot. 15534-III/13.
Subjects. 48 native Italian speakers who had been exposed to Italian literature through one of the national high school curricula were recruited for the main experiment. Half of them were administered material from Ariosto (F= 15, M=9, mean age= 26.34, sd=4.02), the other half from Dante (F=15, M=9, mean age= 26.12, sd=3.61).
Participants were recruited through the SISSA recruiting platform and social media. None of them had a previous history of psychiatric or neurological illness, learning disabilities, nor hearing or visual loss. They were asked to participate in a study on memory and poetry, which would have involved them for two consecutive days, for about 30 minutes the first and about 10 minutes the second. Due to the pandemic situation, they were asked to be connected remotely with their own devices.
Experimental design. The experiment was designed with Psychopy Builder (Peirce et al., 2019). It included a study phase of about 30 minutes the first day, and the test of about 10 minutes the second day.
We aimed at an almost exclusively auditory experiment, in order to assess how memory relies on meter if listening is the only available channel to learn from (Najme et al., 2020). Indeed, the material included audio files only, with the sole exception of written material when a fill in the gap task appeared.
Besides the four passages, verses from two other canti were used for training, as indicated above. However, these verses were presented only in the ONP condition, leaving meter intact.
Every passage, including the training, was associated with an image, taken from among Gustave Doré’s illustrations of the Divina Commedia. The images were consistent for the same canto in different conditions and were intended to help engage memory without, at the same time, biasing the linguistic material (see Extended data).
Every poem, including the training, was presented divided into three consecutive portions.
Notice on the use of the Zoom platform. The pandemic of 2020 forced us to find new methods to administer our experiment to subjects in remote mode.
After evaluating several options, we decided that, for this study, it was important to keep a degree of dialogue with participants. Also, we wanted to make sure that they were focused on the task and that they did the second part at the same time the following day.
For these reasons, among others, we thought that a good option was to have them on streaming in an open source platform. We chose Zoom, for which we had an institutional account.
Unfortunately, this meant that lab conditions could not be fully guaranteed. To overcome potential biases, we gave participants specific instructions:
- be connected with a computer or a tablet. Smartphones were not allowed, because of the small size of their screens and because they could potentially be distracting in case of notifications during the experiment
- be in a silent room with no disturbances
- be in the same room during the experiment for both days
Moreover, we used the accompanying images mentioned in the Experimental design section of the main text, in order to focus the visual attention of the participants away from distracting visual stimuli in the rooms they were in. The images, shown in Extended Data (Andreetta et al., 2021), were taken from among Gustave Doré’s illustrations of the Divina Commedia, but accompanied passages derived from canti in the Commedia unrelated to those the artist referred to, as well as the a priori unrelated passages derived from the Orlando Furioso, and they were further enriched with graded color hues. Each image was consistently paired to each passage, whichever version, ONP, NPS, NPA or NPR, was presented to the subject. The variability across images, enhanced also by leaving each image in its original non-commensurate format, was thus adding an independent component to the natural variability across passages, but not contributing to the metric plausibility effect; and possibly helped reduce the variability, across participants, due to their heterogeneous testing-at-home conditions.
The dialogue over zoom was always conducted by the first author, but the experiment was self-paced by the participants using the Psychopy platform, with the images displayed on the shared screen and the passages played auditorily from the prior recordings by actor Sara Alzetta. The recordings are available upon request. When tested with the muted non-word, participants would read aloud the left, central or right alternative appearing on the screen, and the experimenter would press the corresponding key (leftward, downward or rightward) on her own keyboard.
Study phase. The study phase started with the training ONP. First, participants listened once to all verses. Then they listened to the first part (three verses) repeated five times, with a three second pause between repetitions. Afterwards, another repetition of the same verses followed, but this time a non-word was muted. The task for the participant was then to retrieve the correct non-word. Three written alternatives appeared on the screen and the participant had to read aloud his/her choice.
After this training, each of the experimental passages was played, in a separate block, in the one of the four versions that had been assigned to that subject in the design. Then, after listening once to the entire poem (nine verses in Dante, eight verses in Ariosto), participants listened to the first part (three verses for both authors) five times. Next, they had to complete the task with the muted non-word.
The same happened with the second part of the poem, repeated four times. In this case the audio started from silence with the first part ramping up linearly in intensity, until it continued smoothly into the second part at the standard volume. Therefore, this allowed them to have feedback about the test they just completed.
For the third part they just listened to the repetitions (three verses for Dante, two verses for Ariosto; repeated three times), starting now with an acoustically smoothed version of the second part, but there was no test.
The alternatives to the correct non-word were chosen by maintaining the same number of syllables, and the same accent. Typically, stems and intermediate vowels or consonants changed. Target non-words were generally in the third verse, aiming not to overload working memory from the moment they listened to the silent word until the test time. In the cases where this was not possible (because there were no appropriate non-words in the third verse, for instance) a non-word in the second verse was chosen, if possible towards the end. Notably, for every text we chose options which were consistent among all conditions, allowing a fair comparison in the results.
Test phase. The following day participants were connected at the same time, so 24 hours had passed. They listened directly to the test parts of the text, so the verses with a muted non-word, and they were asked to identify the muted target in all three parts, including then the third one. For the first and second part, tested also the previous day, target non-words were different. After completing the three tests per text, they listened to the entire poem, to receive feedback.
Data analysis. The outcome of interest is essentially the presence of a significant correlation between the dependent variables measured in the ranking (the plausibility index, see Figure 2) and in the memory experiment (correct responses, and reaction times, see Figure 4), that would indicate a joint dependence on the type of passage manipulation. Correlations were considered significant at p < 0.05. Additional methodological considerations and controls are detailed below.
Entropy in the accent distribution. Two simple entropy measures were used to quantify the variability in the pattern of accents in the eight passages from the Divina Commedia and Orlando Furioso from which we derived the non-poems used in the experiment. First, the pattern of accents in each verse (from a total of 36 verses from the Commedia and 32 from the Orlando) was codified, based on the consensus in the literature, as a binary string of length 11, where each syllable was assigned a 1 if accented and a 0 if not. Since all 68 verses were regular hendecasyllables with the 10th syllable accented and the 11th not, we focused on the first nine digits in each string.
The first measure is based on the simplifying assumption of independent accents on neighboring syllables and calculates, for each author, the sum of the binary entropies for the syllables in each ordinal position, a sum which can range from 0 to nine bits.
The second measure is the entropy of the distribution, for each author, of distinct binary strings, and it ranges from 0 to log2(36) for Dante and from 0 to 5 bits for Ariosto.
Word frequency. The targets were derived from words of widely different frequency, covering the entire spectrum from 5×10⁻⁸ to 1.5×10⁻³ in SUBTLEX-IT, the corpus of Italian Subtitle-based Word Frequency Estimates, containing 517.564 entries (poster presented at the Annual Meeting of the Italian Ass Expl Psychol, Rovereto, Sept. 2015: Crepaldi, Amenta, Mandera, Keuleers and Brysbaert, SUBTLEX-IT. Subtitle-based word frequency estimates for Italian. Available online: https://lrlac.sissa.it/publications/frequency-estimates-different-registers-explain-different-aspects-visual-word).