1 Introduction
This paper represents a first effort to apply phylogenetic classification to the Je language family, addressing a significant gap in Macro-Je studies, as quantitative approaches have been notably absent in previous research. Phylogenetic methods, which are well-established in linguistics, have been widely used to elucidate the classification and dating of various language families, such as Indo-European (Chang et al., 2015), Dravidian (Kolipakam et al., 2018), Alor Pantar (Kaiping & Klamer, 2019), Mixtecan (Auderset et al., 2023) and Tupi-Guarani (Ferraz Gerardi et al., 2023). These methods are particularly suited for testing hypotheses related to prehistory, linguistic evolution, and evolutionary dynamics (Greenhill et al., 2020).
Von den Steinen (1886) introduced the term “Je” to designate this language family based on lexical and cultural comparison (see also Ehrenreich, 1891). He derived the name “Je” from a common collective suffix found in many of the group’s names.
The Je language family today comprises about fifteen languages (Hammarström et al., 2024), some with multiple dialects (see, e.g., Gildea & de Castro Alves, 2020: 50), all spoken in Brazil and geographically distributed broadly. Many Je languages have become extinct, and, for most, only limited data is available (Gildea & de Castro Alves, 2010; Nikulin, 2020; Nimuendajú, 2017). Davis (1966), based on phonemic correspondences, proposed internal relations among Apinajé, Timbira, Xavante, Kaingang, and Suyá. This was an important step, as it demonstrated the existence of geographical clusters within the Je family: Northern (Timbira, Apinajé, and Suyá), Central (Xavante), and Southern (Kaingang).
The proposal for the Macro-Je phylum (Mason, 1950; Schmidt, 1926), consisting of the Je family and several smaller families, was supported by studies such as Rivet (1924) (see also Loukotka, 1932; Loukotka, 1937; Loukotka, 1939; Loukotka 1942[1944]), which provided further evidence for this phylum, and included languages such as Ofayé (see also Gudschinsky, 1971), Koropó, Pataxó, Krenak (Borum), Arikapu, Djeoromitxí and Kamakã (see also Mason, 1950; Ribeiro & van der Voort, 2010; Rodrigues, 2009). Boswood (1973) presented lexical evidence supporting the inclusion of Rikbaktsá in this family. Rodrigues (1986) expanded the internal relations within Macro-Je and (Rodrigues, 1999) added data from extinct languages.
The inclusion of Bororo in the Macro-Je phylum, suggested by Guérios (1939), is no longer accepted (Nikulin, 2020). Rodrigues (1986) included Karirí and Guató as small families in the Macro-Je phylum, but considered Pataxó a member of the Maxakalí family. Greenberg (1987) classified Guató, Maxakalí, and Pataxó as part of Macro-Je, adding Chiquitano, Otí, and Jabutí families. Conversely, Kaufman (1990) excluded Otí, Jabutí, and Karirí from Macro-Je but retained Chiquitano (see Nikulin, 2020). For other proposals, see de Castro Alves (2010) and Ribeiro & van der Voort (2010). Nikulin (2020) grouped Maxakalían and Krenakan (perhaps also Kamakanan) in a branch he calls “Transfranciscanan”. He also provided thorough evidence for a larger Macro-Je phylum, further suggesting a more distant relationship with other families such as Chiquitano, which he considers to have a common ancestor with Proto-Macro-Je.
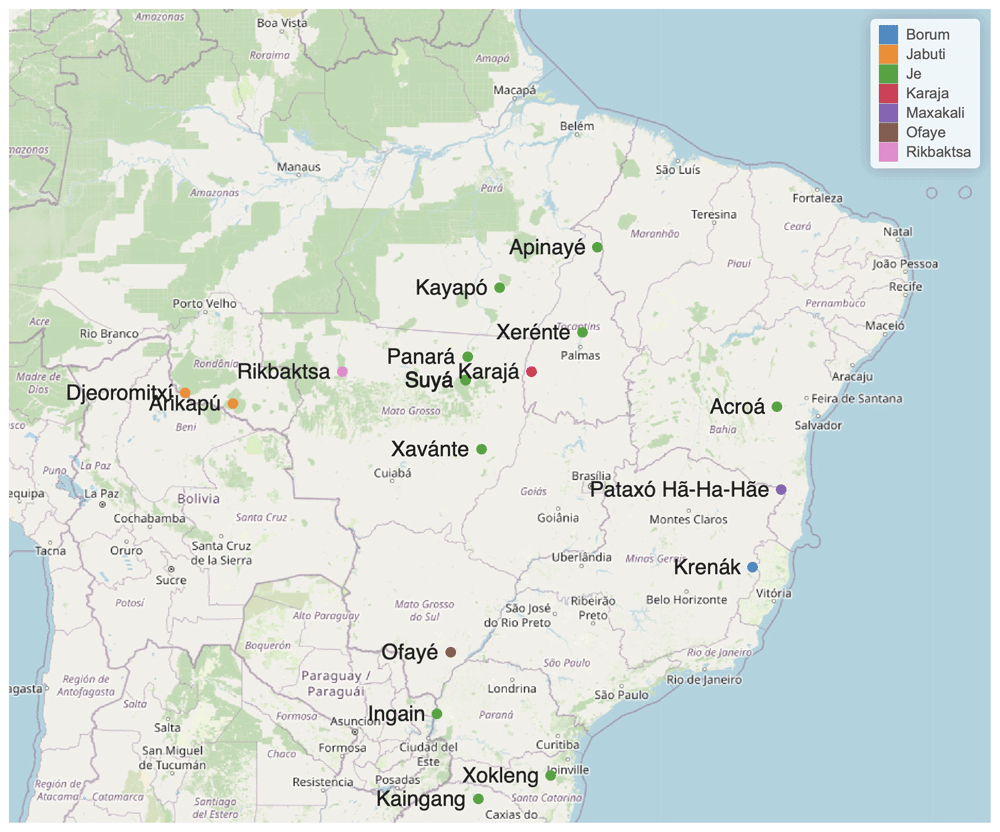
Table 1 lists 27 languages considered potential members of the Macro-Je phylum, for which there is some documentation, although limited in some cases. These languages are shown in Figure 1.
Table 1. Likely members of Macro-Je.
| Doculect | ISO 639 | Glottocode | Family |
|---|
| Acroá | acs | acro1239 | Central Je |
| Apinaye | apn | apin1244 | Northern Je |
| Arikapu | ark | arik1265 | Jabutí |
| Borum | kqq | kren1239 | Borum |
| Canela-Kraho | ram | cane1242 | Northern Je |
| Chiquitano | cax | chiq1253 | Chiquitano |
| Djeoromitxí | jbt | djeo1235 | Jabutí |
| Gaviao-Pyhcopji | xri | krik1239 | Northern Je |
| Ingain | | inga1254 | Southern Je |
| Kaingang | kgp | kain1272 | Southern Je |
| Karajá | kpj | kara1500 | Karajá |
| Mebengokre (Kayapó) | | kaya1330 | Northern Je |
| Koropó | xxr | coro1248 | Maxakalí |
| Kisedje | suy | suya1243 | Northern Je |
| Krenák | | kren1240 | Borum |
| Pataxó | pth | pata1261 | Maxakalí |
| Ofayé | opy | ofay1240 | Ofayé |
| Parkateje | | timb1254 | Northern Je |
| Panara | kre | pana1307 | Northern Je |
| Rikbakstá | rkb | rikb1245 | Rikbakstá |
| Suyá | suy | suya1243 | Northern Je |
| Tapayuna | | beic1238 | Northern Je |
| Timbira | | timb1253 | Northern Je |
| Xacriabá | xkrx | xacr1238 | Central Je |
| Xavante | xav | xava1240 | Central Je |
| Xerente | xer | xer1240 | Central Je |
| Xokleng | xok | xokl1240 | Southern Je |
Ribeiro (2012: 266) noted the difficulty in conducting a comparative study of Macro-Je due to the monosyllabic nature of many parallels presented, and the lack of systematic sound correspondences in their roots (see also Ribeiro & van der Voort, 2010). Many of the lexical parallels found among the linguistic families attributed to this stock and referred to as ’cognates’ may be borrowings, given the high probability of interactions that many populations have had since precolonial times with various other populations (see the dates provided in Section 5). The hypothesis that Macro-Je could result from long-term linguistic contact via ethnogenesis (Dixon & Aikhenvald, 1999) cannot yet be discarded. In this case, similarities found between Je family and some other families / languages, such as Borum and Maxakali, but also Purí and Guató, would be instances of horizontal transfer rather than genetic inheritance (Ramirez et al., 2015).
Evidence from historical-comparative linguistics supports the genetic identity of a ‘nuclear’ Macro-Je linguistic stock, which includes the Je family along with the Chiquitano (Adelaar, 2008), Jabutí (Ribeiro & van der Voort, 2010), Ofayé and Karajá (Ribeiro, 2011; Ribeiro, 2012) families. Conversely, the evidence for including languages such as Bororo, Yatê, Purí, Guató, Karirí, and Otí in the Macro-Je stock is extremely weak.
Speakers of Macro-Je languages inhabit a vast region that extends longitudinally from the Atlantic coast to the Chiquitano Dry Forest and the Guaporé River, and latitudinally from the lower Tocantins to the northern part of the current state of Rio Grande do Sul (see Figure 1). Currently, they number approximately 90,000 individuals, with the most spoken languages being Kaingáng (around 30,000 speakers), Xavante (around 25,000), and Mebengokre (around 13,500).
Typologically, Je languages are characterized phonologically by a rich vowel inventory that includes nasal vowels, which often trigger nasal enhancement phenomena in adjacent segments (de Carvalho & Damulakis, 2015; Pickering, 2010). The languages have a limited number of possible onsets, typically allowing only sequences of a peripheral obstruent (labial or velar) followed by a rhotic (Nikulin, 2020). Je languages tend to be head-final SOV as the most common order. Many Je languages display a rare type of split alignment that has not yet been sufficiently studied. This alignment pattern has been called nominative-absolutive (Gildea & de Castro Alves, 2010; Gildea & de Castro Alves, 2020). Another typical Je feature is the singular-(dual)-plural stem alternation for certain semantic verb types (see Inman & Vuillermet, n.d.), and a somewhat complex system of person marking that interacts with agreement, since most languages are of the dependent marking type. For a more detailed typological profile of the Macro-Je languages, we refer the reader to the works of Salanova (n.d.), Storto (2019: 138–140) (only phonology), Rodrigues (1999) (partially outdated) and Wiesemann (1986).
This paper is structured as follows: Section 2 presents the data used, followed by a presentation of the methods employed in Section 3. The results are discussed in Section 4. The Section on archaeology (5) places Je languages in light of archaeological dates and relates this to the results of our analyses. The paper concludes with final remarks in Section 7.
2 Data
The data used in this study is drawn from Gerardi and Tresoldi 2024, which builds on Nikulin (2020). It consists of 14 languages (given in Table 2) and 516 concepts. The concepts include most Swadesh list items (Swadesh, 1971) along with many culturally relevant concepts related to fields like agriculture, vegetation and fauna. Given the exploratory nature of this study, cognacy judgments were automatically generated using LexStat (List, 2014), a state-of-the-art method implemented in the Lingpy Python package (List & Forkel, 2021). While Rama & List (2019) demonstrated that automated cognacy judgments can be effectively used for preliminary analyses and often produce reliable results, a small subset—approximately 10% of the data—was manually annotated to assess the quality of the automatic annotation. This assessment was conducted by calculating the B-Cubed F-Score (see List (2014) for details) between the automatically and manually assigned cognate classes, resulting in a score of 0.947. This result indicates a high level of accuracy in the automated judgments.
| Doculect | ISO
639 | Glottocode | Latitude | Longitude |
|---|
| Apinaye | apn | apin1244 | -6.11 | -47.63 |
| Arikapu | ark | arik1265 | -12.49 | -62.73 |
| Canela-Kraho | ram | cane1242 | -6.11 | -45.13 |
| Gaviao-Pyhcopji | xri | krik1239 | -5.94 | -46.75 |
| Ingain | - | inga1254 | -24.62 | -54.25 |
| Kaingang | kgp | kain1272 | -27.77 | -52.54 |
| Kisedje | suy | suya1243 | -11.52 | -53.07 |
| Mebengokre | txu | kaya1330 | -7.77 | -51.67 |
| Panara | kre | pana1307 | -10.58 | -53 |
| Parkateje | - | timb1254 | - | - |
| Tapayuna | - | beic1238 | - | - |
| Xavante | xav | xava1240 | -14.30 | -52.44 |
| Xerente | xer | xer1240 | -9.59 | -48.26 |
| Xokleng | xok | xokl1240 | -26.92 | -49.59 |
For the analysis described below, we restricted the dataset to concepts that had corresponding forms in at least 50% of the languages, reducing the set to 303 concepts. Table 3 reveals that approximately 38% of the forms across all languages and remaining concepts are missing. Notably, 210 out of the 622 cognate sets in the dataset are singletons—that is, word forms classified as non-cognate with any other word form. However, 72 of those singletons are found in Arikapu, a Jabutí language and the only non-Je language in the sample (Ribeiro & van der Voort, 2010). Conversely, five concepts with forms available across all sampled languages are classified as consisting of a single cognate set: ”FOOT”, ”HEAD”, ”LIVER”, ”MEAT” and ”SLEEP”. The full list of concepts, as well as the results of the automatic cognate detection, the subset used to calculate the F-Score and the results of the analyses discussed below are available online (Ferraz Gerardi et al., 2025).
Table 3. Coverage and cognate statistics.
| Concepts | 303 |
| Languages | 14 |
| Words | 2638 |
| Coverage | 0.622 |
| Cognate sets | 622 |
| Singletons | 210 |
3 Method
In recent years, the field of computational historical linguistics has experienced substantial growth, with phylogenetic methods adapted from bioinformatics gaining prominence for language classification and dating (see Greenhill (2023) for a comprehensive list of studies). This study seeks to classify the languages in our sample (see Table 2) using Bayesian phylogenetic inference. For the analyses, the data was exported to the NEXUS format (Maddison et al., 1997). In this format, the data is represented as a matrix where each column corresponds to a cognate class, and each row represents a language. The resulting binary representation uses ’1’ to indicate the presence of a cognate class in a language, ’0’ for its absence, and a special character for missing data in a concept-language pair. Following Hoffmann et al. (2021), ascertainment correction was applied.
3.1 NeighborNet
To quantify and visualize conflicting signals within the dataset, we employed δscores and Q-residuals—indices that measure the tree-likeness of the data (Bryant & Moulton, 2004; Gray et al., 2010). δ-scores range from 0 to 1, with higher values indicating increased conflict, while Q-residuals, adjusted for scaling effects, provide a more direct measure of divergence from a strict tree structure (Gray et al., 2010). Lower Q-residual scores suggest a closer fit to a strict tree. Averaging both scores over the tips yields a measure of overall tree-likeness. These metrics, along with the NeighborNet visualization, were generated using SplitsTree4 (Huson & Bryant, 2006). Although direct comparison of δ-scores and Q-residuals across different datasets and the evaluation of their significance may not be feasible, low values for these metrics validate the application of methods such as Bayesian phylogenetics, which assume a strict tree structure (Gray et al., 2010). The plot of δ-scores against Q-residuals for each language is given in Figure 2 and the NeighbourNet is given in Figure 3.
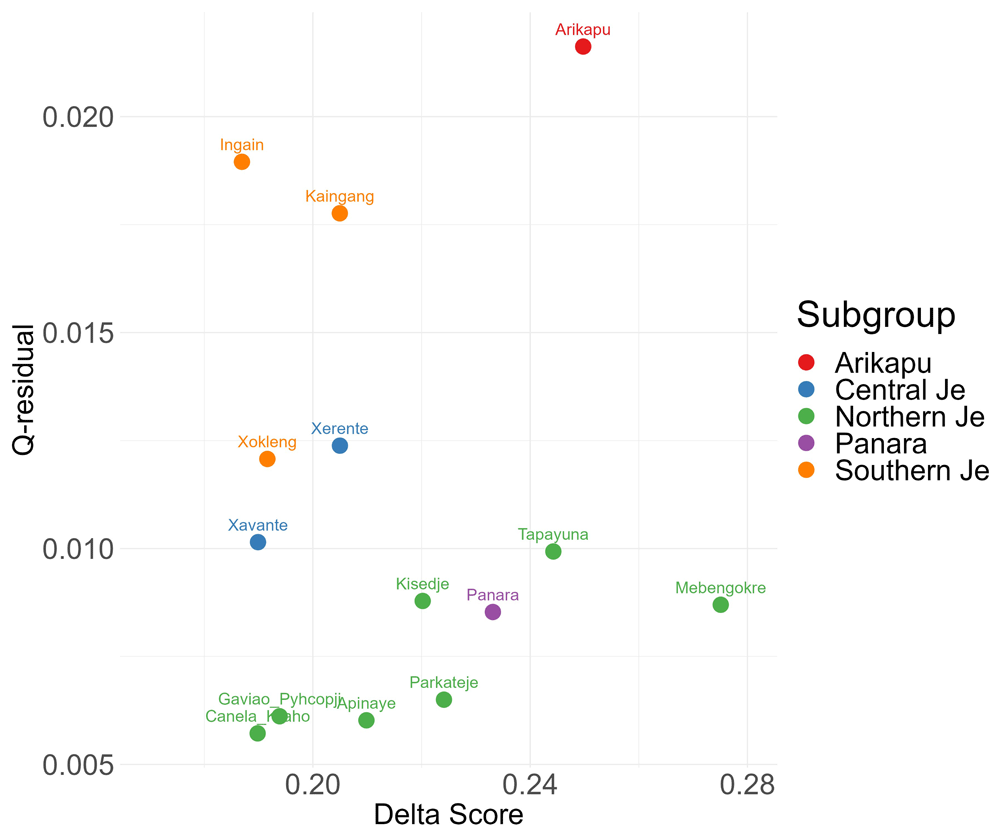
Figure 2. δ-scores and Q-residuals.
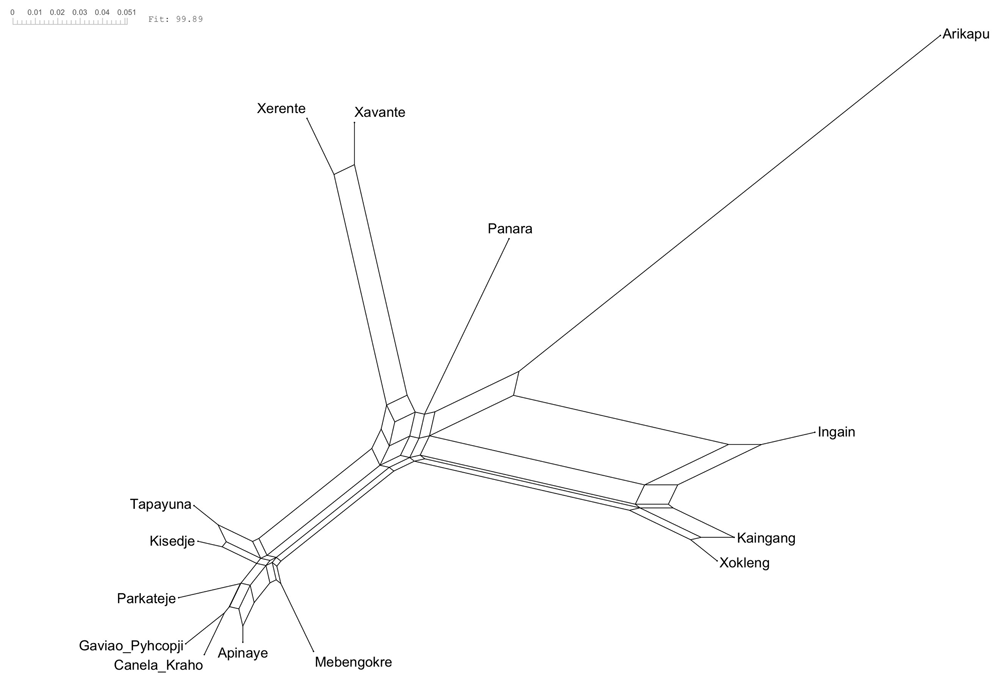
Figure 3. NeighborNet.
The reticulations, the ”boxes” between the branches, indicate the conflicting signal in the data.
3.2 Bayesian analyses
Phylogenetic reconstruction was performed using BEAST2 (Bouckaert et al., 2014), testing various binary covarion models (Huelsenbeck, 2002). Under the binary covarion model, each lexical item, represented as a binary character, can transition between different evolutionary states, such as being subject to change or remaining invariant over time. This flexibility reflects the reality that certain words may evolve at different rates or may be more prone to changes in some languages compared to others, providing a more nuanced and accurate representation of lexical evolution in a phylolinguistic analysis. We tested models that differed in whether each concept was assigned an independent substitution rate ('per-concept rates'), allowing for variation in mutation rates across concepts, or a single shared substitution rate ('shared rates') across all concepts, as well as in whether a strict or relaxed clock was employed. A strict clock assumes a constant rate of evolution across all branches of the tree, while a relaxed clock allows for rate variation, accommodating differing evolutionary dynamics across branches and over time. For all four resulting models, we used a Birth-Death Skyline prior (Stadler et al., 2013). As recommended by one of the reviewers, we included calibration points to include temporal estimates. A uniform root prior ranging from 500 to 6000 BP was applied, as it facilitated convergence based on prior experience. The Xerente-Xavante split was calibrated with a lognormal distribution (mean in real space: 200, standard deviation: 0.05), following Maybury-Lewis (1974). The Northern-Southern split was assigned a normal prior (mean: 1900, standard deviation: 100), and the Northern-Central split a normal prior (mean: 1200, standard deviation: 100), both informed by archaeological evidence (see Section 5).
To identify the best-fitting model, we used Nested Sampling (Skilling, 2006), which is available as a package for the BEAST2 software (Russel et al., 2018), to calculate the log marginal likelihood for each model. Model selection was performed using the Bayes Factor, which compares the models’ likelihoods and identifies the model that best explains the data (Hoffmann et al., 2021).
We conducted tree inference on the model selected as the best fit based on the Bayes Factor analysis. We performed 107 MCMC iterations, sampling a tree every 103 iterations, resulting in a posterior sample of 104 trees. From these, we obtained a maximum clade credibility tree (MCC) based on common ancestor heights using TreeAnnotator version 2.7.4 (Heled & Bouckaert, 2013) with a 50% burn-in.
To quantify the quality of the inferred tree topology, we calculated the Generalized Quartet Distance (Pompei et al., 2011) to the Glottolog tree (Hammarström et al., 2024) using the Quartet package in R (R Core Team, 2023; Sand et al., 2014; Smith, 2019). The Glottolog tree was pruned to include only the languages in our sample. Because Mebengokre, Kaingang, Kisedje and Canela-Kraho are represented as internal nodes rather than tips in the Glottolog tree, we used proxy languages within these nodes to complete the tree for comparison. The Glottocodes of the proxies were kaya1331 (Txucarramae), cent2143 (Central Kaingang), yaru1258 (Yaruma) and krah1246 (Krahô), respectively. Lower GQD values indicate greater topological similarity between the inferred tree and the Glottolog tree.
4 Results
The NeighborNet (Figure 3) and δ-scores and Q-residuals grouped by subgroup (Figure 2) indicate that most conflicting signals were found for Arikapu and parts of the Southern Je subgroup, whereas Northern Je (including Panará) and Central Je languages exhibit the least amount of conflicting signal.
Unsurprisingly Arikapu—a Jabutí language and the only non-Je language in the sample—deviates most from a tree-like structure. However, the elevated Q-residuals observed for the Southern Je languages cannot be conclusively attributed to a potential dialect continuum and may instead result from the limited amount of data available for this branch. Table 4 summarizes the results of model selection, ranking models by their log-marginal likelihoods. The differences between the highest log-marginal likelihood and those of other models are reported as log Bayes Factors. According to Kass & Raftery (1995), a log Bayes Factor of more than 20 indicates strong support for a model. The results show a clear preference for relaxed clock models over strict clock models. Additionally, models without per-concept substitution rates and therefore having fewer parameters, are favored. Following model selection, we performed tree inference using the best-fitting model, identified as the relaxed clock model using shared rates.
Table 4. Nested Sampling results (SD = standard deviation of the log-marginal likelihood estimate, BF = Bayes Factor).
| Model | Log-Marginal
Likelihood | SD | (log) BF |
|---|
shared rates, relaxed
clock | -1967.84 | 2.76 | - |
| shared rates, strict clock | -1991.87 | 2.81 | 24.03 |
per-concept rates, relaxed
clock | -2019.11 | 4.26 | 51.27 |
per-concept rates, strict
clock | -2032.06 | 4.41 | 64.22 |
The relative order of splits in the inferred tree (Figure 4) aligns well with the pre-Columbian history of Je-speaking groups, as reconstructed through archaeological findings. The MCC tree (Figure 4) of the inferred phylogenetic tree was visualized using the FigTree software (Rambaut, 2010). The numbers on the nodes correspond to their posterior probabilities and the blue bars show the 95% highest posterior density estimate of the split timings. Notably, the inferred tree closely aligns with the established classifications, as quantified by a GQD (Generalized Quartet Distance) to the gold-standard tree of 0.124. In comparison to the findings of Häuser et al. (2024), where the GQD was calculated for trees inferred from datasets with expert cognacy judgments, this value is in the low range.
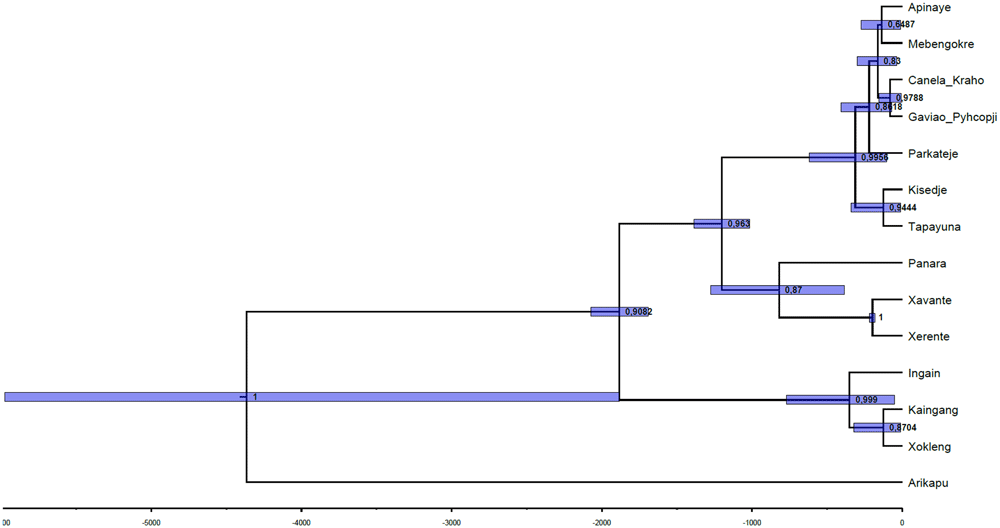
Figure 4. Topology of the tree with shared substitution rates and relaxed clock model.
The first split separates Arikapu (Jabuti) from the Je languages, as expected, followed by a split that separates the Southern group. Subsequently, the Northern and Central languages diverge, consistent with archaeological data (see below).
5 Archaeology
The earliest material culture complex commonly associated with Macro-Je speakers is the Una tradition, distinguished by small, simple ceramic vessels found in open-air settlements and rock shelters in central Brazil (Dias-Jr., 1975; Robrahn-González, 1996). Given its dates and persistence until relatively recently, the Una tradition does not necessarily mark the initial split of the Macro-Je languages, but might have been adopted by various Macro-Je and Je-speaking populations. It does, however, seem to be related to the transition to more sedentary settlements, as well as with the transition to plant cultivation. The earliest dates come from Minas Gerais state, where Una ceramics are associated with early maize and other domesticated plant remains in rock shelters (3490 ± 120 BP, 2 σ cal BP 4078-3406 [SI-2788]) (Bird et al., 1991). After ca. 2700 BP, this tradition is found throughout the cerrado (central Brazilian savanna) from Goiás to Mato Grosso (2390 ± 60 BP, 2 σ cal BP 2699-2147 [Beta-78256], and 2360 ± 70 BP, 2 σ cal BP 2698-2133 [SI-4068]) (Barbosa et al., 1982; Wüst, 1998).
The Southern Je branch is clearly associated with the Taquara/Itararé Tradition, based on its spatial distribution, material culture (small, simple ceramic vessels, sometimes with dark burnishing and plastic decoration), burial practices (funerary mounds, sometimes involving cremation), and chronology, all showing a persistence until early colonial times (Corteletti & Iriarte, 2018; de Mello Araujo, 2007; Noelli & De Souza, 2017). The earliest secure dates for this Tradition reveal a similar horizon of initial settlement for the three southern states, Paraná, Santa Catarina and Rio Grande do Sul - respectively, 1941 ± 35 BP (2 σ cal BP 1980-1741 [LACUFF-150057]), 1840 ± 40 (2 σ cal BP 1827-1610 [CAMS-53915]) and 1810 ± 85 (2 σ cal BP 1890-1431 [SI-813]) (De Masi, 2001; Parellada, 2016; Schmitz & Brochado, 1972). The dates associated with this archaeological dispersal to the south, later than those of the Una tradition, are coherent with the next split of the tree, which separates the Southern and the Central-Northern Je branches (Figure 4).
Around the first millennium AD, a new archaeological complex spreads throughout central Brazil and part of the Atlantic coast. Characterized by circular villages with central plazas, urn burials, and large ceramic vessels, this complex is known as the Aratu Tradition (Robrahn-González, 1996; Wüst & Barreto, 1999). The geographical distribution, similarities with ethnographic ring villages, and chronology confirm that this tradition is related to the Northern and Central Je groups. The origins appear to be in Goiás, with a date of 1220 ± 50 BP (2 σ cal BP 1259-960 [Beta-99031]), spreading to the coast of Bahia and Espírito Santo by 1080 ± 90 BP (2 σ cal BP 1175-741 [SI-542]) and 1076 ± 36 (2 σ cal BP 1050-807 [SI-2347]), respectively (Calderón, 1969; Perota, 1979; Silva et al., 1997). It is important to notice that the presence of this culture in the coast implies that it was not a purely Je phenomenon, but might have been adopted by speakers of other Macro-Je branches or even by unrelated groups. However, our tree suggests that it was probably a retention shared by both Northern and Central Je speakers (Figure 4).
6 Discussion
The results presented here provide additional support for the existence of geographical clusters within the Je language family, as previously suggested by Rodrigues (Rodrigues, 1986; Rodrigues, 1999) and Nikulin (Nikulin & Salanova, 2019: 178). The results also highlight with high certainty that Arikapu is not a Je language.
The inclusion of Panará in a clade with the Central Je languages, specifically Xavante and Xerente, is not entirely unexpected given its geographic location – Panará is usually classified as a separate branch. Historically, this area was in close proximity to the regions where Akwe languages were spoken before their separation around 1815 (Maybury-Lewis, 1974). In fact, de Carvalho (2016) identified a loanword from an Akwe language in Panará, this being the only known instance of “contact” between these groups. These languages were historically spoken in the southern part of the Brazilian state of Tocantins and in northern Goiás, particularly along the middle course of the Tocantins River.
Nikulin (2020) does not include Panará in the Septentrional branch, instead proposing a separate branch comprising languages spoken in the Goyaz region (see also Nikulin & Salanova, 2019), which form a larger clade together with Panará. Within this branch, Panará is the southernmost language, and Nikulin (2020) acknowledges that part of its lexicon is of unknown origin (see also de Carvalho, 2016). These facts do not contradict the results in the tree presented in Figure 4; on the contrary, together they offer evidence regarding the internal classification.
It is worth noting that while the time estimates in the tree align closely with the priors set in the model, they are expected to be reasonably reliable. Excluding individual calibration points resulted in estimates for the omitted timings that remained consistent with those from the full analysis. This consistency indicates that the inferred dates are not solely driven by specific priors but reflect genuine signal in the data.
7 Conclusion
The phylogeny presented here does not introduce new findings as far as classification is concerned, but reinforces previous classifications of Je family, highlighting established geographical clusters of languages as sub-families and raising questions for further inquiry. The novelty of this research concerns the dating of the phylogeny, which agrees with archaeological data discussed in Section 5.
In future research, it will be essential to expand the database to attempt a more comprehensive classification that includes a greater number of (non-Je) languages, broader coverage, and manual cognate annotation. Additionally, incorporating not only lexical data but also morphological and syntactic data could be highly valuable, as these elements evolve at different rates and might offer crucial insights into the evolution of a language family (Hübler & Greenhill, 2022).
The geographical clusters (northern, central, and southern groups) provide a realistic model for understanding the spread of Je languages, but they must account for archaeological data, including those for non-Je groups, which are more scarce. While the Macro-Je hypothesis remains valid, further comparative research is required in order to establish a better groundwork for understanding the branching of the phylum. More information about non-Je languages is now available and will be included in future analyses.
Data availability
Zenodo: A phylogenetic classification of the Je language family: Supplementary data. https://doi.org/10.5281/zenodo.15041553 (Ferraz Gerardi et al., 2025). The supplementary data is also available on https://github.com/TGH-2020/Je_Phylogeny.
This project contains the following underlying data:
data
- concepts.csv: a list of all concepts that have been used in the study, along with the coverage and the number of cognate sets per concept
- auto_cogids.tsv: a list of all word forms and corresponding cogids assigned by automated cognacy judgements and used in the study
- subset_for_metrics_calculation.csv: a subset of the data with columns for automatically and manually annotated cognates (used to assess the quality of automatic annotations)
trees: files to run all model variations with BEAST, as well as the output from the BEAST runs
Data are available under the terms of the Creative Commons Attribution 4.0 International license (CC-BY 4.0).
Faculty Opinions recommendedReferences
- Adelaar WFH:
Relações externas do macro-jê. O caso do chiquitano. In: S V T de A P L Telles & A S de Paula (eds.), Topicalizando macro-jê. Nectar Recife, Braz, 2008; 9–28.
- Auderset S, Greenhill SJ, DiCanio CT, et al.:
Subgrouping in a ‘dialect continuum’: a Bayesian phylogenetic analysis of the Mixtecan language family.
J Lang Evol.
2023; 8(1): 33–63. Publisher Full Text
- Barbosa AS, Schmitz PI, Stobhaeus A, et al.:
Projeto médiotocantins: monte do carmo, go. Fase cerâmica pindorama.
Pesquisas: Antropologia.
1982; 34: 49–92.
- Bird RM, Dias O, de Carvalho ET:
Subsídios para a arqueobotânica no Brasil: o milho antigo em cavernas de Minas Gerais, Brasil.
Revista de Arqueologia.
1991; 6(1): 15–31. Publisher Full Text
- Boswood J:
Evidências para a inclusão do aripaktsá no filo macro-jê.
Série Lingüística.
1973; 1: 67–78. Reference Source
- Bouckaert R, Heled J, Kühnert D, et al.:
Beast 2: a software platform for Bayesian evolutionary analysis.
PLoS Comput Biol.
2014; 10(4): e1003537. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Bryant D, Moulton V:
Neighbor-net: an agglomerative method for the construction of phylogenetic networks.
Mol Biol Evol.
2004; 21(2): 255–265. PubMed Abstract
| Publisher Full Text
- Calderón V:
A fase Aratu no recôncavo e litoral norte do estado da Bahia. In: PRONAPA (ed.), Museu Paraense Emílio Goeldi. 1969; 161–168.
- Chang W, Cathcart C, Hall D, et al.:
Ancestry-constrained phylogenetic analysis supports the Indo-European steppe hypothesis.
Language.
2015; 91(1): 194–244. Reference Source
- Corteletti R, Iriarte J:
Recent advances in the archaeology of the Southern Proto-Jê people. 2018; 1–11. Publisher Full Text
- Davis I:
Comparative Jê phonology.
Estudos Lingüísticos: Revista Brasileira de Lingüística Teórica e Aplicada.
1966; 1(2): 10–24. Reference Source
- de Carvalho FO:
On the development of the Proto-Northern Jê Rhotic in Panará historical phonology.
Anthropological Linguistics.
2016; 58(1): 52–78. Reference Source
- de Carvalho FO, Damulakis GN:
The structure of Akroá and Xakriabá and their relation to Xavante and Xerente: a contribution to the historical linguistics of the Jê languages.
LIAMES: Línguas Indígenas Americanas.
2015; 15(1): 17–46. Reference Source
- de Castro Alves F:
Evolution of alignment in Timbira.
International Journal of American Linguistics.
2010; 76(4): 439–475. Publisher Full Text
- De Masi MAN:
Pescadores coletores da costa sul do Brasil.
Pesquisas: Antropologia.
2001; 57: 1–136. Reference Source
- de Mello Araujo AG:
A tradição cerâmica Itararé-Taquara: características, área de ocorrência e algumas hipóteses sobre a expansão dos grupos Jê no sudeste do Brasil.
Revista de Arqueologia.
2007; 20(1): 9–38. Reference Source
- Dias O Jr:
Pesquisas arqueológicas nas grutas do Brasil.
Anais do 10º Congresso Nacional de Espeleologia.
1975; 61–71. Reference Source
- Dixon RMW, Aikhenvald A:
The Amazonian languages. Cambridge University Press, 1999. Reference Source
- Ehrenreich P:
Die einteilung und verbreitung der Völkerstämme Brasiliens nach den gegenwärtigen stande unserer kenntnisse.
Petermanns Mitt.
1891; 37: 81–89, 114–124. Reference Source
- Ferraz Gerardi F, Tresoldi T, Aragon CC, et al.:
Lexical phylogenetics of the Tupí-Guaraní family: language, archaeology, and the problem of chronology.
PLoS One.
2023; 18(6): e0272226. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Ferraz Gerardi F, Wientzek T, Gregorio de Souza J, et al.:
A phylogenetic classification of the Je language family: supplementary data. (version v1).
Zenodo.
2025. http://www.doi.org/10.5281/zenodo.15041553
- Gerardi FF, Tresoldi T:
CLDF dataset derived from MaJeLeD (Macro-Je Lexical Database) (v0.1-pre).
Zenodo.
[Data set]. 2024. http://www.doi.org/10.5281/zenodo.12304366
- Gildea S, de Castro Alves F:
Nominative-absolutive: counteruniversal split ergativity in Jê and Cariban. In: Spike Gildea & Francesc Queixalós (eds.), Ergativity in Amazonia. John Benjamins Amsterdam, 2010; 159–199. Publisher Full Text
- Gildea S, de Castro Alves F:
Reconstructing the source of nominative-absolutive alignment in two Amazonian language families. In: Jóhanna Barðdal, Spike Gildea & Eugenio R. Luján (eds.), Reconstructing syntax. Brill, 2020; 47–107. Publisher Full Text
- Gray RD, Bryant D, Greenhill SJ:
On the shape and fabric of human history.
Philos Trans R Soc Lond B Biol Sci.
2010; 365(1559): 3923–33. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Greenberg JH:
Language in the Americas. Stanford University Press, 1987. Reference Source
- Greenhill SJ:
Language phylogenies: modelling the evolution of language. In: The Oxford Handbook of Cultural Evolution. Oxford University Press, 2023. Publisher Full Text
- Greenhill SJ, Heggarty P, Gray RD:
Bayesian phylolinguistics. In: Richard D. Janda, Brian D. Joseph & Barbara S. Vance (eds.), The handbook of historical linguistics. Wiley Online Library, 2020; 2. : 226–253. Publisher Full Text
- Gudschinsky SC:
Ofaié-xavánte, a Jê language. In: Sarah C. Gudschinsky (ed.), Estudos sôbre línguas e culturas indígenas. Brasília: Summer Institute of Linguistics, 1971; 1–16. Reference Source
- Guérios RFM:
O nexo linguístico bororo-merrime-caiapó.
Revista do Círculo de Estudos Bandeirantes.
1939; 2(1): 61–74. Reference Source
- Hammarström H, Forkel R, Haspelmath M, et al.:
Glottolog database 5.0. 2024. Publisher Full Text
- Häuser S, Jäger G, Rama T, et al.:
Are sounds sound for phylogenetic reconstruction? 2024. Reference Source
- Heled J, Bouckaert RR:
Looking for trees in the forest: summary tree from posterior samples.
BMC Evol Biol.
2013; 13: 221. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Hoffmann K, Bouckaert R, Greenhill SJ, et al.:
Bayesian phylogenetic analysis of linguistic data using BEAST.
J Lang Evol.
2021; 6(2): 119–135. Publisher Full Text
- Hübler N, Greenhill SJ:
Modelling admixture across language levels to evaluate deep history claims.
J Lang Evol.
2022; 7(2): 166–183. Publisher Full Text
- Huelsenbeck JP:
Testing a covariotide model of DNA substitution.
Mol Biol Evol.
2002; 19(5): 698–707. PubMed Abstract
| Publisher Full Text
- Huson DH, Bryant D:
Application of phylogenetic networks in evolutionary studies.
Mol Biol Evol.
2006; 23(2): 254–267. PubMed Abstract
| Publisher Full Text
- Inman D, Vuillermet M:
Singular-plural verb stem alternation: uncovering global and local drivers of typological variation.
Linguist Typol.
(n.d.) to appear/forthcoming.
- Kaiping GA, Klamer M:
Systematic Bayesian phylogenetics reveal dialect chain breakup in the Timor-Alor-Pantar language family.
OSF.
2019. Publisher Full Text
- Kass RE, Raftery AE:
Bayes factors.
J Am Stat Assoc.
1995; 90(430): 773–795. Publisher Full Text
- Kaufman T:
Language history in South America: what we know and how to know more. In: D. L. Payne (ed.), Amazonian linguistics: studies in Lowland South American languages. Austin: University of Texas Press, 1990; 13–73. Reference Source
- Kolipakam V, Jordan FM, Dunn M, et al.:
A Bayesian phylogenetic study of the Dravidian language family.
R Soc Open Sci.
2018; 5(3): 171504. PubMed Abstract
| Publisher Full Text
| Free Full Text
- List JM:
Sequence comparison in historical linguistics. In: Sequence Comparison in Historical Linguistics. Düsseldorf University Press, 2014. Publisher Full Text
- List JM, Forkel R:
Lingpy. a python library for quantitative tasks in historical linguistics [book library, version 2.6.8]. Leipzig: Max Planck Institute for Evolutionary Anthropology, 2021. Reference Source
- Loukotka C:
La familia lingüística mašakali (estudios de lingüística comparada americana).
Revista del Instituto de etnología de la Universidad nacional de Tucumán.
1932; 2: 21–47.
- Loukotka C:
La familia lingüística coroado.
J Soc Am.
1937; 29(1): 157–214. Reference Source
- Loukotka C:
A língua dos patachos.
Revista Arquivo Municipal.
1939; 55: 5–15. Reference Source
- Loukotka C:
Klassifikation der sudamerikanischen sprachen.
Zeitschrift für Ethnologie.
1942[1944]; 74: 1–69.
- Maddison DR, Swofford DL, Maddison WP:
Nexus: an extensible file format for systematic information.
Syst Biol.
1997; 46(4): 590–621. PubMed Abstract
| Publisher Full Text
- Mason JA:
The languages of South America. In: Julian Steward (ed.), Handbook of South American Indians. (Smithsonian Institution Bureau of American Ethnology Bulletin), chap. 6, Washington: Government Printing Office, 1950; 143. : 157–317.
- Maybury-Lewis D:
Akwe-Shavante society. New York: Oxford University Press, 1974.
- Nikulin A:
Proto-macro-jê: um estudo reconstrutivo. Universidade de Brasília. (Doctoral dissertation), 2020. Reference Source
- Nikulin A, Salanova AP:
Northern Jê verb morphology and the reconstruction of finiteness alternations.
Int J Am Linguist.
2019; 85(4): 533–567. Publisher Full Text
- Nimuendajú C:
Mapa etno-histórico do brasil e regiões adjacentes. Instituto do Patrimônio Histórico e Artístico Nacional (IPHAN) (ed.). 3rd edition. Reprint of the original 1917 map, updated and republished by IPHAN. Brasília, Brazil: IPHAN, 2017. Reference Source
- Noelli FS, De Souza JG:
New perspectives on the archaeological cartography of the jê in Southern Brazil.
Bol Mus Para Emílio Goeldi Cienc Hum.
2017; 12(1). Publisher Full Text
- Parellada CI:
Paisagens transformadas: a arqueologia de povos jê no paraná, sul do Brasil.
Rev Museu Arqueol Etnol.
2016; 27: 158–167. Publisher Full Text
- Perota C:
Sítio monsarás. 1979.
- Pickering WA:
A fonologia xavante: uma revisitação. Universidade estadual de Campinas. (doctoral dissertation), 2010; 256. Reference Source
- Pompei S, Loreto V, Tria F:
On the accuracy of Language Trees.
PLoS One.
2011; 6(6): e20109. PubMed Abstract
| Publisher Full Text
| Free Full Text
- R Core Team:
R: A language and environment for statistical computing. R Foundation for Statistical Computing. Vienna, Austria, 2023. Reference Source
- Rama T, List JM:
An automated framework for fast cognate detection and Bayesian phylogenetic inference in computational historical linguistics. In: Anna Korhonen, David Traum & Lluís Màrquez (eds.), Proceedings of the 57th annual meeting of the Association for Computational Linguistics. Florence, Italy: Association for Computational Linguistics, 2019. Publisher Full Text
- Rambaut A:
Figtree v1.4.4. 2010.
- Ramirez H, Vegini V, de França MCV:
Koropó, puri, kamakã e outras línguas do leste Brasileiro.
LIAMES: Línguas indígenas Americanas.
2015; 15(2): 223–277. Publisher Full Text
- Ribeiro ER:
Prefixos relacionais como evidência históricocomparativa: os casos chiquitano e jabutí.
Línguas e Culturas Macro-Jê.
2011; 2: 105–120. Reference Source
- Ribeiro ER:
A grammar of karajá. University of Chicago. (Doctoral dissertation): 2012; x+291. Reference Source
- Ribeiro ER, van der Voort H:
Nimuendajú was right: the inclusion of the Jabutí language family in the Macro-Jê stock.
International Journal of American Linguistics.
2010; 76(4): 517–570. Publisher Full Text
- Rivet P:
Langues Américaines iii: langues de l’amérique du sud et des antilles. In: Antoine Meillet & Marcel Cohen (eds.), Les langues du monde. Paris: Société Linguistique de Paris, (Coll. Ling. Paris), 1924; 16. : 639–712.
- Robrahn-González EM:
Os grupos ceramistas pré-coloniais do Centro-Oeste brasileiro.
Revista do Museu de Arqueologia e Etnologia.
1996; 6: 83–121. Publisher Full Text
- Rodrigues AD:
Línguas brasileiras: para o conhecimento das línguas indígenas. Edições Loyola, 1986. Reference Source
- Rodrigues AD:
Macro-jê. In: R. M. W. Dixon & A. Aikhenvald (eds.), The Amazonian languages. Cambridge: Cambridge University Press, 1999; 165–206.
- Rodrigues AD:
A case of affinity among Tupí, Karíb and Macro-Jê.
Revista Brasileira de Linguística Antropológica.
2009; 1(1): 139–167. Reference Source
- Russel PM, Brewer BJ, Klaere S, et al.:
Model selection and parameter inference in phylogenetics using nested sampling.
Syst Biol.
2018; 68(2): 219–233. PubMed Abstract
| Publisher Full Text
- Salanova AP:
The Macro-Jê languages. In: Patience Epps & Lev Michael (eds.), Amazonian languages. An international handbook. In preparation. Berlin: Mouton de Gruyter. N.d
- Sand A, Holt MK, Johansen J, et al.:
Tqdist: a library for computing the quartet and triplet distances between binary or general trees.
Bioinformatics.
2014; 30(14): 2079–2080. PubMed Abstract
| Publisher Full Text
- Schmidt W:
Die Sprachfamilien und Sprachenkreise der Erde. Helmut Buske, 1926. Reference Source
- Schmitz PI, Brochado JJP:
Datos para una secuencia cultural del estado de rio grande do sul, Brasil.
Gabinete de Arqueologia Publicações.
1972; 2: 1–20.
- Silva R, Rubin JCR, Viana SA:
Resgate arqueológico: sítios gengibre e lourenço. Universidade Católica de Goiás, 1997.
- Skilling J:
Nested sampling for general bayesian computation.
Bayesian Anal.
2006; 1(4): 833–859. Publisher Full Text
- Smith MR:
Quartet: comparison of phylogenetic trees using quartet and split measures. R package version 1.2.5. 2019. Publisher Full Text
- Stadler T, Kühnert D, Bonhoeffer S, et al.:
Birth–death skyline plot reveals temporal changes of epidemic spread in HIV and hepatitis C virus (HCV).
Proc Natl Acad Sci U S A.
2013; 110(1): 228–233. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Storto L:
Línguas indígenas: tradição, universais e diversidade. Campinas: Mercado de Letras, 2019. Reference Source
- Swadesh M:
The origin and diversification of language: edited post mortem by joel sherzer. Chicago: Aldine, 1971.
- von den Steinen K:
Durch Zentral-Brasilien. Brockhaus, 1886. Reference Source
- Wiesemann U:
The pronoun systems of some Jê and Macro-Jê languages. In: Ursula Wiesemann (ed.), Pronominal systems. Tübingen: Gunther Narr Verlag, 1986; 359–380. Reference Source
- Wüst I:
Continuities and discontinuities: archaeology and ethnoarchaeology in the heart of the Eastern Bororo territory, Mato Grosso, Brazil.
Antiquity.
1998; 72(277): 663–675. Publisher Full Text
- Wüst I, Barreto C:
The ring villages of central Brazil: a challenge for Amazonian archaeology.
Latin American Antiquity.
1999; 10: 3–23. Publisher Full Text









