Introduction
The 3-' untranslated region (3’-UTR) of a messenger RNA (mRNA) molecule is a critical segment located downstream of the coding sequence and plays a pivotal role in gene regulation. Polyadenylation sites (pA sites) are specific locations within the 3’-UTR, where the mRNA undergoes a process known as polyadenylation, resulting in the addition of a poly(A) tail to the pA site. Alternative polyadenylation (Mitschka & Mayr, 2022) refers to the phenomenon in which a single gene possesses multiple pA sites within its 3’-UTR, leading to the production of distinct mRNA isoforms with varying 3’-UTR lengths.
These alternative polyadenylation isoforms can have profound implications for post-transcriptional regulation, as they may influence mRNA localization, stability, and interaction with regulatory factors, thereby affecting the ultimate functional output of the gene. Understanding the mechanisms and consequences of alternative polyadenylation is essential to unravel the complexities of gene expression and its role in diverse biological processes.
We previously developed the software package SCAPE (Zhou et al., 2022) that can estimate alternative polyadenylation events from single-cell RNA-seq (scRNA-seq) data. Because the reads in scRNA-seq are generally not long enough to cover the pA sites, we used a Bayesian mixture model (Figure 1A) to infer the pA sites using the insert length distribution. The mixture model contained k (k > 1) Gaussian components and one uniform component. Each pA site is represented by a Gaussian component, which has three parameters: mean μ, standard deviation δ and weight π. The full SCAPE analysis workflow can be summarized into the following steps: (1) extract the 3’-UTR annotation from the General Transfer Format (GTF) or General Feature Format (GFF) file; (2) map the reads to the reference genome and calculate the relative positions of reads on the corresponding 3’-UTR regions; (3) perform parameter inference for each 3’-UTR region and output the result; and (4) perform downstream tasks such as differential pA site usage analysis.
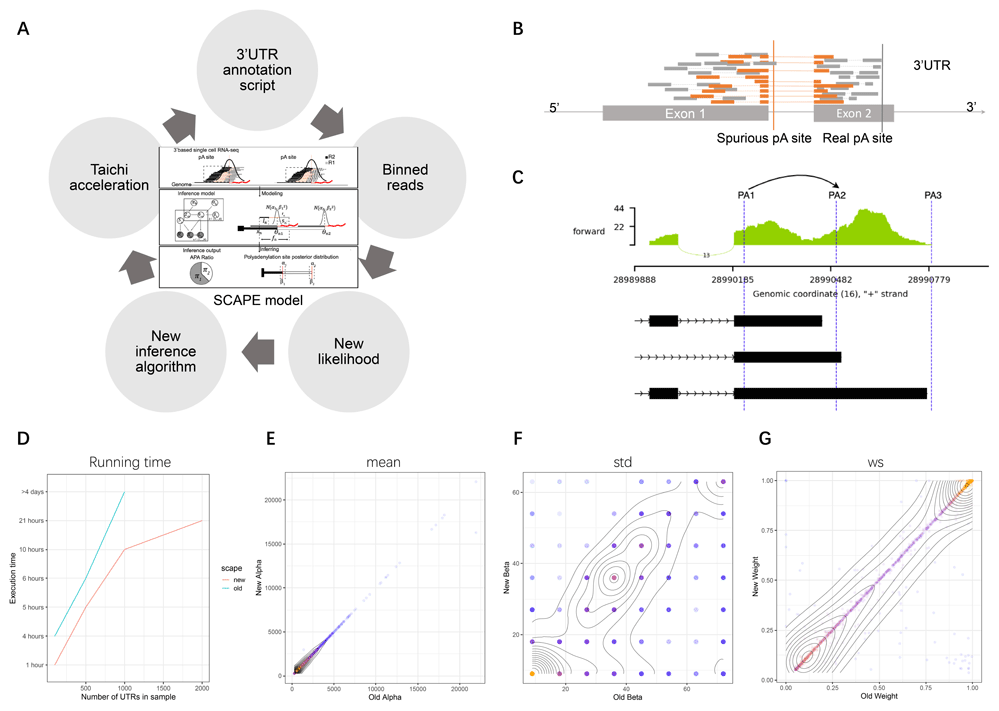
Figure 1.
(A) Original SCAPE model and improvements of SCAPE-APA. (B) Schematic illustration of a spurious pA site due to splicing of 3’-UTR. (C) A real spurious pA site case. PA1 is the spurious pA site and should be merged into PA2. (D) Comparison of running time on the same computer across different datasets. (E–G) Comparison of estimated mean, std and weight of estimated pA sites. The curves are the density contour of data points.
Methods
Improvements
We made significant updates to the previous implementation, as shown in Figure 1A. The biggest challenge in real data analysis is that the read number can be very large (n > 200,000) for some 3’-UTRs. This makes the original inference algorithm extremely slow. As the 3’-UTR is relatively short (~1500bp), there are many redundant reads. To solve this problem, we binned reads in the vicinity, that is, reads with similar x, l, r values in the following likelihood.
Note that the bin is 3-dimensional. The nth bin was denoted by the unique combination (xn, ln, rn) and its count by cn, where the bin sizes were set to 5bp, 10bp, 10bp, respectively. The joint likelihood of the mixture model can be rewritten as:
It can be seen that we only need to calculate the likelihood once for all cn reads in the nth bin in the new likelihood, whereas this has to be repeated cn times in the original likelihood. As the likelihood changes, the inference algorithm must be modified accordingly. The detailed mathematical derivations of the inference algorithm for the new likelihood are provided in Supplementary Note 1. To further accelerate the inference, we used the Taichi language (Hu et al., 2019) to re-implement the inference algorithm, where Taichi used the just-in-time (JIT) compilation to accelerate the Python code. Because the inference algorithm is serial, the computation times are similar, regardless of whether the GPU is used.
In addition to the new likelihood and inference algorithm, we re-implemented and added new bioinformatics functionalities to streamline the workflow. We re-wrote the Python script to extract 3’-UTR annotations from GTF or GFF files based on the package “gffutils” (https://github.com/daer/gffutils), which was easier to maintain than the previous ad hoc implementation. We added a post-processing script to handle spurious pA sites owing to the junction reads. As shown in Figure 1B, some 3’-UTR may contain multiple exons/fragments, while the SCAPE model assumes the 3’-UTR to be a consecutive region on the genome, that is, we take the start of the first exon/fragment and the end of the last exon/fragment as the full 3’-UTR region. Because of this multi-segment property of the given 3’-UTR in Figure 1B, two pA sites were estimated from the data, where the orange pA site was the spurious pA site. To resolve this, we merged a pA site with the next downstream pA site if there were > 40% junction reads in all reads assigned to this pA site. Figure 1C shows a spurious pA site case in the real data, where the first estimated pA site should be merged with the second. Finally, we made a python package “scape-apa” and uploaded it to the Python Package Index (PyPI) to facilitate the installation.
We compared the speed and inference results of the old and new SCAPE software by sampling 100, 500, 1000, and 2000 3’-UTRs from public scRNA-seq data (Notaras et al., 2022). Figure 1D shows the running times for the analyses of these datasets on a CPU-only computer (Dell PowerEdge C4130), with the maximum memory set to 10GB. It can be seen that the speedup is 9-fold for the dataset with 1000 3’-UTRs. Figure 1E–G shows the estimated mean, std, and weights given by the old and new SCAPE packages of the dataset with 1000 3’-UTR. We fixed the number of pA sites in each UTR based on the results of the new package. It can be seen that the majority of the data points are scattered around the y = x line for the mean and weight, whereas a larger variation is observed for the standard deviation. These differences are due to the binning operation; however, the overall comparisons suggest a highly consistent result between the old and new packages.
In summary, we revised the statistical model for binned reads and utilized Taichi to accelerate the parameter inference of SCAPE, as well as developed useful Python scripts to process GTF files and handle spurious pA sites.
Implementation
The SCAPE-APA package has five main modules:
utils.py: This module processes GFF files from the Ensembl database into 3’-UTR annotations using the dedicated APIs of gffutils. If no 3’-UTR annotation is available for a gene, the last exon is used as its 3’-UTR.
input_processor.py: This module extracts relevant information from the input BAM files for APA event estimation. This includes variables such as x, l, r in the SCAPE model, as well as cell barcode, UMI, and junction read information.
apa_core.py: This module contains the core inference algorithm of the SCAPE model. The ApaModel class implements the core functionality, holding the parameters and results for the model. Its run() function gathers all relevant components for the inference algorithm. Details of the statistical model and inference algorithm are provided in Supplementary Note 1.
taichi_core.py: This module provides equivalent implementations of relevant functions from the inference algorithm using the Taichi language. Since Taichi is a static language, all memory for inputs and outputs must be pre-allocated before calling a Taichi function. These functions are imported by the apa_core.py module to perform the actual inference.
junction_handler.py: This module merges spurious pA sites that arise due to junction reads. If more than 40% of the reads assigned to a given pA site are junction reads, the site is labeled as spurious and merged with the next pA site.
Operation
SCAPE-APA can be installed on Linux, Mac, and Windows systems with Python 3.11 or higher. A GPU is not required to run SCAPE-APA. The basic workflow consists of five steps:
1. Generate the 3’-UTR annotation file using the “scape gen_utr_annotation” command. The input file of this step is GFF3 file of suitable genomes downloaded from Ensembl database.
2. Prepare the input files using the “scape prepare_input” command. The 3’-UTR annotation file from step 1 and the BAM file from the scRNA-seq experiment are the inputs for this step.
3. Perform pA site inference using the “scape infer_pa” command.
4. Remove spurious pA sites caused by junction reads using the “scape merge_pa” command.
5. Extract the pA count matrix using the “scape ex_pa_cnt_mat” command. The rows represent cells, and the columns represent the estimated pA sites. The pA count matrix can be fed into Seurat for differential analysis.
Discussion
Since 2019, the scale of scRNA-seq data has expanded dramatically, growing from datasets with thousands of cells to those containing millions in 2024. This surge in data volume has highlighted the limitations of the original SCAPE tool, which was not equipped to handle such large datasets. In fact, the original SCAPE was extremely slow, sometimes taking weeks to analyze a single dataset with just thousands of cells. Moreover, it contained several bugs that compromised its performance, and the reliance on ad-hoc Python scripts made maintenance difficult, especially as databases like Ensembl regularly update their annotations. Using a dedicated API to extract 3’-UTR annotations is a far more robust and reliable solution for long-term sustainability.
SCAPE-APA was developed to address these critical issues. It offers substantial improvements in speed, reliability, and maintainability, making it far better suited for the analysis of large-scale scRNA-seq datasets. By incorporating modern bioinformatic tools and creating a formal Python package, SCAPE-APA enables faster and more efficient analysis while reducing maintenance challenges. This updated version will be an invaluable tool for researchers, capable of handling the increasingly large and complex datasets in single-cell RNA sequencing, ensuring that SCAPE-APA meets the growing demands of the field.
Ethics and consent
Ethical approval and consent not required
Author contribution
G. C. developed an inference algorithm for binned reads and implemented it in Taichi. T. L. developed Python scripts for parsing the GTF file, removing spurious pA sites, and ran benchmark experiments. R. Z. provided advice regarding the 3’-UTR annotation extraction. L. C. supervised the project.
Acknowledgements
GC, TL, and LC acknowledge the computational resources provided by the Aalto Science-IT project and the CSC – IT Center for Science, Finland.
Faculty Opinions recommendedReferences
- Hu Y, Li TM, Anderson L, et al.:
Taichi: a language for high-performance computation on spatially sparse data structures.
ACM Trans Graph.
2019; 38(6): 1–16. Publisher Full Text
- Mitschka S, Mayr C:
Context-specific regulation and function of mRNA alternative polyadenylation.
Nat Rev Mol Cell Biol.
2022; 23(12): 779–96. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Notaras M, Lodhi A, Dündar F, et al.:
Schizophrenia is defined by cell-specific neuropathology and multiple neurodevelopmental mechanisms in patient-derived cerebral organoids.
Mol Psychiatry.
2022; 27(3): 1416–34. PubMed Abstract
| Publisher Full Text
| Free Full Text
- Zhou R, Xiao X, He P, et al.:
SCAPE: a mixture model revealing single-cell polyadenylation diversity and cellular dynamics during cell differentiation and reprogramming.
Nucleic Acids Res.
2022; 50(11): e66. PubMed Abstract
| Publisher Full Text
| Free Full Text